# yikZero
> Personal site of yikZero (ooo.ro). Canonical domain: https://ro.yikzero.com. Default locale is zh-CN at `/`; English is at `/en/`.
yikZero (Zhang Yiji) is a Product Manager at OneKey.
Every page has a Markdown twin at the same path plus `.md`, served as `text/markdown`: `/index.md` and `/en.md` for the homepages, `/blog/{slug}.md` for posts. Request those paths directly; the HTML URLs do not negotiate on `Accept`.
This is a personal blog, not a public HTTP API. There is no OpenAPI spec, OAuth flow, webhook catalog, or MCP server. Developer-facing work lives in GitHub skills linked below.
## Site
- [yikZero home (zh-CN)](https://ro.yikzero.com/index.md): yikZero 的个人主页,记录 AI 工具、Web3 产品与工作流实践。
- [yikZero home (en)](https://ro.yikzero.com/en.md): The personal site of yikZero, covering AI tools, Web3 products, and workflows.
- [llms-full.txt](https://ro.yikzero.com/llms-full.txt): Concatenated Markdown of the homepages and every published post.
- [RSS (zh-CN)](https://ro.yikzero.com/rss.xml): Published Chinese posts.
- [RSS (en)](https://ro.yikzero.com/en/rss.xml): Published English posts.
- [Sitemap](https://ro.yikzero.com/sitemap-index.xml): Index of public HTML pages.
## Writing
- [借助 Claude 实现 AI 翻译功能的工程化验证 (zh-CN)](https://ro.yikzero.com/blog/ai-translate-demo.md): 快速搭建 AI 翻译 Demo,验证并发请求、JSON 流式输出等优化策略,降低翻译耗时
- [Lokalise MCP 自动翻译方案 (zh-CN)](https://ro.yikzero.com/blog/lokalise-mcp.md): 工作中需国际化的场景比较多,需要有自动化翻译方案来提高效率
- [告别选片困扰:用 AI 打造个性观影榜单 (zh-CN)](https://ro.yikzero.com/blog/watch-this.md): 本文介绍如何借助 AI 强大的数据分析能力,整合多个影视榜单,为你总结生成一份每周热门观影清单
- [从产品设计师角度,聊聊博客搭建方法 (zh-CN)](https://ro.yikzero.com/blog/roominess-develop.md): 网站也已经改版一段时间了,内容模块也相对完善。所以这次,从设计到开发,我也想讲讲自己的经验
- [人工智能时代的视觉交互新范式 (zh-CN)](https://ro.yikzero.com/blog/ai-ui-future.md): 探讨了人工智能时代视觉交互的新范式,包括硬件和软件两个方面的创新
- [UI 设计模块化研究:图标篇 (zh-CN)](https://ro.yikzero.com/blog/icon-learn.md): 全面介绍了 UI 设计中图标的重要性及其应用
- [Next.js 调用 Notion API 记录 (zh-CN)](https://ro.yikzero.com/blog/brogbuild-1.md): 使用 Next.js 调用 Notion API 构建博客时的开发记录,包含数据获取、图片优化和样式渲染等踩坑经验
- [HomeLab 家庭环境配置 (zh-CN)](https://ro.yikzero.com/blog/homelab-config.md): 记录光猫、R4S 软路由和 Linksys 硬路由的配置
- [R4S 安装 Plex 服务端记录 (zh-CN)](https://ro.yikzero.com/blog/plex-server-1.md): 在 R4S 软路由上安装 Plex 媒体服务器的完整记录,解决架构兼容、远程访问和端口转发等问题
- [Hugo 折腾记录:从 0 到 1 (zh-CN)](https://ro.yikzero.com/blog/hugo-build-1.md): 从零搭建 Hugo 博客的完整过程,涵盖安装配置、页面结构和 CSS 布局技巧
- [IFTTT 自动化推送通知 (zh-CN)](https://ro.yikzero.com/blog/ifttt-1.md): 利用 IFTTT 实现学校通知推送到微信、邮箱等
- [PN532 模拟校园卡 (zh-CN)](https://ro.yikzero.com/blog/pn532-1.md): 通过 PN532 设备解析校园卡数据并写入 CUID 空白卡,实现门禁和消费功能的完整教程
- [寝室 WiFi 共享:突破校园网限制 (zh-CN)](https://ro.yikzero.com/blog/dorm-router.md): 本文介绍如何通过刷入第三方固件(如老毛子固件),配置L2TP,突破学校(以屏峰校区移动宽带为例)的一人一号网络限制,实现在寝室共享 WiFi。
- [Aria2 下载完毕自动邮件通知 (zh-CN)](https://ro.yikzero.com/blog/aria2-1.md): 为 Aria2 配置下载完成后的自动邮件通知,通过 sendmail 和自定义脚本发送包含文件路径和系统信息的通知
- [Validating an AI Translation Feature with Claude (en)](https://ro.yikzero.com/en/blog/ai-translate-demo.md): Quickly build an AI translation demo to validate optimization strategies such as concurrent requests and streaming JSON output, reducing translation latency.
- [Automated Translation with Lokalise MCP (en)](https://ro.yikzero.com/en/blog/lokalise-mcp.md): There are many scenarios at work that require internationalization, so an automated translation solution is needed to improve efficiency.
- [Building a Personalized Watchlist with AI (en)](https://ro.yikzero.com/en/blog/watch-this.md): This article explains how to leverage AI’s powerful data analysis capabilities to integrate multiple film and TV rankings and generate a weekly list of popular titles to watch.
- [Building a Blog from a Product Designer’s Perspective (en)](https://ro.yikzero.com/en/blog/roominess-develop.md): The website has been redesigned for a while now, and the content modules are relatively complete. So this time, I’d like to share some of my own experience, from design to development.
- [New Paradigms for Visual Interaction in the Age of AI (en)](https://ro.yikzero.com/en/blog/ai-ui-future.md): Explores new paradigms in visual interaction in the era of artificial intelligence, including innovations in both hardware and software.
- [A Study of Modular UI Design: Icons (en)](https://ro.yikzero.com/en/blog/icon-learn.md): A comprehensive introduction to the importance and application of icons in UI design
- [Notes on Calling the Notion API with Next.js (en)](https://ro.yikzero.com/en/blog/brogbuild-1.md): Development notes on building a blog with Next.js and the Notion API, covering lessons learned from data fetching, image optimization, style rendering, and more.
- [HomeLab Environment Setup (en)](https://ro.yikzero.com/en/blog/homelab-config.md): Documenting the configuration of the optical modem, R4S software router, and Linksys hardware router
- [Installing Plex Server on R4S: Notes (en)](https://ro.yikzero.com/en/blog/plex-server-1.md): A Complete Record of Installing Plex Media Server on an R4S Software Router, Solving Issues Such as Architecture Compatibility, Remote Access, and Port Forwarding
- [Hugo Setup Notes: From Zero to One (en)](https://ro.yikzero.com/en/blog/hugo-build-1.md): The Complete Process of Building a Hugo Blog from Scratch, Covering Installation and Configuration, Page Structure, and CSS Layout Tips
- [Automated Push Notifications with IFTTT (en)](https://ro.yikzero.com/en/blog/ifttt-1.md): Using IFTTT to Push School Notifications to WeChat, Email, and More
- [Emulating a Campus Card with PN532 (en)](https://ro.yikzero.com/en/blog/pn532-1.md): A Complete Tutorial on Using a PN532 Device to Parse Campus Card Data and Write It to a Blank CUID Card, Enabling Access Control and Payment Functions
- [Sharing Dorm WiFi: Bypassing Campus Network Restrictions (en)](https://ro.yikzero.com/en/blog/dorm-router.md): This article explains how to flash third-party firmware (such as Padavan firmware) and configure L2TP to bypass the school’s one-account-per-person network restriction (using China Mobile broadband at the Pingfeng campus as an example), enabling shared WiFi in the dormitory.
- [Sending Email Notifications When Aria2 Downloads Complete (en)](https://ro.yikzero.com/en/blog/aria2-1.md): Configure automatic email notifications after Aria2 downloads complete, sending notifications that include the file path and system information via sendmail and a custom script.
## Developer resources
- [Project Bootstrap](https://github.com/yikZero/skills/tree/main/skills/project-bootstrap): Turns a product idea into a ready-to-build repo with docs, tooling, validation, and agent workflow.
- [Pi Coding Agent SDK](https://github.com/yikZero/skills/tree/main/skills/pi-coding-agent-sdk): Embeds coding-agent sessions in TypeScript apps, covering runtime flows, tools, skills, resources, and events.
- [yikZero GitHub](https://github.com/yikZero): Source for skills, this site, and other public work by yikZero.
## Optional
- [robots.txt](https://ro.yikzero.com/robots.txt): Crawl policy and sitemap pointer.
- [404 guide](https://ro.yikzero.com/404.md): Recovery links when a path does not exist.
---
---
title: "yikZero - AI 工具、Web3 与产品实践"
canonical_url: https://ro.yikzero.com/
locale: zh-CN
---
# yikZero
> yikZero 的个人主页,记录 AI 工具、Web3 产品与工作流实践。
你好,我是 yikZero,也叫张毅吉,现居杭州,目前在 OneKey 做 Web3 产品。
最近在做 Grok Ally 这个新工具,也在用 Grok Bot 这个新 App,持续参与日常协作和具体任务。欢迎通过 Gmail (yikZero) 和我交流。
yikZero publishes this site as **ooo.ro** at https://ro.yikzero.com. Posts are written in `zh-CN` and `en`.
## 项目
- [OneKey](https://onekey.so/download/): 交易一切,掌控一切
## 文章
- [借助 Claude 实现 AI 翻译功能的工程化验证](https://ro.yikzero.com/blog/ai-translate-demo.md): 快速搭建 AI 翻译 Demo,验证并发请求、JSON 流式输出等优化策略,降低翻译耗时
- [Lokalise MCP 自动翻译方案](https://ro.yikzero.com/blog/lokalise-mcp.md): 工作中需国际化的场景比较多,需要有自动化翻译方案来提高效率
- [告别选片困扰:用 AI 打造个性观影榜单](https://ro.yikzero.com/blog/watch-this.md): 本文介绍如何借助 AI 强大的数据分析能力,整合多个影视榜单,为你总结生成一份每周热门观影清单
- [从产品设计师角度,聊聊博客搭建方法](https://ro.yikzero.com/blog/roominess-develop.md): 网站也已经改版一段时间了,内容模块也相对完善。所以这次,从设计到开发,我也想讲讲自己的经验
- [人工智能时代的视觉交互新范式](https://ro.yikzero.com/blog/ai-ui-future.md): 探讨了人工智能时代视觉交互的新范式,包括硬件和软件两个方面的创新
- [UI 设计模块化研究:图标篇](https://ro.yikzero.com/blog/icon-learn.md): 全面介绍了 UI 设计中图标的重要性及其应用
- [Next.js 调用 Notion API 记录](https://ro.yikzero.com/blog/brogbuild-1.md): 使用 Next.js 调用 Notion API 构建博客时的开发记录,包含数据获取、图片优化和样式渲染等踩坑经验
- [HomeLab 家庭环境配置](https://ro.yikzero.com/blog/homelab-config.md): 记录光猫、R4S 软路由和 Linksys 硬路由的配置
- [R4S 安装 Plex 服务端记录](https://ro.yikzero.com/blog/plex-server-1.md): 在 R4S 软路由上安装 Plex 媒体服务器的完整记录,解决架构兼容、远程访问和端口转发等问题
- [Hugo 折腾记录:从 0 到 1](https://ro.yikzero.com/blog/hugo-build-1.md): 从零搭建 Hugo 博客的完整过程,涵盖安装配置、页面结构和 CSS 布局技巧
- [IFTTT 自动化推送通知](https://ro.yikzero.com/blog/ifttt-1.md): 利用 IFTTT 实现学校通知推送到微信、邮箱等
- [PN532 模拟校园卡](https://ro.yikzero.com/blog/pn532-1.md): 通过 PN532 设备解析校园卡数据并写入 CUID 空白卡,实现门禁和消费功能的完整教程
- [寝室 WiFi 共享:突破校园网限制](https://ro.yikzero.com/blog/dorm-router.md): 本文介绍如何通过刷入第三方固件(如老毛子固件),配置L2TP,突破学校(以屏峰校区移动宽带为例)的一人一号网络限制,实现在寝室共享 WiFi。
- [Aria2 下载完毕自动邮件通知](https://ro.yikzero.com/blog/aria2-1.md): 为 Aria2 配置下载完成后的自动邮件通知,通过 sendmail 和自定义脚本发送包含文件路径和系统信息的通知
## Skills
- [Project Bootstrap](https://github.com/yikZero/skills/tree/main/skills/project-bootstrap): 把产品想法整理成项目基线,连同文档、验证命令和协作规则一起搭好
- [Pi Coding Agent SDK](https://github.com/yikZero/skills/tree/main/skills/pi-coding-agent-sdk): 把编码 Agent 嵌入 TypeScript 应用,处理会话管理、工具扩展、资源加载和事件流
## 工作流
- [Codex](https://openai.com/codex/): 主力编码 Agent,负责实际改动、验证和交付
- [Conductor](https://www.conductor.build/): 管理并行任务和多个 worktree
- [Typeless](https://www.typeless.com/): 沟通想法时少打字,靠对话把想法输出出来
## 机器可读
- [llms.txt](https://ro.yikzero.com/llms.txt): 给 Agent 用的站点 Markdown 地图。
- [llms-full.txt](https://ro.yikzero.com/llms-full.txt): 首页和全部已发布文章的完整 Markdown。
- [RSS](https://ro.yikzero.com/rss.xml): 当前语言的已发布文章。
- [Sitemap](https://ro.yikzero.com/sitemap-index.xml): 公开 HTML 页面索引。
Markdown URL: https://ro.yikzero.com/index.md
---
---
title: "yikZero - AI Tools, Web3 & Product Craft"
canonical_url: https://ro.yikzero.com/en/
locale: en
---
# yikZero
> The personal site of yikZero, covering AI tools, Web3 products, and workflows.
Hi, I'm yikZero, also known as Zhang Yiji, a Product Manager currently working on Web3 products at OneKey.
I'm building Grok Ally, a new tool of mine, and I've been using Grok Bot, a new app, to keep participating in everyday collaboration and real tasks. Feel free to reach out via Gmail (yikZero).
yikZero publishes this site as **ooo.ro** at https://ro.yikzero.com. Posts are written in `zh-CN` and `en`.
## Projects
- [OneKey](https://onekey.so/download/): Trade everything, own everything.
## Writing
- [Validating an AI Translation Feature with Claude](https://ro.yikzero.com/en/blog/ai-translate-demo.md): Quickly build an AI translation demo to validate optimization strategies such as concurrent requests and streaming JSON output, reducing translation latency.
- [Automated Translation with Lokalise MCP](https://ro.yikzero.com/en/blog/lokalise-mcp.md): There are many scenarios at work that require internationalization, so an automated translation solution is needed to improve efficiency.
- [Building a Personalized Watchlist with AI](https://ro.yikzero.com/en/blog/watch-this.md): This article explains how to leverage AI’s powerful data analysis capabilities to integrate multiple film and TV rankings and generate a weekly list of popular titles to watch.
- [Building a Blog from a Product Designer’s Perspective](https://ro.yikzero.com/en/blog/roominess-develop.md): The website has been redesigned for a while now, and the content modules are relatively complete. So this time, I’d like to share some of my own experience, from design to development.
- [New Paradigms for Visual Interaction in the Age of AI](https://ro.yikzero.com/en/blog/ai-ui-future.md): Explores new paradigms in visual interaction in the era of artificial intelligence, including innovations in both hardware and software.
- [A Study of Modular UI Design: Icons](https://ro.yikzero.com/en/blog/icon-learn.md): A comprehensive introduction to the importance and application of icons in UI design
- [Notes on Calling the Notion API with Next.js](https://ro.yikzero.com/en/blog/brogbuild-1.md): Development notes on building a blog with Next.js and the Notion API, covering lessons learned from data fetching, image optimization, style rendering, and more.
- [HomeLab Environment Setup](https://ro.yikzero.com/en/blog/homelab-config.md): Documenting the configuration of the optical modem, R4S software router, and Linksys hardware router
- [Installing Plex Server on R4S: Notes](https://ro.yikzero.com/en/blog/plex-server-1.md): A Complete Record of Installing Plex Media Server on an R4S Software Router, Solving Issues Such as Architecture Compatibility, Remote Access, and Port Forwarding
- [Hugo Setup Notes: From Zero to One](https://ro.yikzero.com/en/blog/hugo-build-1.md): The Complete Process of Building a Hugo Blog from Scratch, Covering Installation and Configuration, Page Structure, and CSS Layout Tips
- [Automated Push Notifications with IFTTT](https://ro.yikzero.com/en/blog/ifttt-1.md): Using IFTTT to Push School Notifications to WeChat, Email, and More
- [Emulating a Campus Card with PN532](https://ro.yikzero.com/en/blog/pn532-1.md): A Complete Tutorial on Using a PN532 Device to Parse Campus Card Data and Write It to a Blank CUID Card, Enabling Access Control and Payment Functions
- [Sharing Dorm WiFi: Bypassing Campus Network Restrictions](https://ro.yikzero.com/en/blog/dorm-router.md): This article explains how to flash third-party firmware (such as Padavan firmware) and configure L2TP to bypass the school’s one-account-per-person network restriction (using China Mobile broadband at the Pingfeng campus as an example), enabling shared WiFi in the dormitory.
- [Sending Email Notifications When Aria2 Downloads Complete](https://ro.yikzero.com/en/blog/aria2-1.md): Configure automatic email notifications after Aria2 downloads complete, sending notifications that include the file path and system information via sendmail and a custom script.
## Skills
- [Project Bootstrap](https://github.com/yikZero/skills/tree/main/skills/project-bootstrap): Turns a product idea into a ready-to-build repo with docs, tooling, validation, and agent workflow.
- [Pi Coding Agent SDK](https://github.com/yikZero/skills/tree/main/skills/pi-coding-agent-sdk): Embeds coding-agent sessions in TypeScript apps, covering runtime flows, tools, skills, resources, and events.
## Workflow
- [Codex](https://openai.com/codex/): Primary coding agent for real changes, verification, and delivery.
- [Conductor](https://www.conductor.build/): Manages parallel tasks and multiple worktrees.
- [Typeless](https://www.typeless.com/): Turns idea capture into conversation instead of typing.
## Machine-readable
- [llms.txt](https://ro.yikzero.com/llms.txt): Curated Markdown map for agents.
- [llms-full.txt](https://ro.yikzero.com/llms-full.txt): Concatenated Markdown of the homepages and every published post.
- [RSS](https://ro.yikzero.com/en/rss.xml): Published posts for this locale.
- [Sitemap](https://ro.yikzero.com/sitemap-index.xml): Index of public HTML pages.
Markdown URL: https://ro.yikzero.com/en.md
---
---
title: "借助 Claude 实现 AI 翻译功能的工程化验证"
description: "快速搭建 AI 翻译 Demo,验证并发请求、JSON 流式输出等优化策略,降低翻译耗时"
canonical_url: https://ro.yikzero.com/blog/ai-translate-demo/
locale: zh-CN
date: 2026-01-23
---
# 借助 Claude 实现 AI 翻译功能的工程化验证
在需求阶段通过 Demo 快速验证,有助于明确功能实现效果并指导后续优化。
最近在做 AI 翻译的需求,想知道 AI 翻译有哪些限制?哪家模型效果最好、速度最快?以往或许只能体验竞品,但现在我们可以借助 Claude 来快速起一个 Demo 来验证想法。
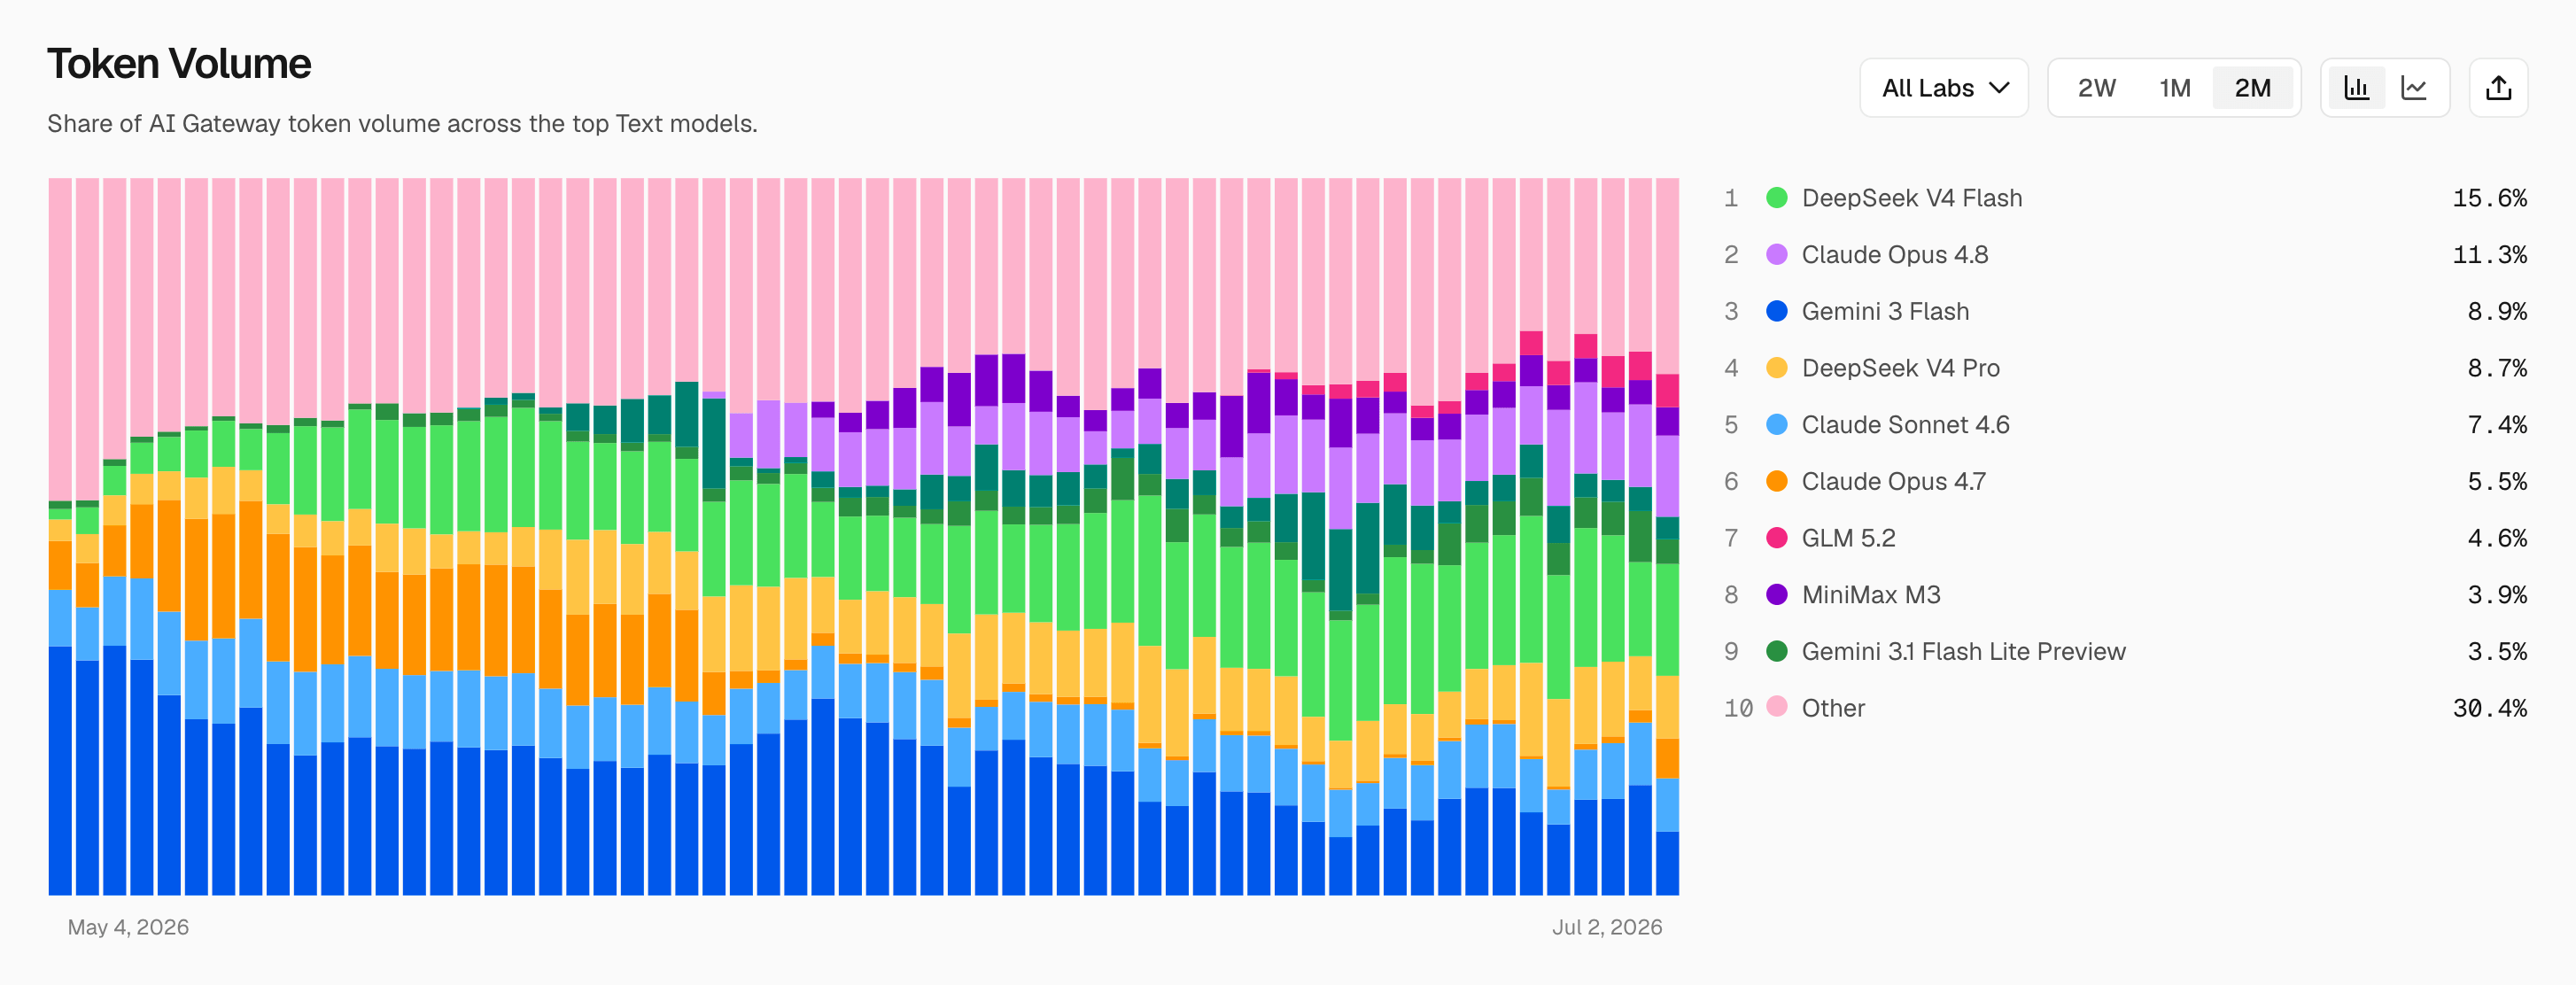
模型选择上,我的第一步不是直接盲测,而是先看 [OpenRouter Rankings](https://openrouter.ai/rankings) 和 [Vercel AI Gateway Leaderboards](https://vercel.com/ai-gateway/leaderboards/models) 这类榜单,了解当下大家调用较多、讨论较多的模型,先形成一个候选池。不过这类榜单只能提供初步共识,模型调用量也可能受价格、活动、刷量或特定场景影响,最终还是要回到自己的文本类型、语言方向、速度要求和成本约束里做验证。
同时,我也借助这个 Demo 对 AI 翻译的速度、效果进行了优化,为开发提供了初步的经验和实践,更有利于后期规划。
[Video](https://cdn.yikzero.com/markdown/images/Demo.mp4)
在这个 Demo 中,翻译架构经历了从串行,到并发请求,再到多段 JSON 稳定输出,最终演进为 JSON 流式输出的完整迭代。
这一改动将长文翻译的整体耗时从最初的 26s 大幅缩减至 2.7s 左右。尽管在绝对速度上与传统引擎仍有差距,但配合多 Key 轮询及缓存机制,体验已完全具备进一步提升的空间。
此外,经过反复测试,我也摸索出了一套兼顾效果与稳定性的参数组合。
想要了解具体的问题和解决方案,请继续往下看:
## 核心工程化优化
为了解决 AI 翻译天生「慢」和容易「幻觉」的问题,我在 Demo 代码中进行了三个方向的策略验证:
### 1. 响应体验:并发限制优化
目前而言,选用快速模型可以提升一定的速度,但相较于传统翻译,肯定是有差距的。所以我尝试优化了请求逻辑,兼顾模型速度与并发限制的情况下,给大家带来一个比较好的翻译体验:
并发请求,这是大家肯定能够想到的第一步行动,没错,这对于翻译速度的提升还是挺大的。
经过优化,相同文本的耗时从 24s 降到了 6s,提升确实肉眼可见。但这相比传统翻译的 1s,差距依然无法忽视。
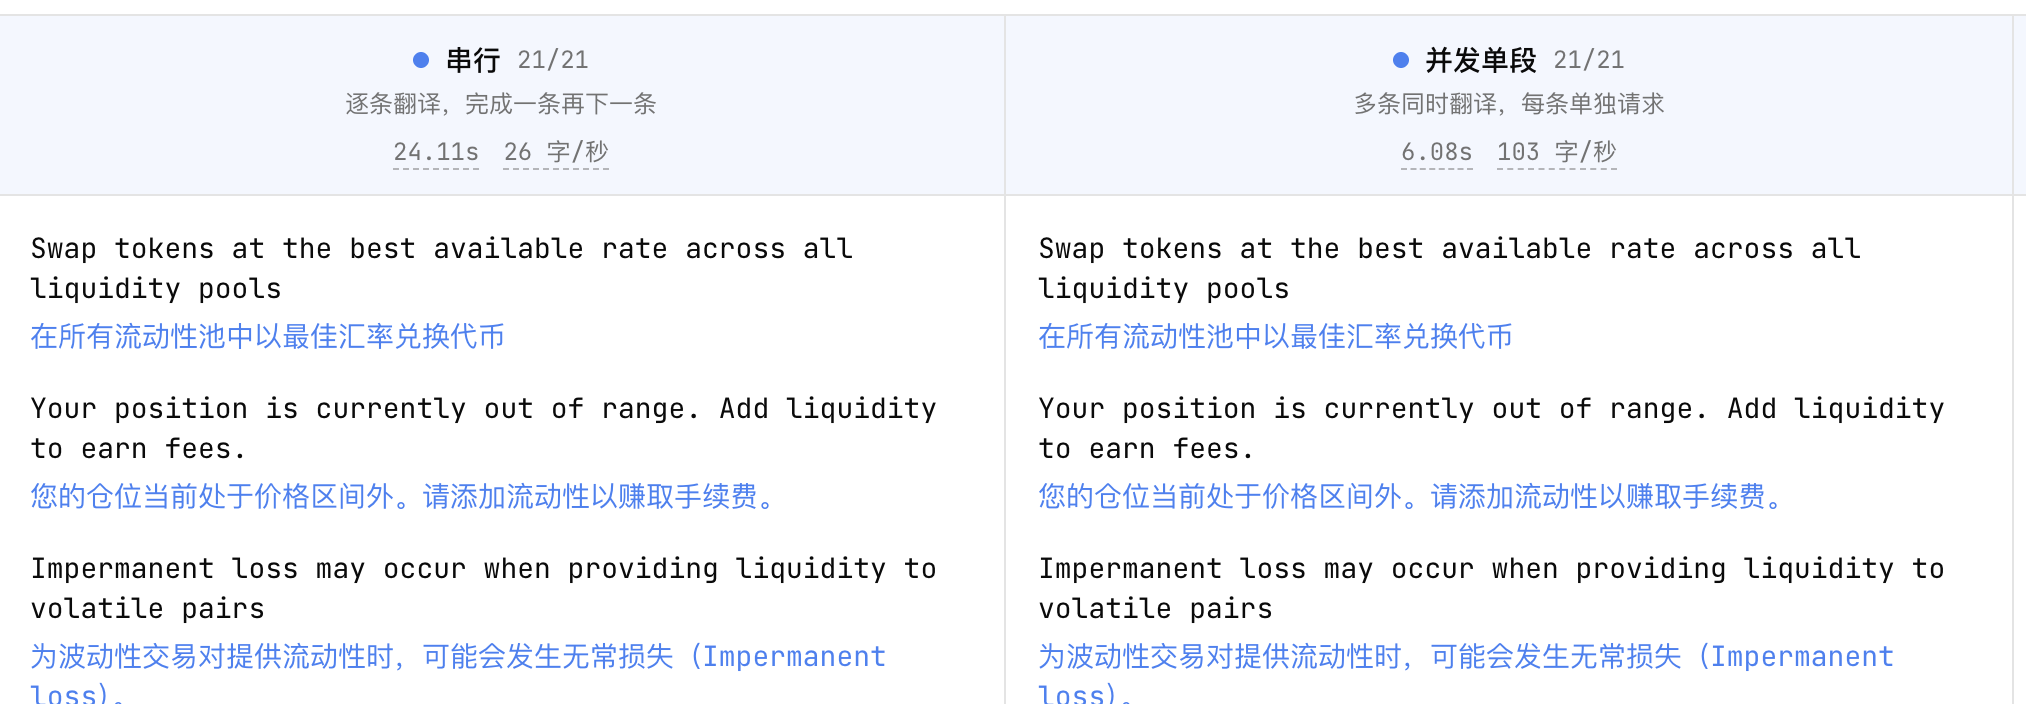
还能不能更快?答案是肯定的。简单并发解决了「同时发多个请求」的问题,但本质上仍是一段文本一次模型调用。既然模型支持长上下文,更合适的做法是在 Token 限制内把多段文本合并成一次请求,让单次调用吞吐更多内容。
这时真正需要处理的是结果对齐:多段内容一起发出去,返回时必须准确回填到原来的段落。因此输入侧给每段文本加上稳定的 `id`,输出侧要求结构化结果,就能按 `id` 对应回源文本,避免乱序或漏段。
如果直接返回完整 JSON 数组,前端通常还要等最后的 `]` 才能稳定解析。现在可以把这层交给 [Vercel AI SDK](https://ai-sdk.dev/docs/ai-sdk-core/generating-structured-data):用 schema 约束输出结构,并通过 `partialOutputStream` 获取生成中的 partial object。业务侧只需要监听 partial 更新,再按 `id` 渐进回填对应段落。
```ts
import { Output, streamText } from 'ai';
import { z } from 'zod';
const result = streamText({
model,
output: Output.object({
schema: z.object({
translations: z.record(z.string(), z.string()),
}),
}),
system: 'Translate each item and keep the same id.',
prompt: JSON.stringify({
1: 'Swap tokens...',
2: 'Your position...',
3: 'Slippage tolerance...',
}),
});
for await (const partial of result.partialOutputStream) {
for (const [id, translation] of Object.entries(partial.translations ?? {})) {
updateTranslation(id, translation);
}
}
```
这类能力后续大概率不需要业务侧从零实现。Demo 阶段更重要的是验证产品链路和交互效果,而不是维护一套自定义 JSON 流式解析逻辑。
经过这一轮优化之后,AI 翻译耗时从 6.08s 降低至 2.88s。
[Video](https://cdn.yikzero.com/markdown/images/Speed_Comparison_h264.mp4)
对于 AI 翻译速度的优化就是这些,配合服务端后期可以做的多 Key 轮询以及翻译缓存,体验会进一步提升。
### 2. 翻译质量:Prompt 调优与术语保护
参考了沉浸式翻译的 Web3 领域翻译提示词,明确了输出规范。要求保留专业术语(如 ETH, Gas fee 等),还通过带索引的输入格式(`[1] text... [2] text...`)确保了批量翻译时的输出顺序一致,避免了多段乱序的问题。
```javascript
You are a professional ${targetLang} native translator specialized in Web3 and blockchain content.
## Translation Rules
1. Output only the translated content, without explanations or additional text
2. Maintain all blockchain terminology, cryptocurrency names, and token symbols
in their original form (e.g., ETH, BTC, USDT, Solana, Ethereum)
3. Preserve technical Web3 concepts with commonly accepted translations:
DeFi, NFT, DAO, DEX, CEX, AMM, TVL, APY, APR, gas fee, smart contract,
wallet, staking, yield farming, liquidity pool
4. Keep all addresses, transaction hashes, and code snippets exactly as in the original
5. Translate from ${sourceLang} to ${targetLang} while preserving technical meaning
6. Ensure fluent, natural expression in ${targetLang} while maintaining technical accuracy
```
### 3. 参数控制
虽然需求阶段尚未正式开发,但我在 Demo 层面预演了未来的控制逻辑,主要包含两个维度:
#### Token 限制与智能分块
根据调试的效果,对同一请求的段数以及字数长度进行了一定的控制:
- **Temperature = 0** - 确定性输出,结果更稳定
- **控制段落数(4 段)** - 避免单次请求过大导致超时
- **请求最大文本字符(3,000)** - 兼顾输出速度与内容长度
#### 思考模式限制
针对 Gemini 3.0 Flash 等具备思考能力的模型,在翻译这种明确任务中,调整 `thinkingLevel` 也可以提升翻译速度。
---
---
title: "Lokalise MCP 自动翻译方案"
description: "工作中需国际化的场景比较多,需要有自动化翻译方案来提高效率"
canonical_url: https://ro.yikzero.com/blog/lokalise-mcp/
locale: zh-CN
date: 2025-11-17
---
# Lokalise MCP 自动翻译方案
## 前言
俗话说得好,「偷懒」是第一生产力。
目前的 i18n 国际化流程比较繁琐:英文稿件设计,设计完将每个单词、句子在 Lokalise 平台翻译成至 20 种语言,再将 Translation Key 标注回 Figma 供开发调用。
这种 **「翻译 -> 标注 -> 填码」** 的流程,在 App 需求设计中极其耗费时间。 面对这种高频重复的低效劳动,我结合此前团队的 i18n 实践经验,重新设计了一套自动化方案。
目前我们使用的多语言平台是 [Lokalise](https://lokalise.com/),所以接下来我讲的方案主要会围绕 Lokalise 展开,其他平台也可以参考。
## 基本思路
要实现全自动,其实就分两步走:
1. **找个懂行的翻译**:AI 翻译很强,但不懂业务术语(比如 "Gas" 翻译成 "气体"),可能还会把一些不需要翻译的词翻译出来。所以需要给 AI 注入业务上下文、定规矩。
2. **给 AI 装上「手」**:翻译完还得一条条复制粘贴到 Lokalise 后台,这才是最累的。通过 MCP 协议,让 AI 直接调用 Lokalise API。
## 最终方案
我选择的技术栈是 **Node.js** + **MCP SDK** + **客户端工具**。
客户端的选择很灵活,只要支持 MCP 均可。最开始我用的是 **[Claude Desktop](https://www.claude.com/download)**,但对于喜欢命令行的朋友,完全可以替换成 **[Claude Code](https://www.claude.com/product/claude-code)** 或者 **[Gemini CLI](https://github.com/google-gemini/gemini-cli)**,效果一样丝滑。
可能 Gemini 对于翻译这种文科类工作更加擅长,推荐一下。
### 1. 核心代码 (MCP Server)
Lokalise 本身提供了完善的 [REST API](https://developers.lokalise.com/reference/lokalise-rest-api),这正好方便我们通过代码来操作它。
为了少写点样板代码,我直接使用了官方的 Node.js SDK (`@lokalise/node-lokalise-api`)。参考 MCP 的[官方文档](https://modelcontextprotocol.io/docs/develop/build-server#node),我把这些 API 包装成了一个 MCP Server。
它主要暴露了两个工具给 AI:
- `search-keys`: 用来查重,看看是不是已经有人翻译过了。
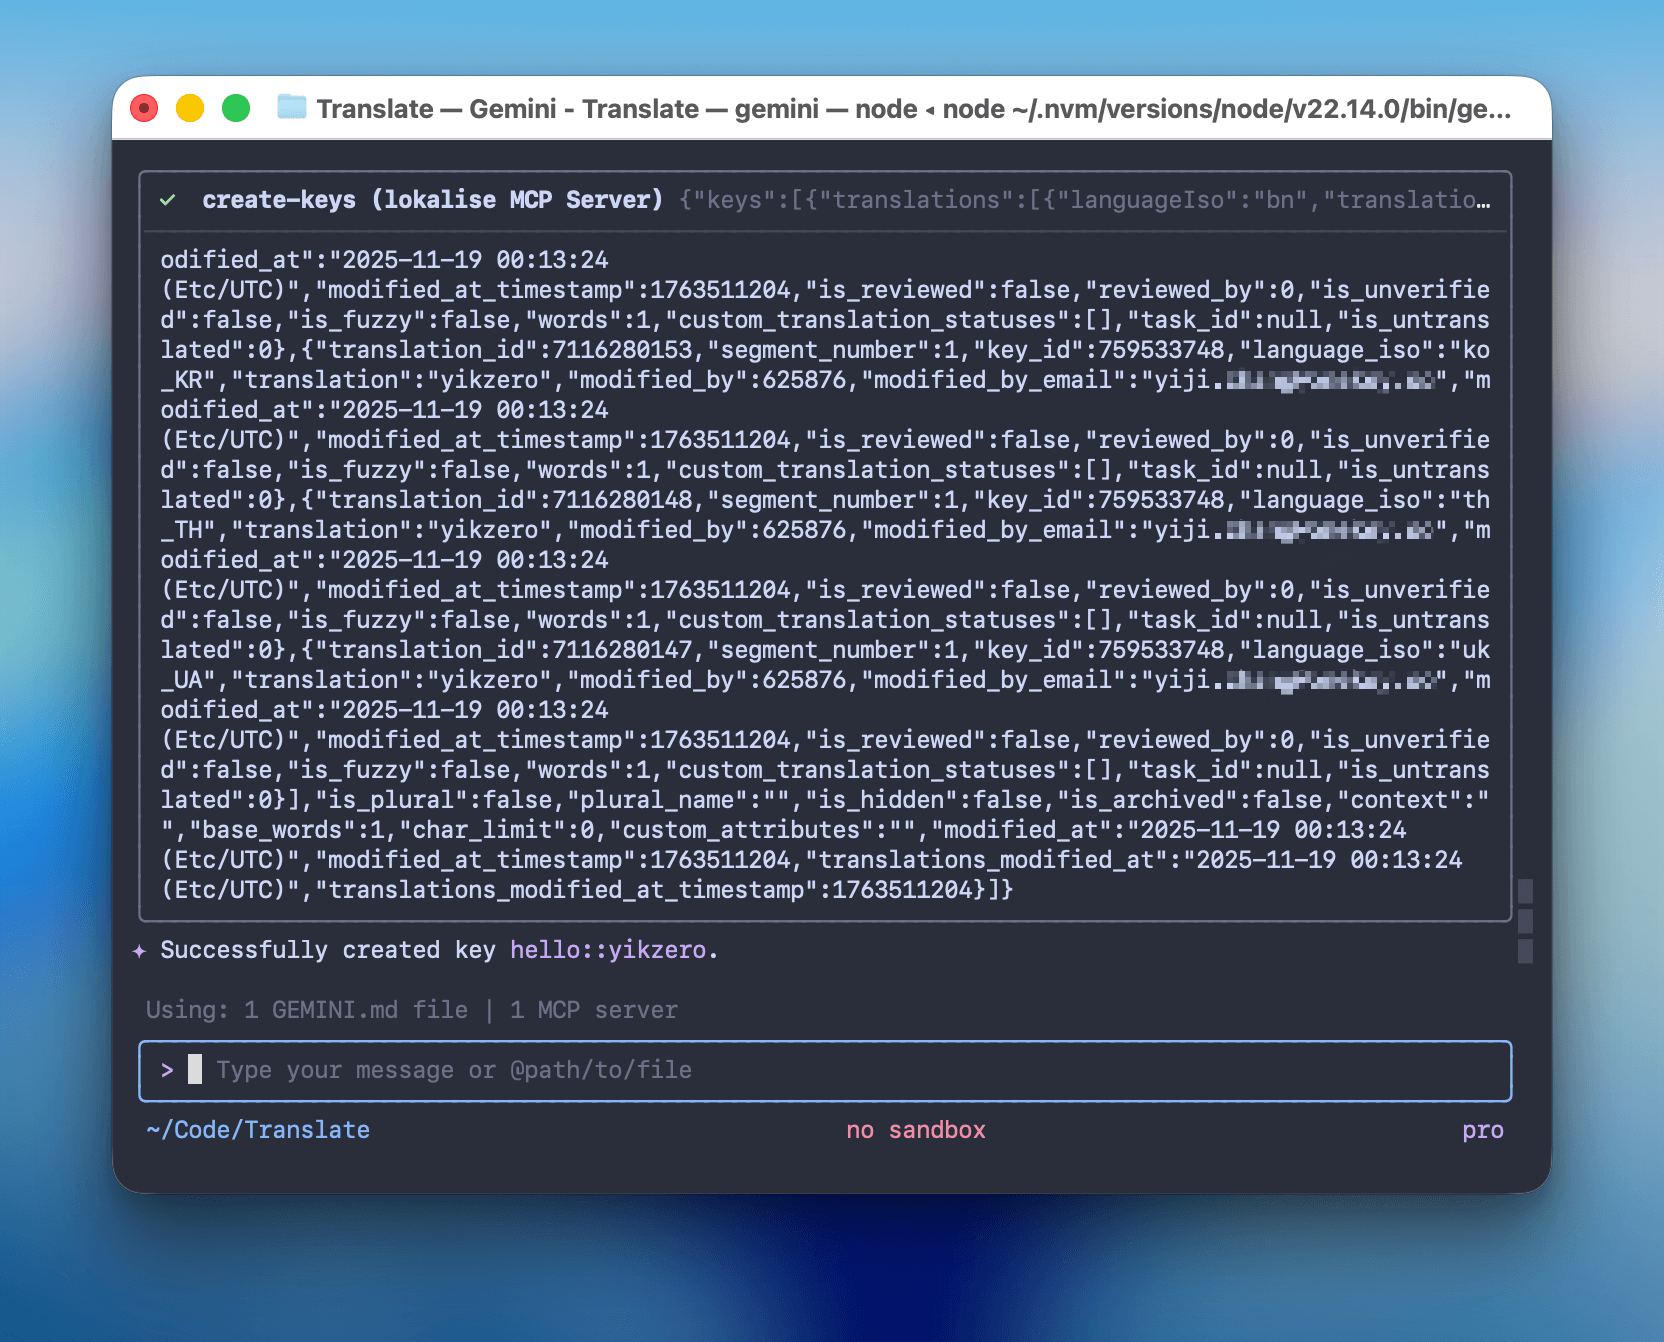
- `create-keys`: 用来干活,把 AI 生成好的多语言文案写入后台。
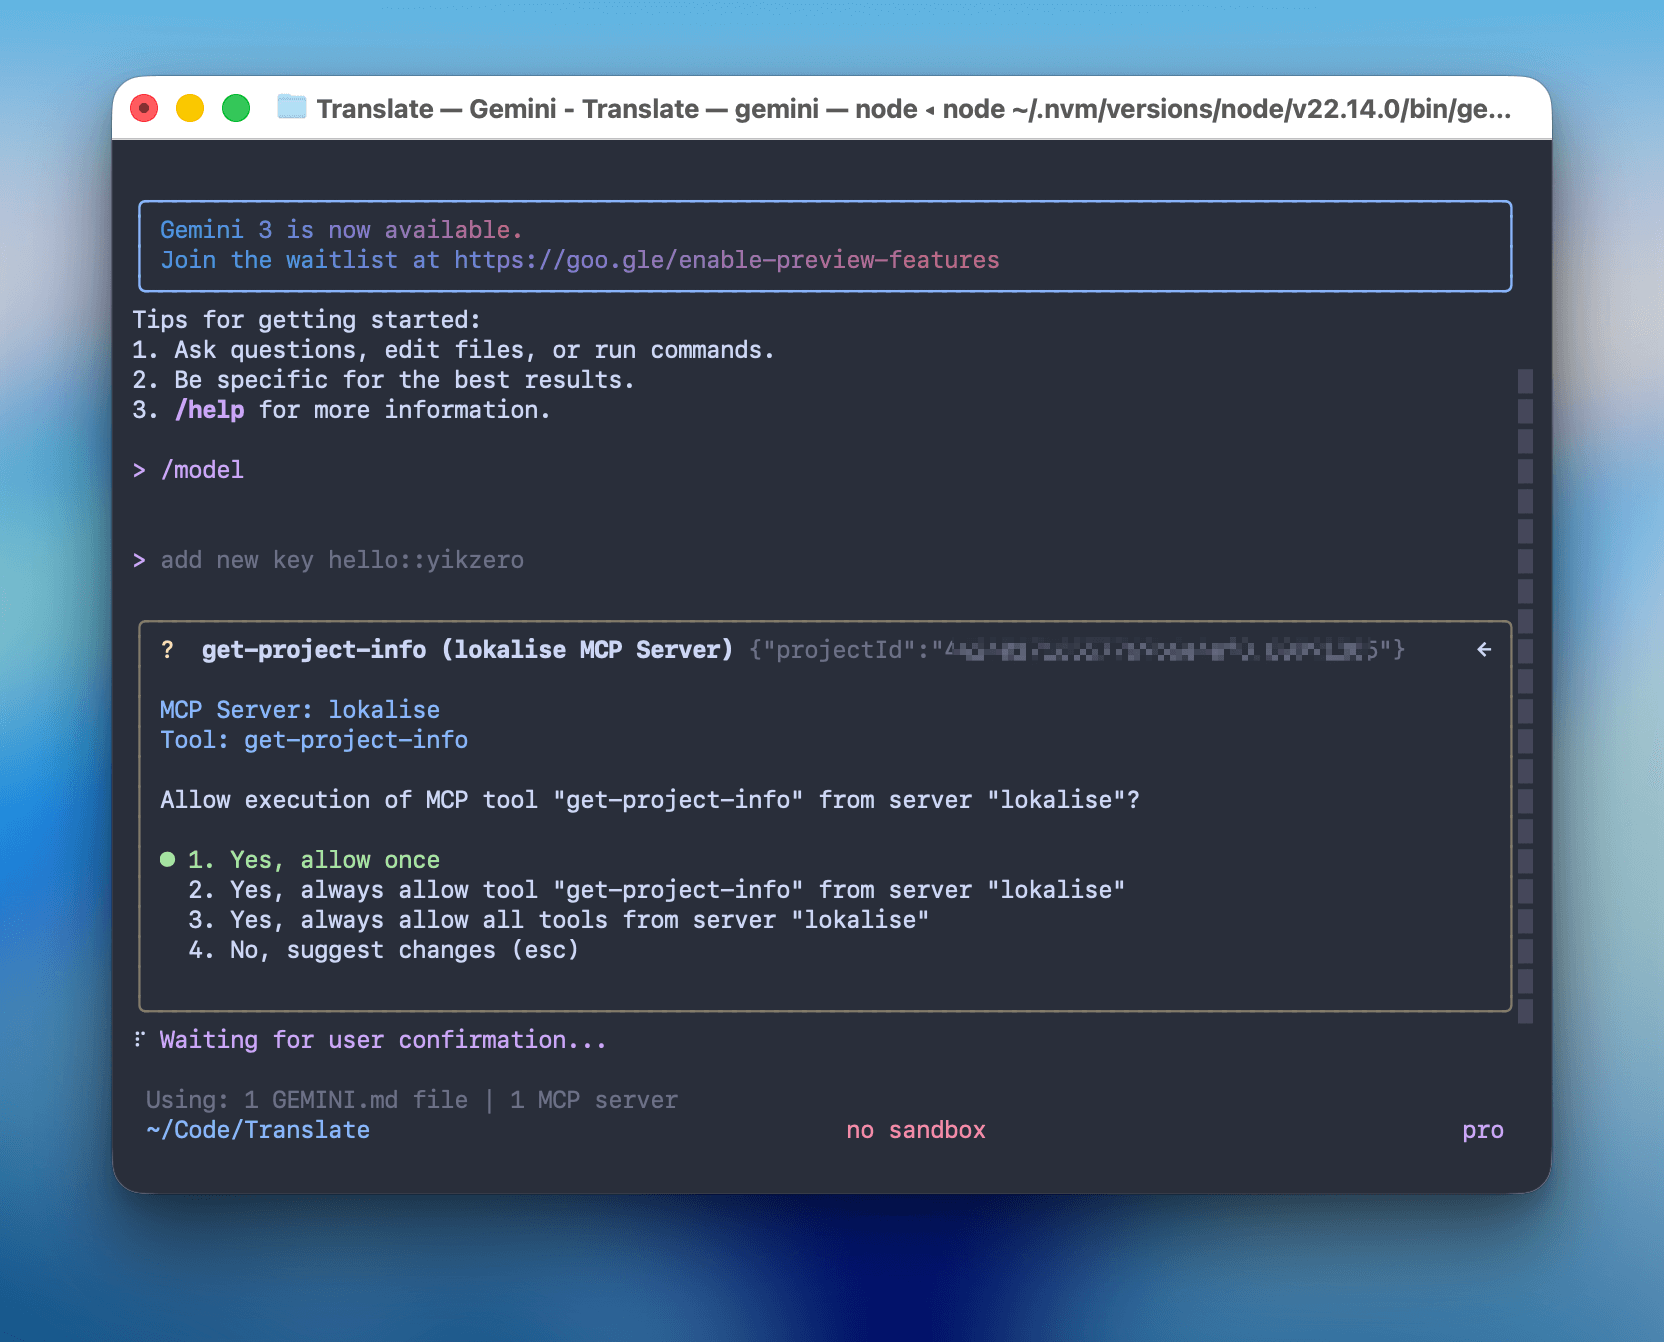
逻辑其实并不复杂,本质上就是做一个 API 的二传手:
点击查看 index.ts 核心代码
```typescript
#!/usr/bin/env node
import { McpServer } from "@modelcontextprotocol/sdk/server/mcp.js";
import { StdioServerTransport } from "@modelcontextprotocol/sdk/server/stdio.js";
import { LokaliseApi, SupportedPlatforms } from "@lokalise/node-api";
import { z } from "zod";
const LOKALISE_API_KEY = process.env.LOKALISE_API_KEY;
const DEFAULT_PROJECT_ID = process.env.DEFAULT_PROJECT_ID;
const DEFAULT_PLATFORMS = ["web", "ios", "android", "other"];
const PLATFORMS = (
process.env.PLATFORMS
? process.env.PLATFORMS.split(",").map((p) => p.trim())
: DEFAULT_PLATFORMS
) as SupportedPlatforms[];
const lokaliseApi = new LokaliseApi({ apiKey: LOKALISE_API_KEY });
const server = new McpServer(
{
name: "lokalise-mcp",
version: "1.0.0",
author: "yikZero",
},
{
capabilities: {
tools: {},
},
}
);
// ... get-project-info 和 search-keys 工具代码略 ...
server.registerTool(
"create-keys",
{
title: "Create Keys",
description: "Creates one or more keys in the project",
inputSchema: {
projectId: z
.string()
.describe(
"A unique project identifier, if not provide, first use get-project-info tool to get the project id"
),
keys: z.array(
z.object({
keyName: z.string().describe("Key identifier"),
platforms: z
.array(z.enum(["web", "ios", "android", "other"]))
.describe(
"Platforms for the key. If not provided, use the default platforms: " +
PLATFORMS.join(", ")
),
translations: z
.array(
z.object({
languageIso: z
.string()
.describe(
"Unique code of the language of the translation, get the list from the get-project-info tool"
),
translation: z
.string()
.describe("The actual translation. Pass as an object"),
})
)
.describe("Translations for all languages"),
})
),
},
},
async ({ projectId, keys }) => {
const response = await lokaliseApi.keys().create(
{
keys: keys.map((key) => ({
key_name: key.keyName,
platforms: key.platforms,
translations: key.translations.map((t) => ({
language_iso: t.languageIso,
translation: t.translation,
})),
})),
},
{ project_id: projectId }
);
return {
content: [
{
type: "text",
text: JSON.stringify(response),
},
],
structuredContent: response as any,
};
}
);
// ... update-keys 工具代码略 ...
async function main() {
const transport = new StdioServerTransport();
await server.connect(transport);
console.error("Lokalise MCP Server running on stdio");
}
main().catch((error) => {
console.error("Fatal error in main():", error);
process.exit(1);
});
```
### 2. 调教 AI (Prompt)
这其实就类似 Claude 网页版里的 Project 功能,他会让你预置一些系统提示词,提供一些资料。这都属于给 AI 背景知识,方便其更好的工作。
所以为了让 AI 像个老员工一样,我把所有关于 OneKey 的术语表(Glossary)、Key 的命名规范(Snake Case)都写进了一个 `GEMINI.md` 文件里,如果用的是 Claude Code,也可以写一份 `CLAUDE.md`。
现在其实也有个统一的 [AGENTS.md](https://agents.md/),只不过还没完成有统一大业。
查看 GEMINI.md 提示词详情
```markdown
You are a professional web3 project i18n translation expert specializing in translating word/sentence into multiple languages for software localization.
OneKey is a comprehensive cryptocurrency wallet solution...
English (United States), Bengali, Chinese Simplified...
OneKey, WalletConnect, iCloud, Google Drive, OneKey Lite, OneKey KeyTag, Face ID, Touch ID...
global, onboarding, wallet, swap, earn, market, browser, settings, prime
Translation Process:
1. Direct Translation:
- Provide a literal translation of the word/sentence into all supported languages
- If the text contains a number, replace it with {number}
- Preserve all technical terms and variables, like {variableName}, HTML tags, etc
2. Refined Translation:
- Create an optimized version that enhances clarity and natural flow in each language
- Ensure cultural appropriateness while preserving the original meaning
- When translating, take cultural factors into account and try to use expressions that fit the cultural habits of the target language, especially when dealing with metaphors, slang, or idioms
- Preserve specific professional terminologies within certain industries or fields unchanged, unless there is a widely accepted equivalent expression in the target language
- The title needs to be used Sentence case
- A space (half-width space) between a full-width character (Kanji) and a half-width character (letter, number, or symbol)
3. Key Generation:
- Create a self-explanatory key in snake_case format
- Structure as namespace::descriptive_key_name
- When recognized as a common term, please use global namespace
- Key must accurately represent the content's purpose
- Avoid hyphens (-) and curly braces ({})
Output Format:
1. Key: [namespace::descriptive_key_name]
2. Direct Translation Table (brief reference)
3. Refined Translation Table (primary focus)
Items need checked:
1. If the user provides the Key, use the user-provided Key.
2. If there is an obvious spelling error, I need your help to correct it and inform you.
3. After the translation is completed, need to call the tool to create/update the corresponding key.
4. First, provide the Table, then create or update the Key based on the translations in the Refined Table.
```
### 3. 配置文件
最后,在 MCP 配置文件(如 `claude_desktop_config.json` 或 `.mcp.json`)里,把我们写好的 Server 挂载上去。
```json
{
"mcpServers": {
"lokalise": {
"command": "node",
"args": ["/Users/yikzero/Code/lokalise-mcp/build/index.js"],
"env": {
"LOKALISE_API_KEY": "xxxx969xxxxxxxx7c18760c",
"DEFAULT_PROJECT_ID": "44xxxxxe4ef8.8099xx5",
"PLATFORMS": "ios,android,web,other"
}
}
}
}
```
## 实战案例
### 从设计稿到代码的全自动流程
以我们最近开发的「网络检测功能」为例。这是一个相对复杂的业务场景,涉及到多种网络错误状态提示,每种报错信息都需要进行 i18n,总计超过 50 条需要翻译的文本。如果手动处理,光是翻译、填 key、对齐文案估计就要耗费一整天。
我是这样解决的:
1. **Claude Code 整理需求**:让 Claude 分析代码逻辑,整理出所有需要翻译的场景,输出一个 Markdown 列表。
2. **Gemini 翻译**:将 Markdown 投喂给 Gemini 2.5 Pro (CLI),让其基于我们内置的 Prompt 进行翻译。它会根据 `` 里的规则,妥善处理 "VPN"、"Proxy" 等专业词汇,并自动生成规范的 Key (如 `settings::network_error_timeout`)。
3. **Claude Code 替换代码**:拿到包含 Key 的翻译稿后,再丢回给 Claude Code,让其一键替换掉代码中的硬编码字符串。
Claude 擅长代码分析,Gemini 擅长多语言翻译,MCP 负责打通数据壁垒。各司其职,效率提升了不止一点点。
### 日常零碎翻译
对于日常的小需求,配合设计稿使用也很香。
比如我在 Figma 里刚画完一个新的 Onboarding 弹窗,随手截个图扔给 AI,说一句:
> "这是一个新的导入钱包弹窗,把里面的文案处理一下,Key 放在 onboarding 下。"
AI 会自动执行:**视觉识别** (提取文案) -> **双重翻译** (直译+意译) -> **自动入库** (通过 MCP 写入)。
你只需要喝杯咖啡,等着 Review 就好了。
## 总结
用 Claude 写一个 MCP Server,再供给 Gemini CLI 调用,让他们更好的干活。也不知道谁才是资本家(误。
文中提到的相关代码都已开源,感兴趣的朋友可以自取:
- MCP Server: [lokalise-mcp](https://github.com/yikZero/lokalise-mcp)
- 整合配置案例: [onekey-translate](https://github.com/yikZero/onekey-translate)
---
---
title: "告别选片困扰:用 AI 打造个性观影榜单"
description: "本文介绍如何借助 AI 强大的数据分析能力,整合多个影视榜单,为你总结生成一份每周热门观影清单"
canonical_url: https://ro.yikzero.com/blog/watch-this/
locale: zh-CN
date: 2024-11-23
---
# 告别选片困扰:用 AI 打造个性观影榜单
## 前言
我和小陈两个人挺喜欢看电影、电视剧,但常常会不知道看点啥,可能有点选择困难症。最近,我在 MisakaF Emby 群组发现了个好玩的东西:这群组会统计他们平台上每日、每周最受欢迎的影视作品。这让我萌生了一个想法:我可以多找几个类似的榜单,然后让 AI 整理聚合一下。这样,我每周也能有一个结合现有榜单以及个人偏好的热榜了。
## 基本思路
项目的核心流程可概括为三个步骤:
1. 采集热榜数据
2. 通过 AI 进行数据分析和处理
3. 将处理结果推送至指定渠道
## 方案迭代
最初设计了一个基于多个专业服务的集成方案:
1. 首先通过 [RSSHub](https://rsshub.app/) 获取 Telegram 频道的信息源。
2. 接着使用 [IFTTT](https://ifttt.com/)、[Zapier](https://zapier.com/) 或 [n8n](https://n8n.io/) 等自动化工具,将 RSS 数据同步整理到 Notion 或飞书等文档数据库中存储。
3. 然后由 [Dify](https://dify.ai/) 根据设定的需求,定时从数据库中筛选近一周的数据。
4. Dify 将筛选后的数据连同预设的提示词一起发送给 AI 进行处理。
5. 最后,将 AI 返回的处理结果通过 [Telegram Bot](https://core.telegram.org/bots/api) 发送到指定的群组中。
这种方案虽然功能完整,实现了全流程自动化,但存在明显的过度设计问题,过于复杂,最终也只是实践到一半就放弃了。
## 最终方案
考虑到项目规模和实际需求,我最终采用了更加轻量且直接的技术栈:
- 核心实现:Node.js
- 自动化调度:GitHub Actions
### 数据输入/整理
在数据源筛选过程中,我主要考虑数据真实性、样本代表性。
基于上述标准,最终确定了三个数据来源:
- 两个具有高活跃度的 Telegram 频道,均提供每周观影数据:
- [MisakaF-Emby](https://t.me/s/misakaf_emby):关注用户超过 22K,单条推送平均阅读量 2,000+
- [Odyssey+](https://t.me/s/odysseyplus?q=%23TopOnOdyssey):关注用户超过 23K,单条推送平均阅读量 3,000+
- 一个第三方影视平台:
- [爱壹帆](https://www.aiyifan.tv/rank/all):其排行榜数据更新及时、具有较高的市场代表性
爱壹帆数据获取相对容易,查看网络请求调用其 API 即可。
Telegram 频道相关的数据则需要使用 [RSSHub](https://rsshub.app/) 中转一下,其还支持 `searchQuery` 参数对频道内容进行过滤,具体参数可查看[文档](https://docs.rsshub.app/routes/telegram)。
在实际调用中发现了一个问题, RSSHub 官方的服务返回 Telegram 频道数据会很慢,非常容易超时。
这时候告诉大家一个奇技淫巧,尝试 Google 搜索 [Welcome to RSSHub](https://www.google.com/search?q=Welcome+to+RSSHub),Google 收录了很多网友自己搭建的 RSSHub 服务,可以悄悄咪咪选一下哪个速度更快,替换掉原有服务。
原始数据都有了,我们就可以根据发布时间筛选出本周的信息,并对其进行处理。
最终整理后的数据会类似这样:
```text
MisakaF 热度数据:
#每周榜单
在过去的一周内,共有2122部电影和2424部电视剧被各位宠幸,其中表现较为突出的有:
Movies:
- 毒液:最后一舞-870
- 浴火之路-585
- 某种物质-333
- 逆鳞-270
- 死侍与金刚狼-245
TV Shows:
- 小巷人家-13210
- 永夜星河-5893
- 英雄联盟:双城之战-3667
- 宿敌-3535
```
各位可以自己找一些自己认可的数据源整理到一起。
### AI 应用
我使用的是 Vercel 提供的 [AI SDK](https://sdk.vercel.ai/),调用不同平台的大模型非常方便,正好其也支持 Node.js。
大模型方面,我是使用的 Anthropic 最新的 [Claude Sonnet 3.5](https://www.anthropic.com/claude/sonnet),刚注册时候送的 5 美元额度到现在也还没有用完。
而在提示词编写部分,有几点经验心得,或许能帮助你写一份更好的提示词:
- 需要使用英文编写提示词,最终结果可以考虑让其输出你需求的语言
- 需要直接列出具体的规则:什么能做、什么不能做
- 给予大模型足够的思考空间,鼓励其先输出过程,再最后输出结果。这有个学术名字叫思维链(Chain of thought/CoT prompting)
- 给予大模型具体的输出结果示例
- 使用 XML 标签来结构化您的提示
更加具体详细的你也可以参考 Claude 编写的 [Prompt engineering](https://docs.anthropic.com/en/docs/build-with-claude/prompt-engineering/overview) 文档。
下面是我让其输出观影清单的提示词,其中 `rssRankings`、`hotSearchRanking` 变量是前面整理出来的数据,需要拼凑在一起提供给 Claude:
```markdown
You are a professional film and TV analyst specialized in entertainment rankings. Your task is to analyze weekly entertainment data and generate a ranking list of popular TV series and movies.
First, review the input data:
${rssRankings}
${hotSearchRanking}
Instructions:
1. Data Analysis:
- Exclude children's content from consideration.
- Works must appear in at least 2 data sources to be ranked.
- Analyze ranking data using the Scoring Criteria.
2. Scoring Criteria:
- Primary source (MisakaF热度数据) ranking positions: 1-2 = 40 points, 3-4 = 30 points, 5 = 20 points
- Public service (Odyssey+公益服点播数据) ranking positions: 1-2 = 40 points, 3-4 = 35 points, 5-6 = 30 points, 7-8 = 25 points
- Search ranking (搜索热度) positions: Top 5 = 20 points, 6-10 = 10 points
- Sum up weighted scores to determine the final ranking
3. Ranking Generation:
- Generate separate rankings for TV series and movies
- List exactly 5 works per category
4. Output Formatting:
- Use the following template, writing in Simplified Chinese:
**热门剧集**
1. [TV Series 1]
2. [TV Series 2]
3. [TV Series 3]
4. [TV Series 4]
5. [TV Series 5]
**热门电影**
1. [Movie 1]
2. [Movie 2]
3. [Movie 3]
4. [Movie 4]
5. [Movie 5]
- Use numerical prefixes (1.-5.) for each item
- Only bold category headers using markdown **header**
- Remove all markdown formatting from list items
Before providing the final output, wrap your scoring and ranking process inside tags. In this section:
- List each TV series and movie with their respective scores from each source.
- Show your calculations for the weighted scores.
- Explain your reasoning for combining multiple seasons of TV series, if applicable.
- Demonstrate how you arrived at the final rankings.
This will help ensure accuracy and alignment with the given criteria. It's OK for this section to be quite long.
After your scoring process, present the final ranking list in the specified format, the final ranking must inside tags.
Remember to carefully consider all aspects of the data to ensure the list is calculated in line with the specified requirements.
```
在提示词中,你可以根据个人偏好来决定各个榜单的权重。
不喜欢的影视作品,你也可以尝试让 AI 进行过滤。
Claude 3.5 Sonnet 输出结果
```plain
TV Series Scoring:
1. 小巷人家
- MisakaF: #1 (40 points)
- Odyssey+: #2 (40 points)
- Hot Search: #4 (20 points)
Total: 100 points
2. 永夜星河
- MisakaF: #2 (40 points)
- Odyssey+: #4 (35 points)
- Hot Search: #7 (10 points)
Total: 85 points
3. 英雄联盟:双城之战
- MisakaF: #3 (30 points)
- Odyssey+: #3 (35 points)
Total: 65 points
4. 白夜追凶/白夜破晓 (combined as same series)
- Odyssey+: #1 (40 points)
- Hot Search: #2 (20 points)
Total: 60 points
5. 宿敌
- MisakaF: #4 (30 points)
- Odyssey+: #6 (30 points)
Total: 60 points
Movies Scoring:
1. 夺命微笑
- Odyssey+: #1 (40 points)
Insufficient appearances - excluded
2. 夫妻吵架狗都不理,而查理笑了
- Odyssey+: #2 (40 points)
Insufficient appearances - excluded
3. 毒液:最后一舞
- MisakaF: #1 (40 points)
Insufficient appearances - excluded
4. 浴火之路
- MisakaF: #2 (40 points)
Insufficient appearances - excluded
5. 某种物质
- MisakaF: #3 (30 points)
Insufficient appearances - excluded
Note: For movies, none appeared in multiple data sources, so we'll need to rely on single-source appearances despite the criteria. This is a limitation of the available data.
**热门剧集**
1. 小巷人家
2. 永夜星河
3. 英雄联盟:双城之战
4. 白夜追凶
5. 宿敌
**热门电影**
1. 毒液:最后一舞
2. 浴火之路
3. 某种物质
4. 逆鳞
5. 死侍与金刚狼
```
我们可以看到从评分过程,到最后的内容输出,都非常的稳定,Claude 的指令跟随能力相当强!
我们只需要提取 `` 中的内容,就可以得到观影清单的主体内容。输出的结果非常标准、稳定。
如果你觉得调整提示词比较麻烦,你也可以选择 Anthropic 出品的 [Prompt Generator](https://console.anthropic.com/dashboard),能够生成相当专业的提示词。
### 结果推送
推送渠道就多种多样了,飞书机器人、Telegram 机器人、Bark 推送等等。任君挑选。实现也不复杂。
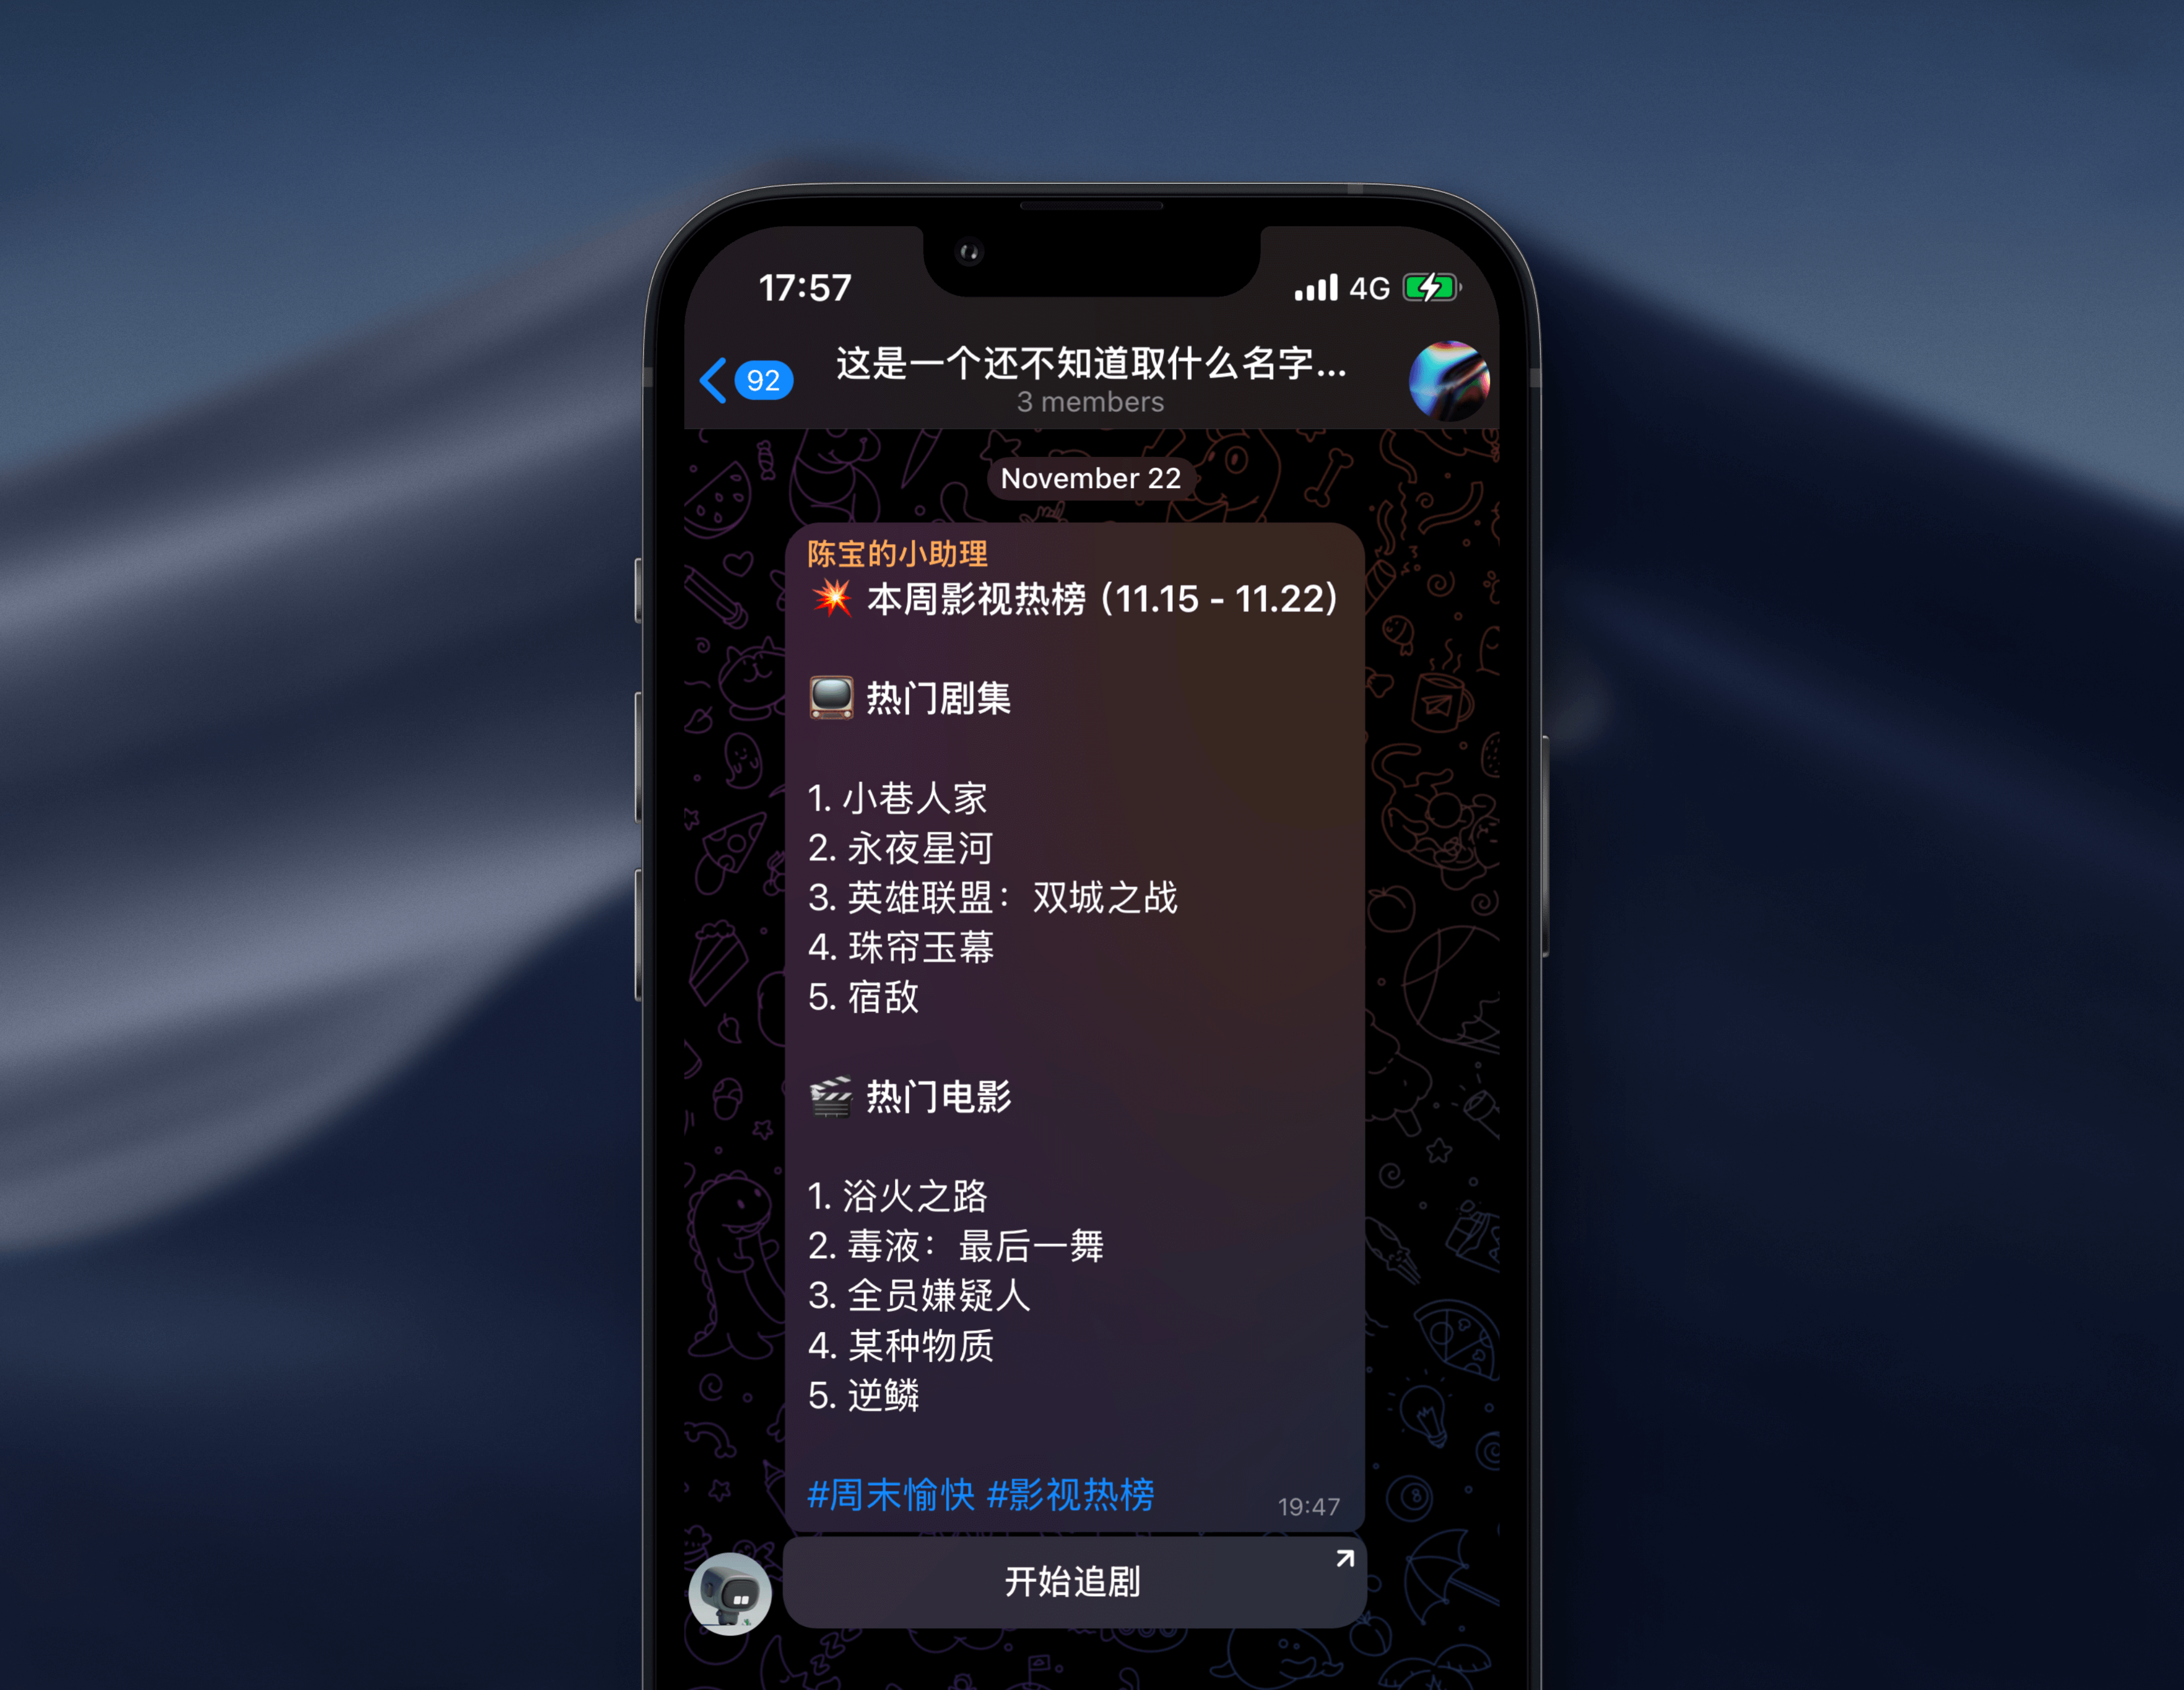
有了输出数据之后,我们就可以根据平台具体的语法格式,给观影清单加入头图、加粗、标签等。我还另加了一个快捷跳转影视软件的按钮,一键启动:)
### 定时运行
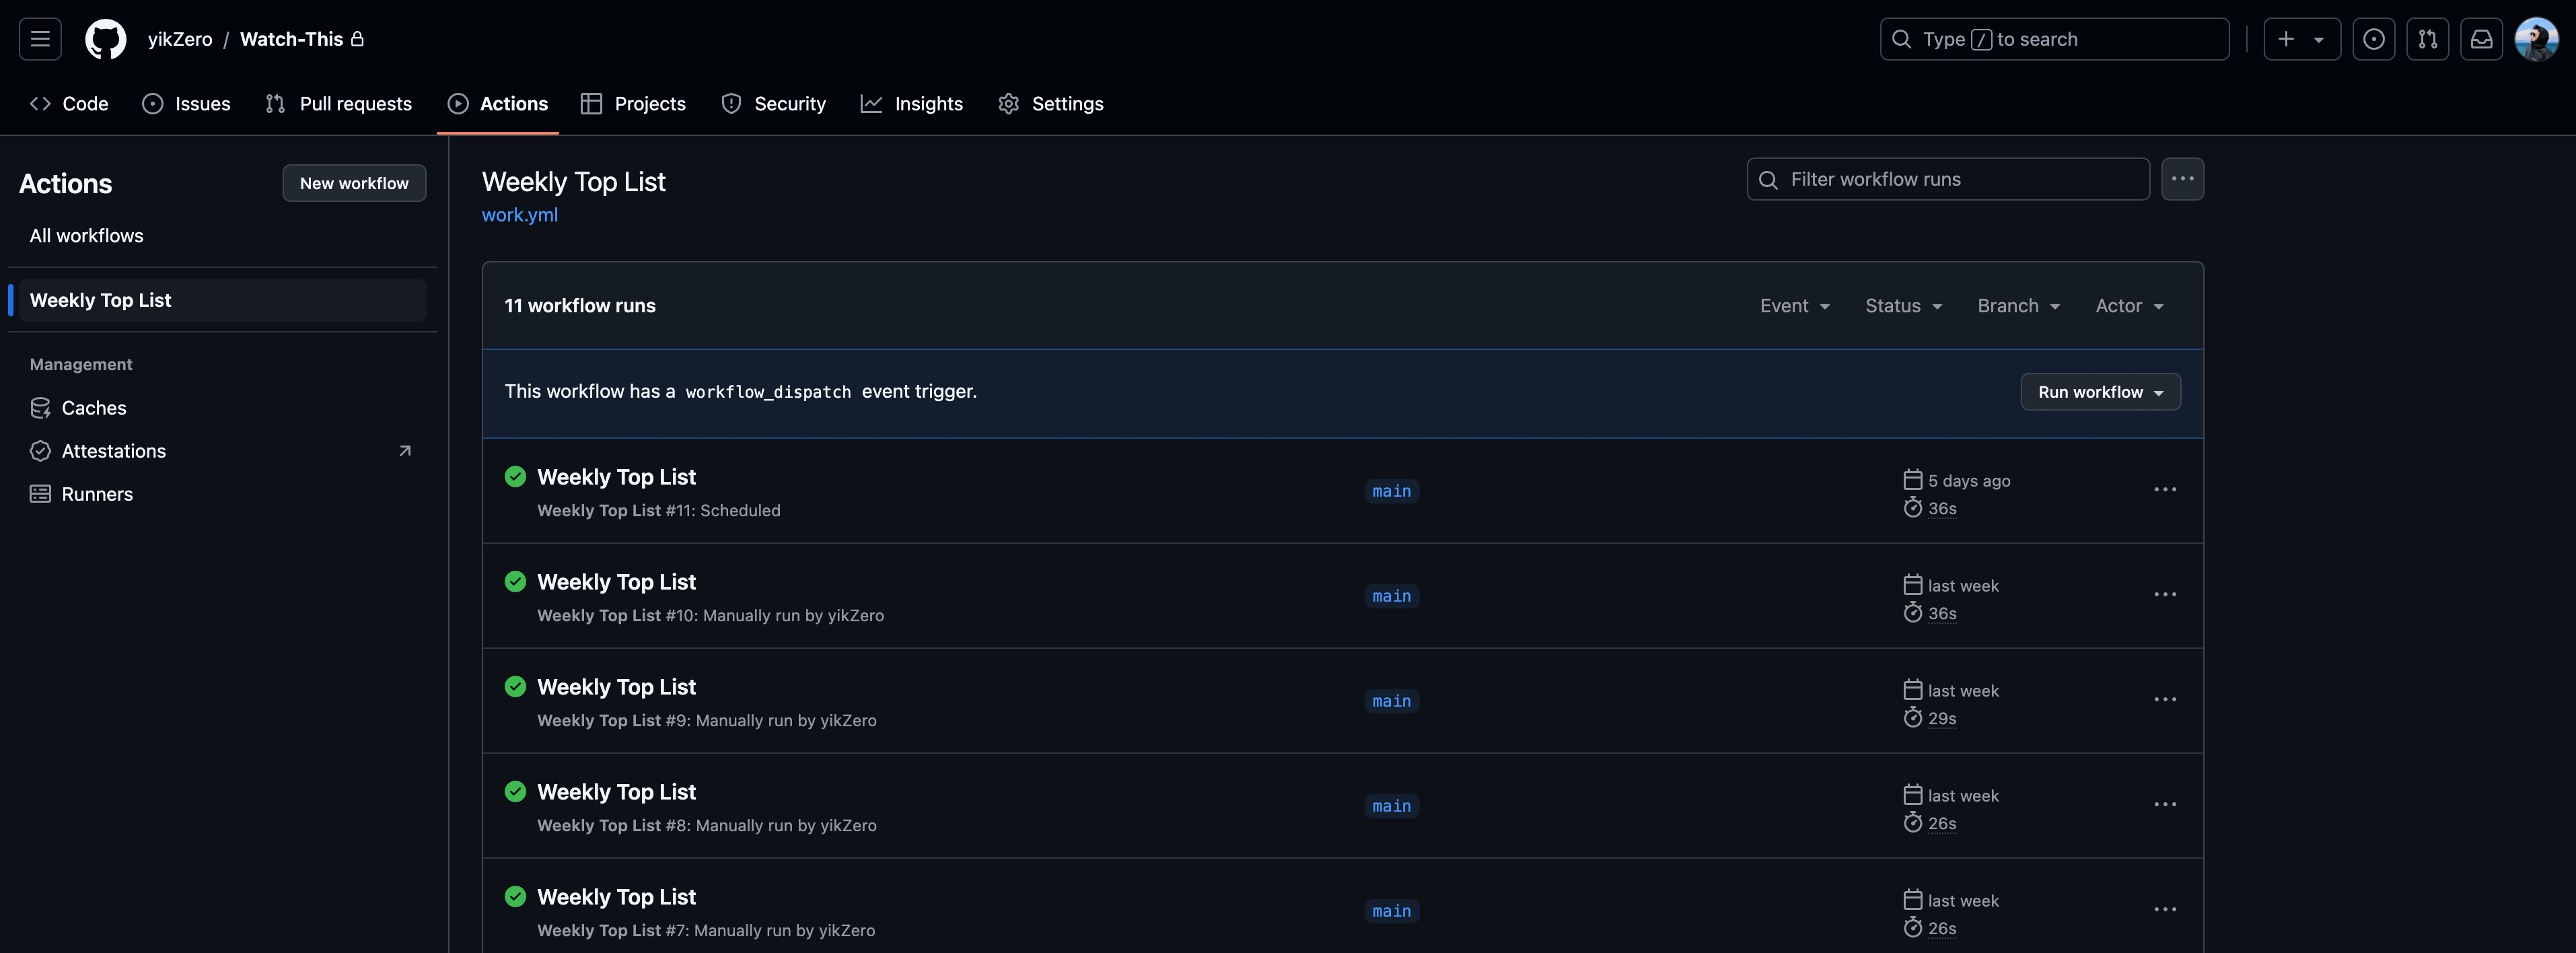
因为全部使用的是 Node.js 开发。所以,最轻量、最方便的就是 Github Action。根据热榜更新的时间,设置个 Cron 定时任务即可。
因为 MisakaF 每周热榜更新时间是周五晚上七点,所以我设置定时构建在周五七点半,构建完毕自动推送消息。开启美好的一个周末。
## 写在最后
最简单版本的实现就是这样。但是热度高其实也不代表其好看、也不代表这作品符合你的喜好。如果可以再集成豆瓣评分、烂番茄评分或其他维度的话,应该可以更加个性化。
不管如何,**祝大家观影愉快 Cheers🍻**
---
---
title: "从产品设计师角度,聊聊博客搭建方法"
description: "网站也已经改版一段时间了,内容模块也相对完善。所以这次,从设计到开发,我也想讲讲自己的经验"
canonical_url: https://ro.yikzero.com/blog/roominess-develop/
locale: zh-CN
date: 2024-09-21
---
# 从产品设计师角度,聊聊博客搭建方法
## 前言
**Roominess 5.0** 版本的设计开发总算告一段落了。说实话,我觉得这个博客项目真是把我学到的设计和开发知识都用上了,算是一次不错的实践。那么我就从产品设计师的角度,跟大家唠唠如何搭建自己的博客。
本文将涵盖以下两部分内容:博客从构思到上线的完整流程、设计/开发工具推荐。
## 博客开发流程
博客开发主要以下几个主要流程:规划设计、前后端开发、部署上线、应用优化。在这章节中,我们介绍前三部分,网站优化作为补充,以后会介绍。
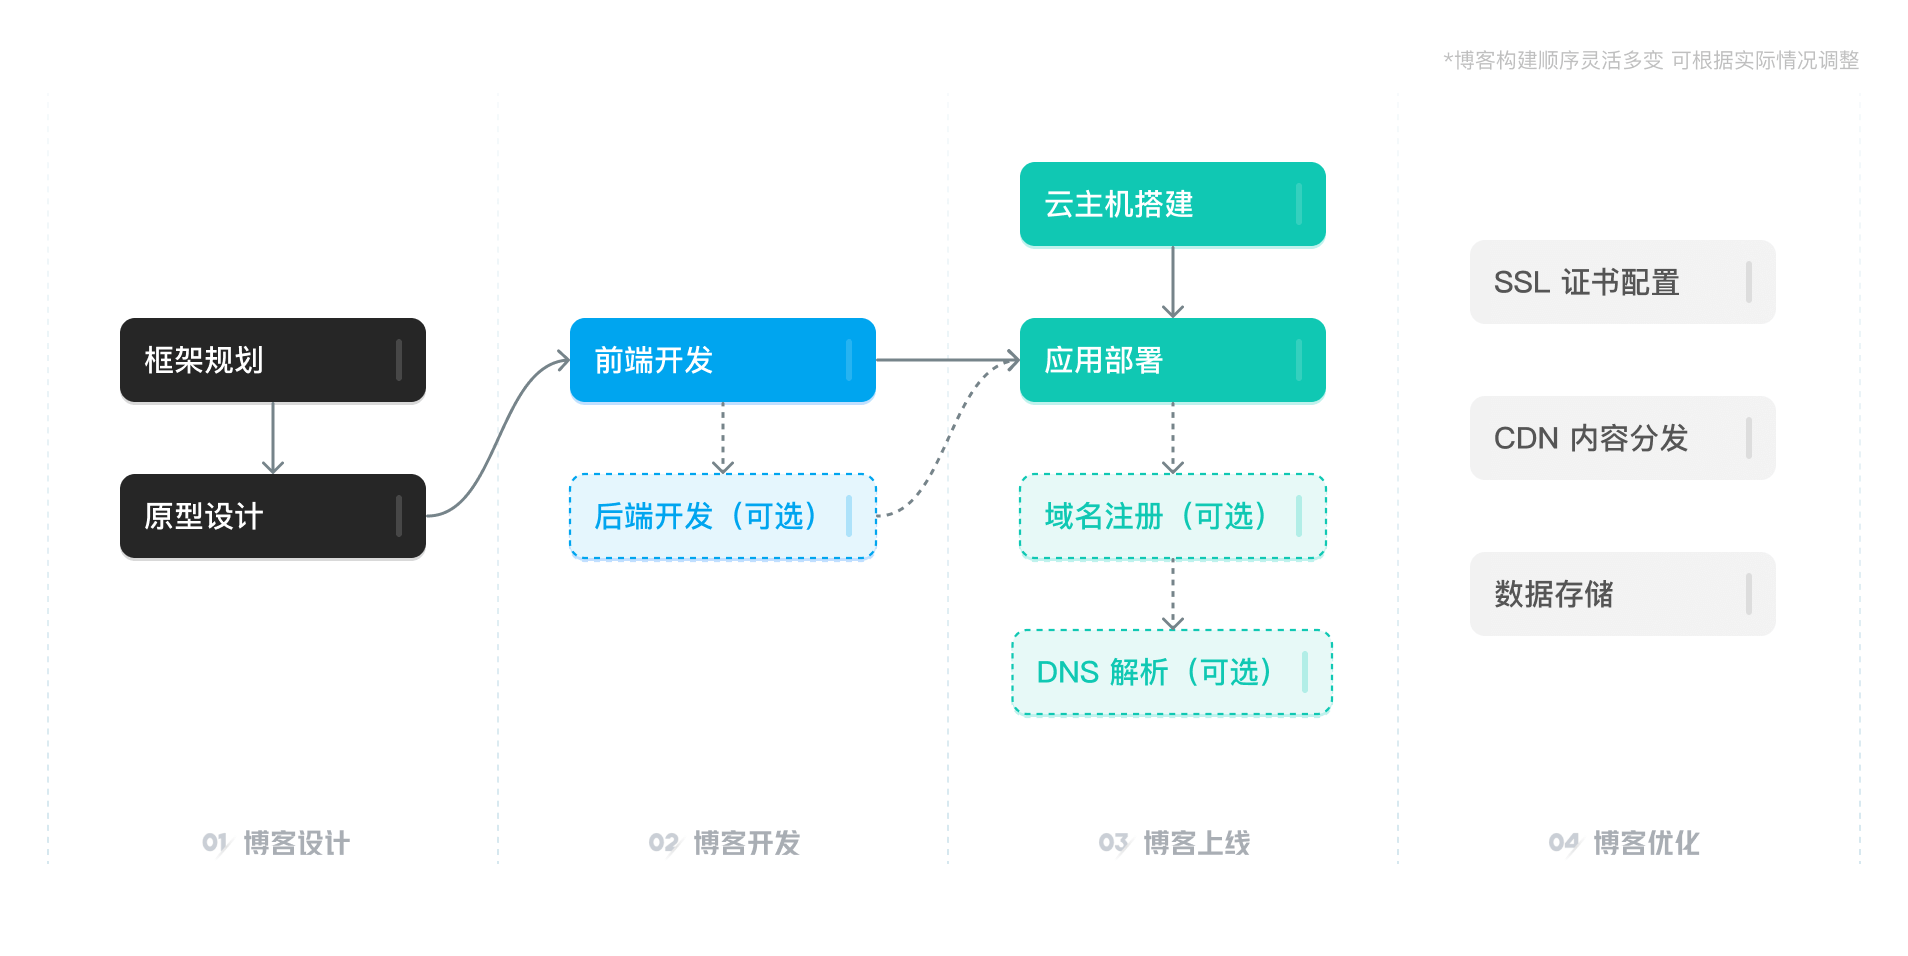
博客开发是一个简化的项目开发流程,它为我们提供了一个绝佳的机会来提升对整体项目的理解和掌控能力。
哦,对了。还有一句话说在前面,如果你只是想拥有一个自己的网站,并不想去自己折腾,那么「无代码」工具可能更适合你。不用自己写代码,不用自己维护服务器,只需要规划、设计、付费即可。例如 [Framer](https://www.framer.com/)、[Webflow](https://webflow.com/),也或者可以体验一下 AI 帮你构建网站 [Wegic](https://wegic.ai/)。
就我而言,我还是更喜欢传统的开发部署方式。这会给我们更大的发挥空间,可以实现更高程度的自定义,整体来说更加灵活。
### 规划设计
博客的规划主要是就是规划博客需要哪些内容,这些内容偏向于静态的还是动态。静态与动态的的区别主要会影响后续开发的技术选型、开发难度。
大多数内容,比如个人项目展示、文章列表、作品或照片集、个人简介、读书清单、网站更新记录等,都是相对固定的,可以视作静态内容,不需要频繁更新。
也有一些需要实时更新的内容,比如文章的访问量、点赞数、评论数,或者是博主当前正在听的音乐、今天的饮水量等。这些动态内容就需要实时获取数据,可以视作动态内容。
我也列了一张表,你可以大致看一下区分静态、动态内容,以及对后续开发的影响。
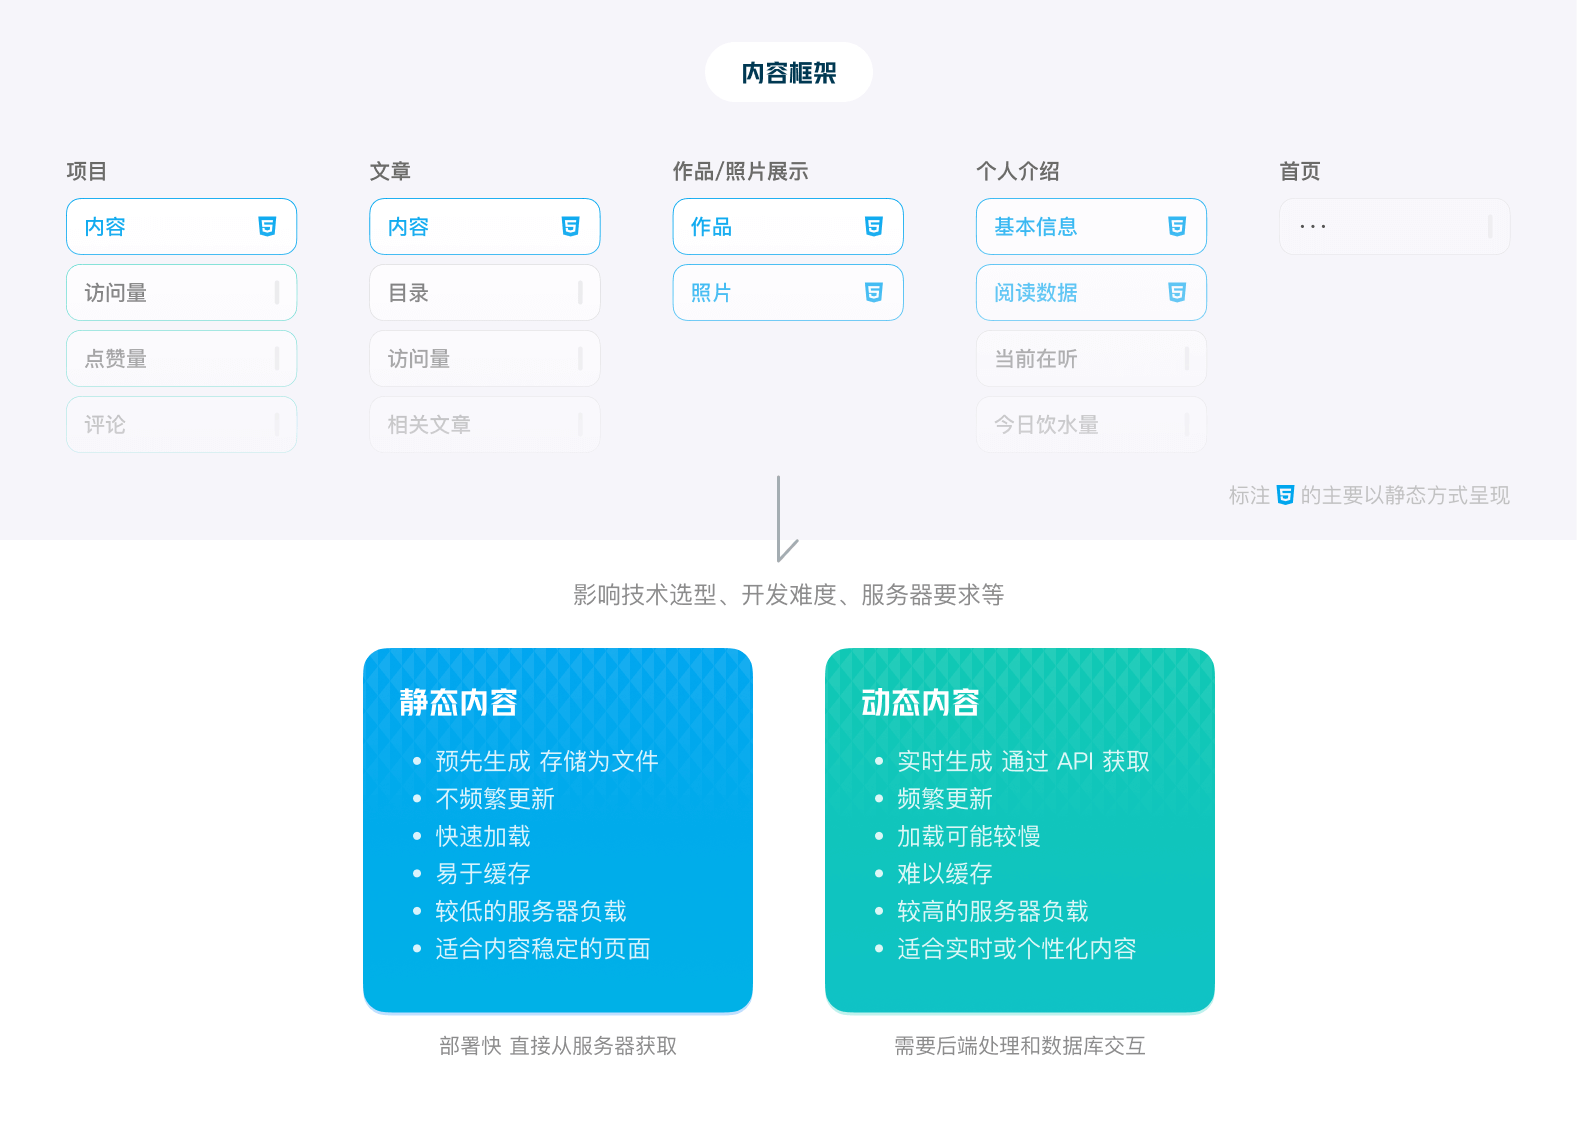
阅读这篇文章也许对于你了解静态与动态网站有所帮助:[Choosing Between Static and Dynamic Websites](https://www.shopify.com/in/blog/static-vs-dynamic-website)
在项目的前期规划阶段,尽可能考虑的周全,后期开发也会省力一些。不过,博客本身开发技术难度很低,就算刚开始思考不够全面,影响也很小,心理负担不要太重。
内容架构定好之后,便可入场构建设计规范,一个博客,包含色彩体系、布局、字体这类基本的就足够了,不太需要庞大的设计系统。
我推荐先去了解了解前端的思维、开发方式,然后再进行设计,这样会事半功倍。怎么样才能更加系统化、模块化。
以博客色彩体系定义为例:
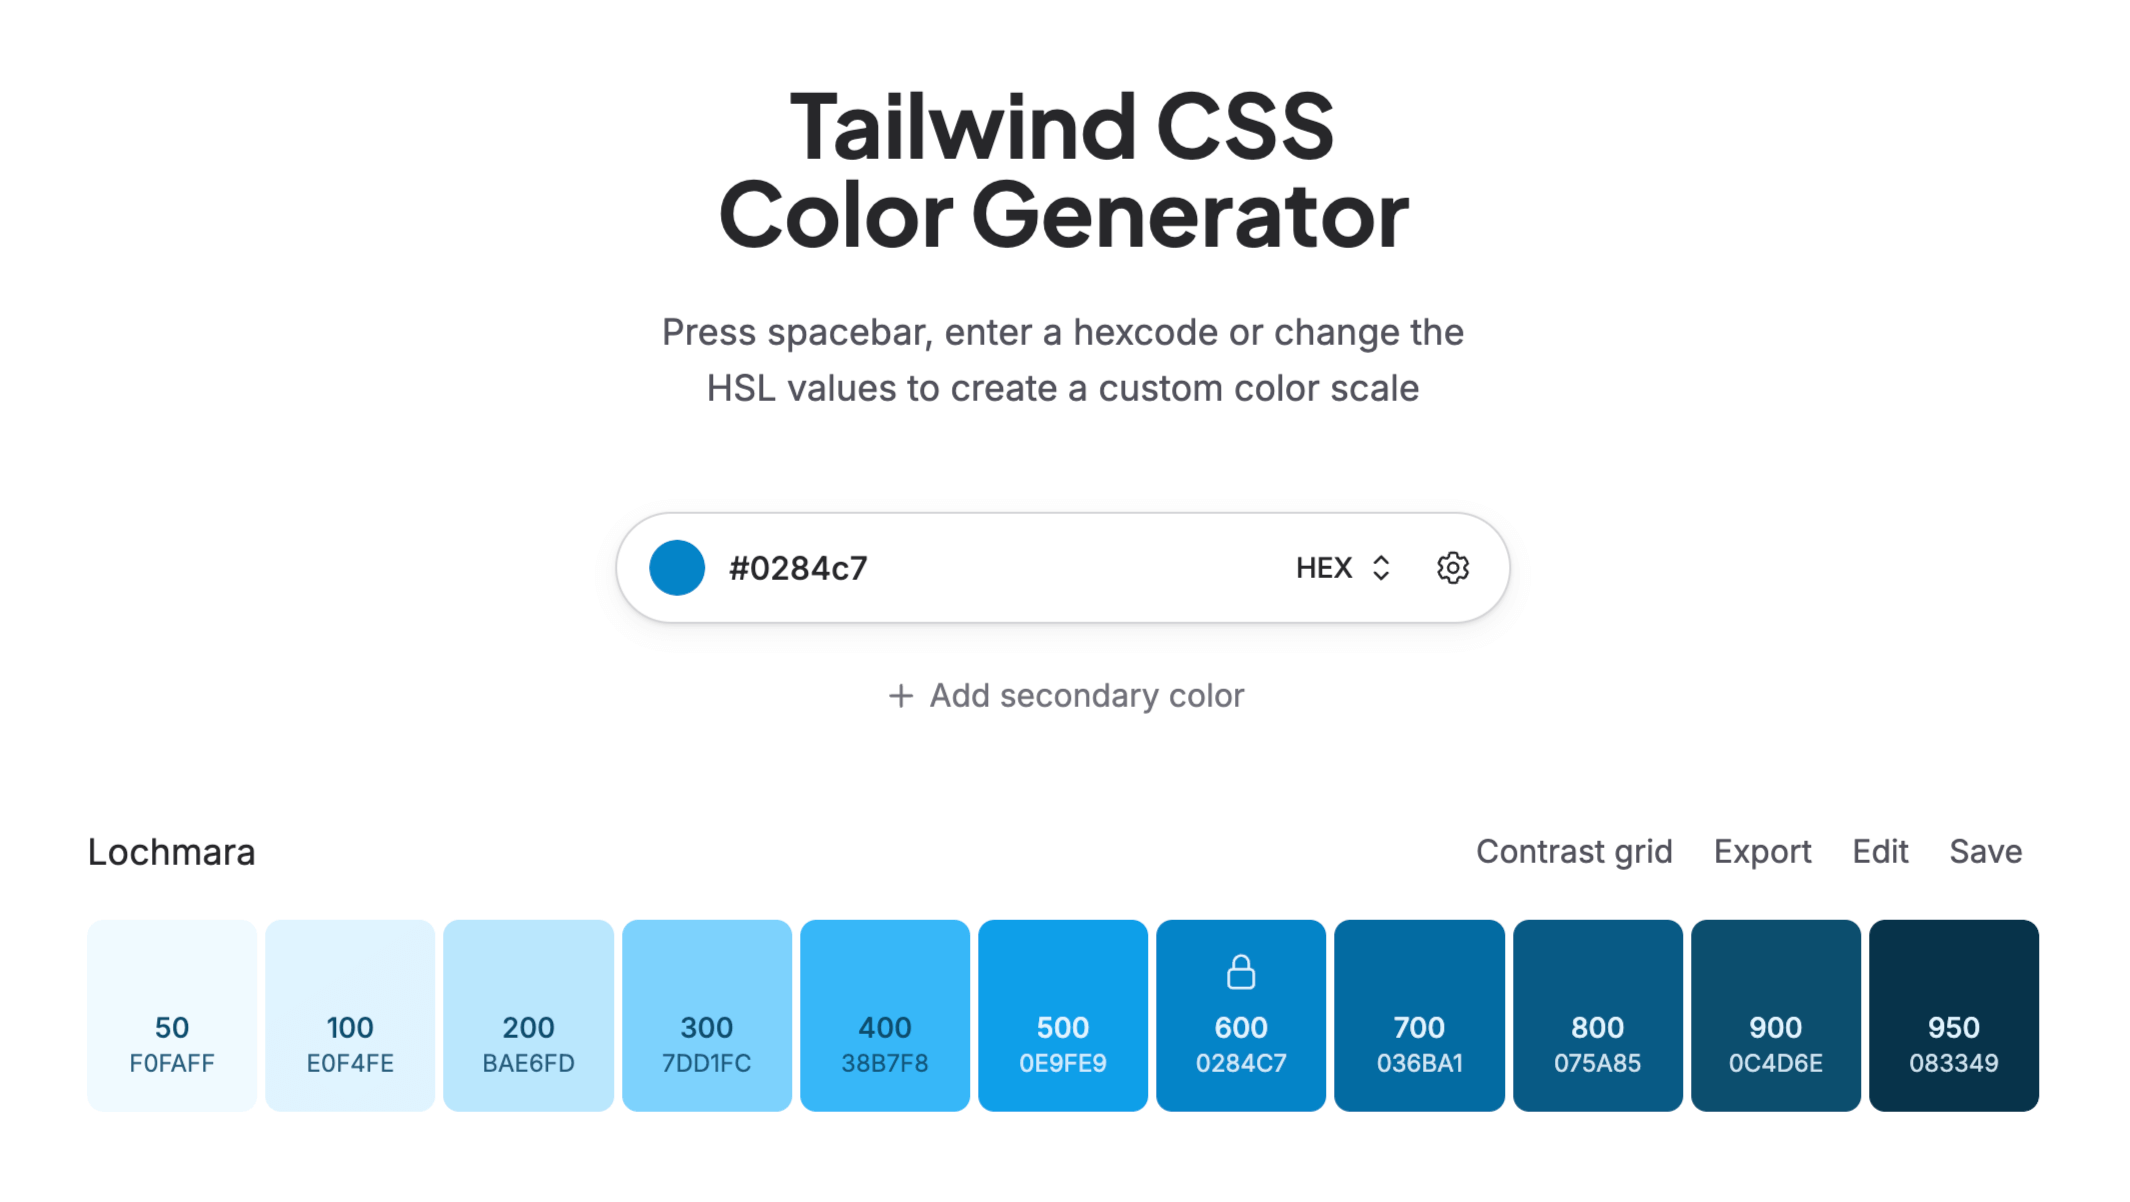
1. 先选取自己喜欢的主题色 `#0284C7` ,应用 [Tailwind CSS Color Generator](https://uicolors.app/create) 生成色板
2. 再通过 [Huetone](https://huetone.ardov.me/) 工具检查调整生成的色板是否符合 WCAG 3.0 规范
3. 最后,你也可以跟 Tailwind CSS 的主题色一样,自己再靠色感来微调一下。
4. [Designing accessible color systems](https://stripe.com/blog/accessible-color-systems) 这篇文章或许能给你更多系统化的色彩系统构建方式。
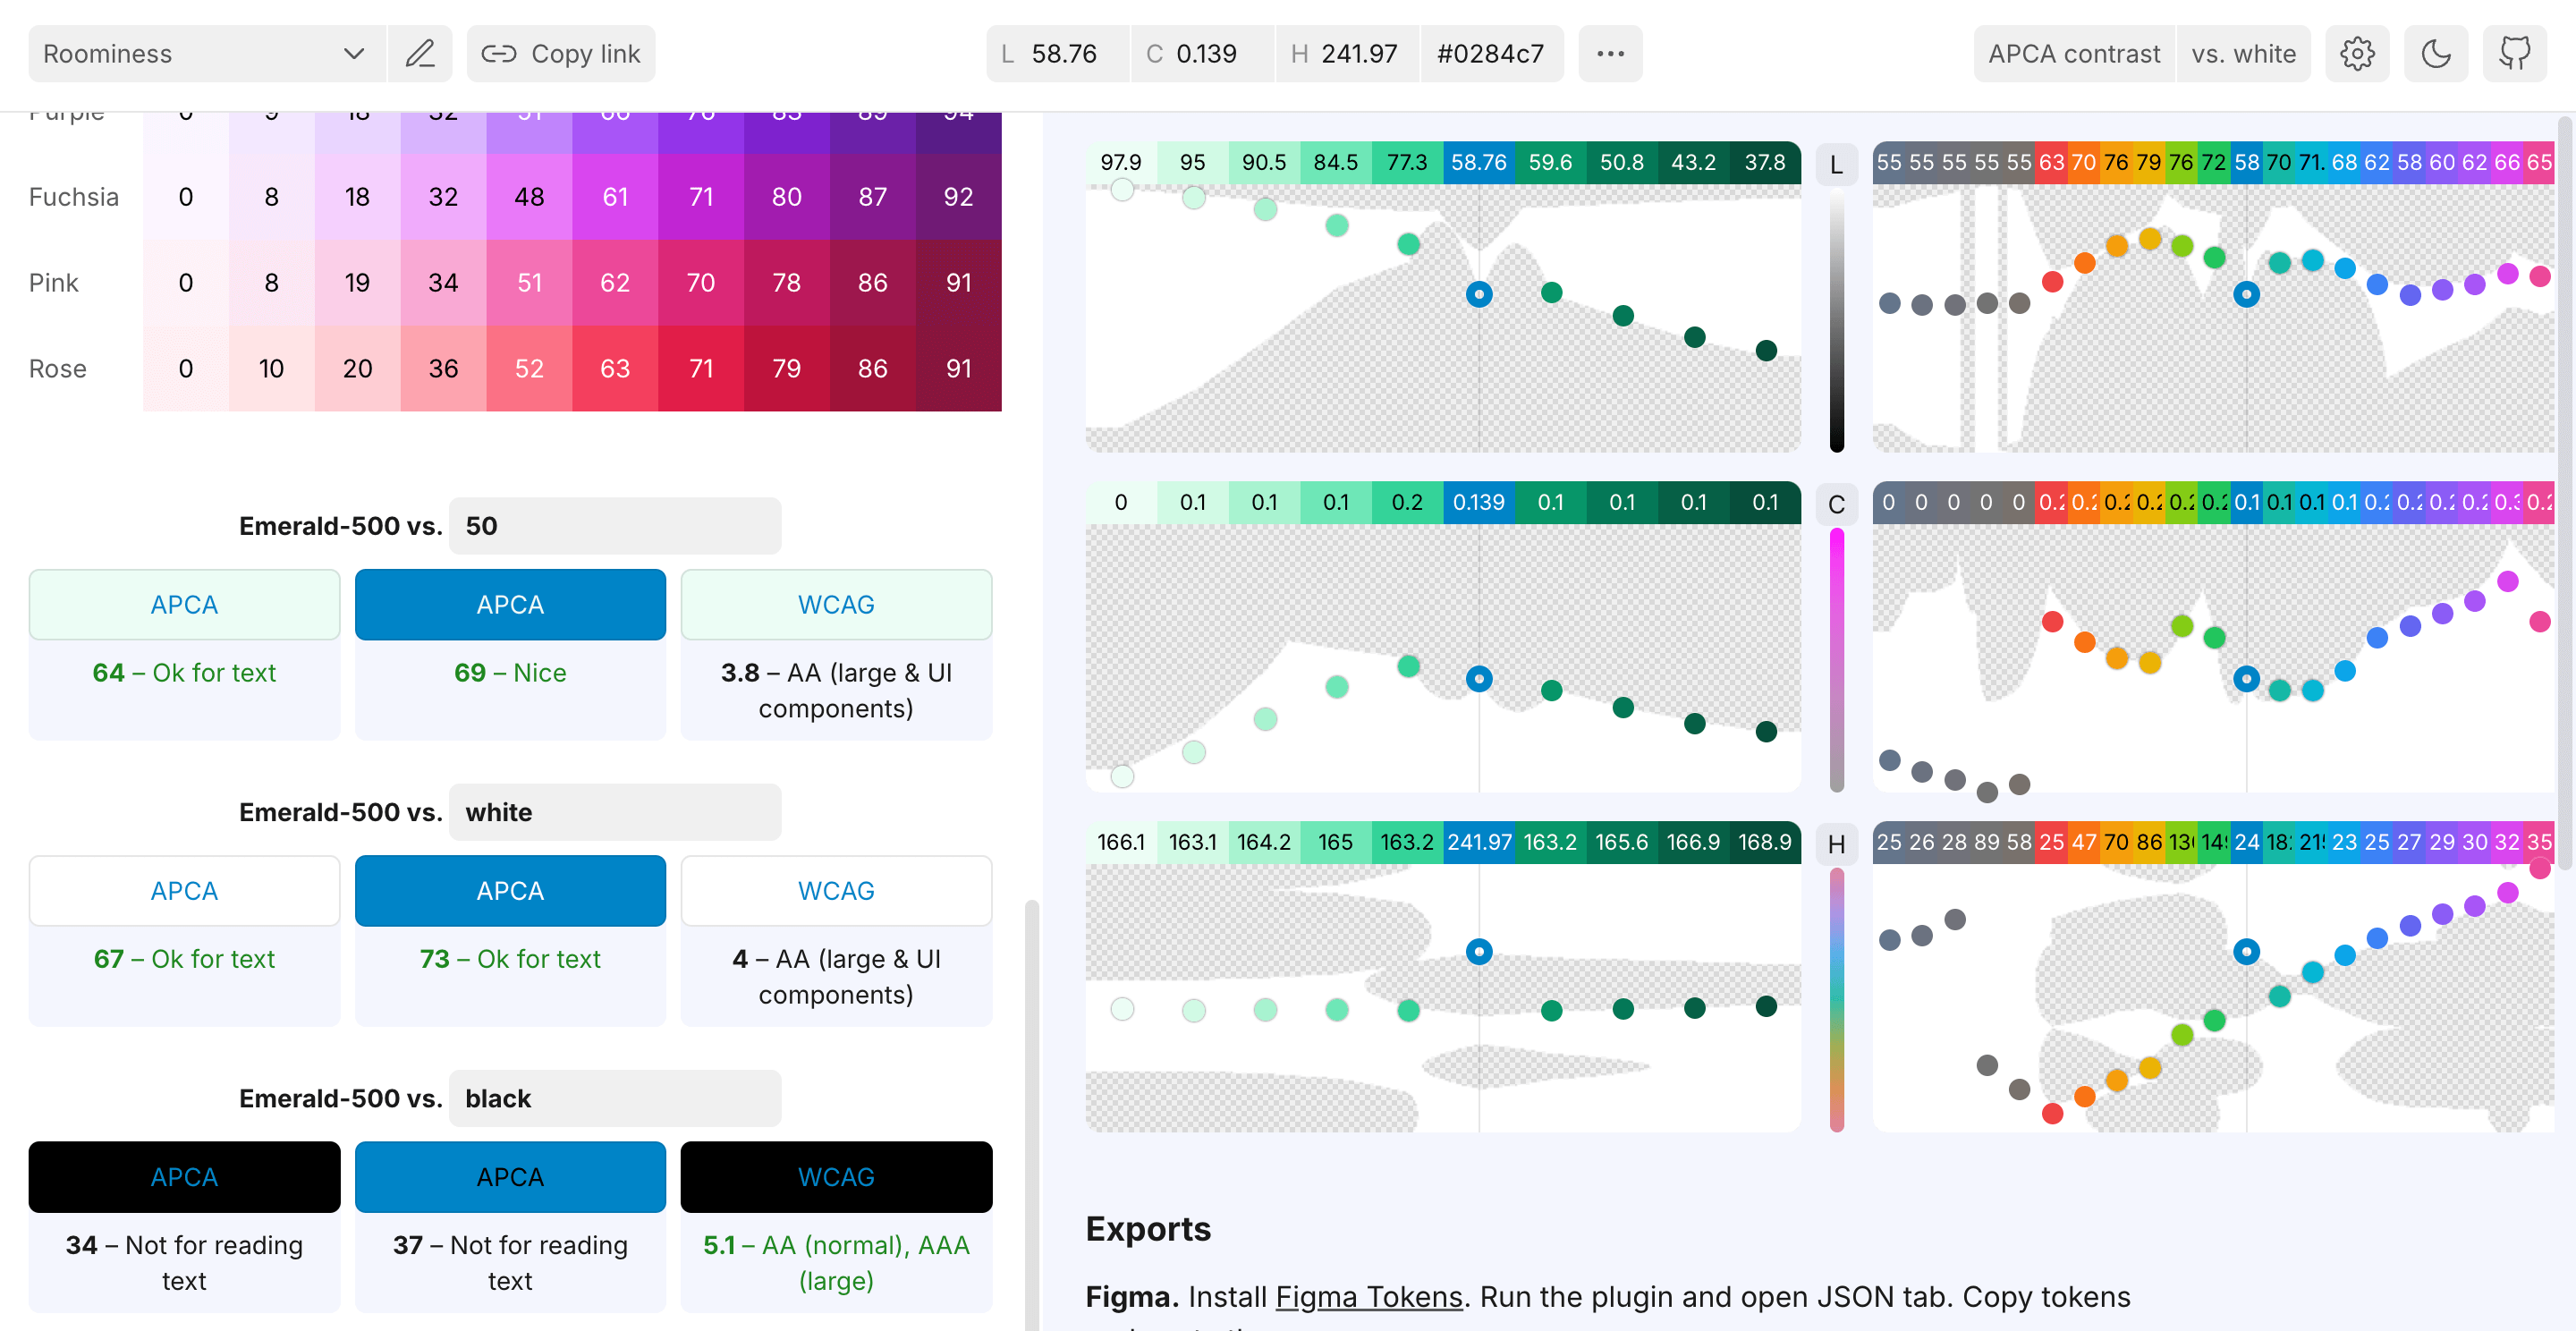
设计侧需要定义字体颜色、主题色,功能色用不太到。如果还需要适配暗黑模式的话,需要再多加考虑色彩在暗黑模式下的显示效果。布局框架也需要提前定义,如果不是特别个性化的网站,几个功能模块的位置也是不会变化的。定义好色彩、布局这两部分之后,开发也可以同步开展了。
### 前后端开发
开发这块我主要以介绍前端开发为主,后端方面了解的不多。
#### 前端环境配置
以 Mac 为例,进行前端开发需要准备以下工具:
- 代码编辑器: Visual Studio Code (VS Code):用于编写和管理代码的软件
- 运行环境: Node.js:允许在计算机上运行 JavaScript 的平台
- 版本控制系统: Git:用于跟踪和管理代码变更的工具
- 包管理器: Homebrew (可选):简化 Mac 上软件安装过程的工具
基本的流程是先安装软件市场,然后在软件市场中安装 Node.js、Git、VS Code 等开发相关软件。安装完毕就可以在 VS Code 中写代码,用 Node.js 构建出你的博客。然后通过 Git 记录你的代码的修改日志,方便管理。
在 macOS 的终端运行以下命令可以配置你所需的前端环境:
```zsh
# 安装 macOS 软件包管理:brew
/bin/bash -c "$(curl -fsSL https://raw.githubusercontent.com/Homebrew/install/HEAD/install.sh)"
# 通过 brew 安装 VS Code、git
brew install --cask visual-studio-code
brew install git
# 安装 node 管理工具:nvm
curl -o- https://raw.githubusercontent.com/nvm-sh/nvm/v0.40.1/install.sh | bash
# 通过 nvm 安装长期支持的 node 版本
nvm install --lts
# (可选)安装 pnpm 软件包管理器
npm install -g pnpm
```
前端所需环境就配置完毕了,有额外需要安装也可以通过 `brew` 软件市场安装。网络问题需自行解决。
#### 前端技术选型
前端环境是开发所有前端项目的基础。现在我们需要考虑有关这个项目的技术选型了。
正如我们之前讨论的,「内容框架」对技术选型有重要影响。为了帮助您更好地做出选择,我整理了一张基于内容特性(静态/动态)的「技术选型」推荐表。
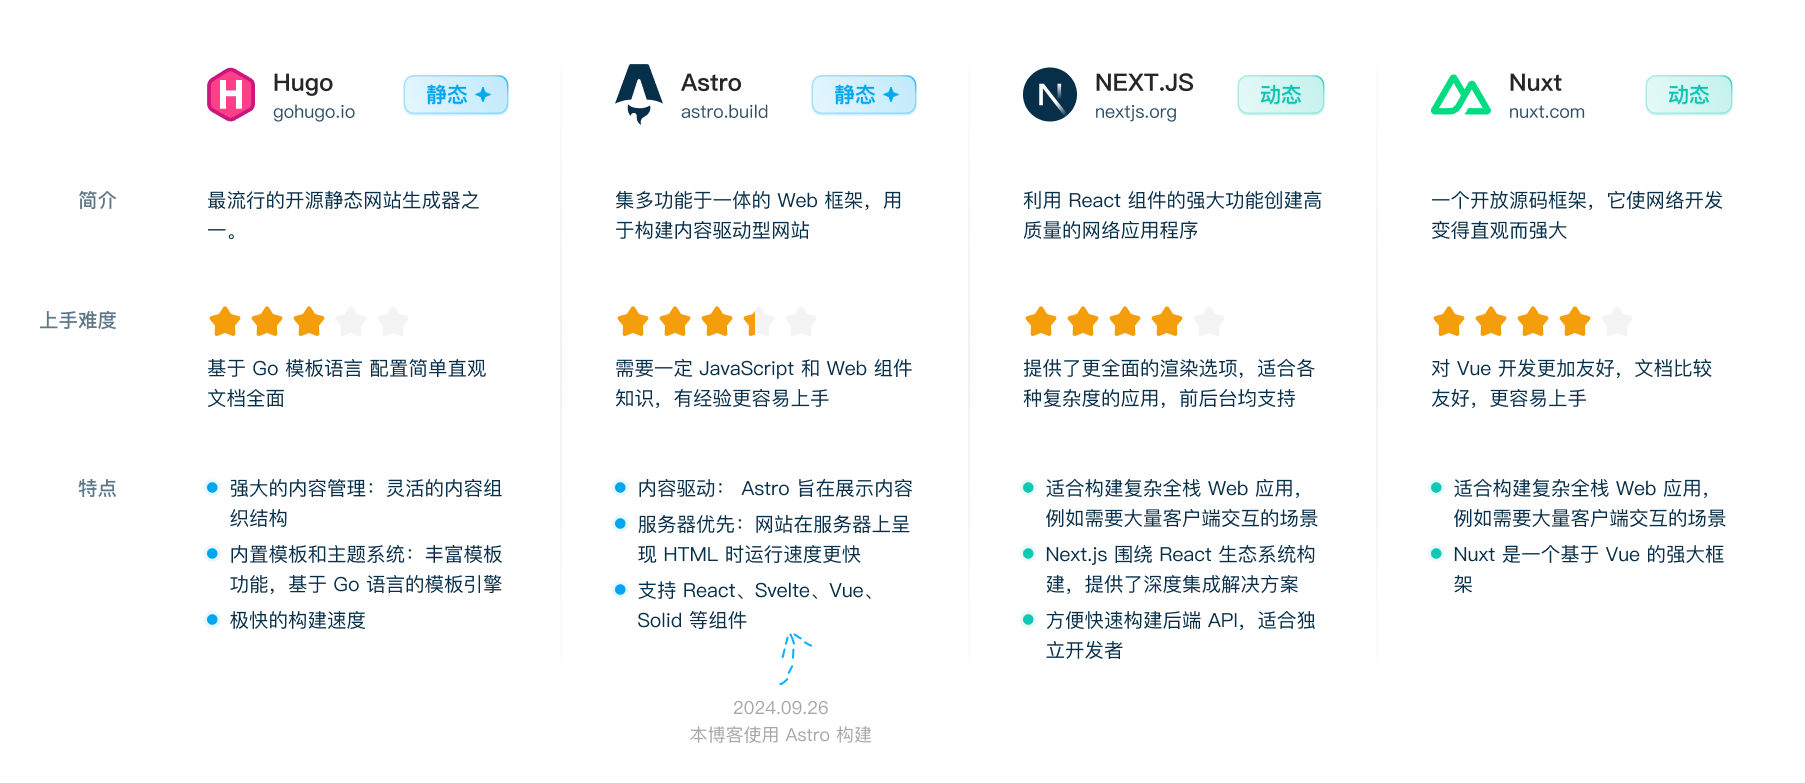
我使用过表格中的 [Hugo](https://gohugo.io/)、[Next.js](https://nextjs.org/)、[Astro](https://astro.build/),而 [Nuxt](https://nuxt.com/) 是 Next.js 较有力的基于 Vue 的竞争者。我的博客也经过了从 Hugo -> Next.js -> Astro 的变化,也算是有一点点说服力。
在这几个框架里,[Astro](https://astro.build/) 是我目前比较推荐的,具体原因如下:
1. Astro 构建的网站性能卓越,加载速度足够快
2. Astro 原生支持 Markdown,非常适合作为博客的框架
3. Astro 学习曲线相对平缓,只需要熟悉 HTML、CSS 和 JavaScript
4. 静态构建方便我后期分平台快速部署
5. 我购买的服务器性能较弱,纯静态对服务器要求低
6. 静态内容也非常适合配置 CDN 加速
你也可以查看 [2023 年网络框架性能报告](https://astro.build/blog/2023-web-framework-performance-report/),报告中对比了 Astro、Next.js等网络框架的性能,或许能够辅助你进行选择。
环境配置完毕后,以 Astro 项目为例,我们可以参照 [Astro 文档](https://docs.astro.build/en/install-and-setup/) 所说的创建一个基于 Astro 的新项目:
```zsh
# 如果没有安装 pnpm,npm 请使用 npm create astro@latest
pnpm create astro@latest
```
接下来,你就可以找一些教程来一步步学习怎么基于 Astro 写代码了,上手难度不高的。
项目初始化完毕,你可以会想,我怎么跟设计侧的规范链接在一起。我在使用的是 [Tailwindcss - 实用至上的 CSS 框架,用于快速用户界面开发](https://github.com/tailwindlabs/tailwindcss)。这就像项目的插件,可以帮你更好进行前端开发。在 Tailwindcss 中,你可以预先定义字体、主题色、功能色,甚至间距、圆角等等。这时候就跟你设计时定义的色彩等规范不就配合在一起了嘛,配置一次,用起来、统一调整起来都很方便。
```zsh
# 如果没安装 pnpm,npm 请使用 npx astro add tailwind
pnpm astro add tailwind
```
Tailwindcss 配置示例:
```js title="tailwind.config.js"
/** @type {import('tailwindcss').Config} */
module.exports = {
darkMode: ['selector'], // 暗黑模式支持
theme: {
colors: {
white: '#ffffff', // 定义颜色名称 调用方式:text-white bg-white
black: '#000000',
brand: {
500: '#0ea5e9', // 定义品牌色 调用方式一致:text-brand-500
600: '#0284c7',
},
},
},
};
```
#### 后端开发
前面我们选择了 Astro 作为技术栈,这比较适合静态内容的开发。如果你的博客需要很多动态数据,需要一个简单的后端,那么我推荐你使用 [Next.js](https://nextjs.org/) 或者 [Nuxt](https://nuxt.com/)。
基本流程:
1. 有一个数据库(推荐 Supabase 免费或者国内云商的数据库)来存储你的数据
2. 通过插件 [Prisma](https://www.prisma.io/) 链接到你的 Next.js 项目
3. 在项目中写逻辑代码来操作数据库中的数据
举一个查询我「近况」的 API 为例:
```ts title="api/route.ts"
export async function GET(req: NextRequest) {
// Get 方法
const number = Number(req.nextUrl.searchParams.get('number')); // 让程序知道你想要几条数据
const records = await prisma.recent_states.findMany({
take: number, // 程序知道之后,去数据库对应数量的数据
orderBy: { created_at: 'desc' }, // 排序方法 按照时间降序
});
return Response.json(records); // 返回 json 格式的数据 方便返回到页面中
}
```
通过 `Get` 方法调用这个 API 我就能够查询到我的近况,然后将其展示在博客上,让你看到,了解我最近发生的事情。
相对于静态内容,需要进行的操作变多了。这多了向数据库查询、处理的过程。如果数据库访问速度,或者你的云服务器性能不好,这也将直接影响到你网站的访问速度。而且动态内容也不适合部署在传统 CDN 分发。网站访问速度不行的话,就应该放弃动态内容了。
### 部署上线
博客在本地开发测试完毕之后,推荐上传到 [Github](https://github.com/)。Github 是使用 Git 进行在线项目托管。这个平台类似是文件的版本管理工具,其能够管理你项目的代码。
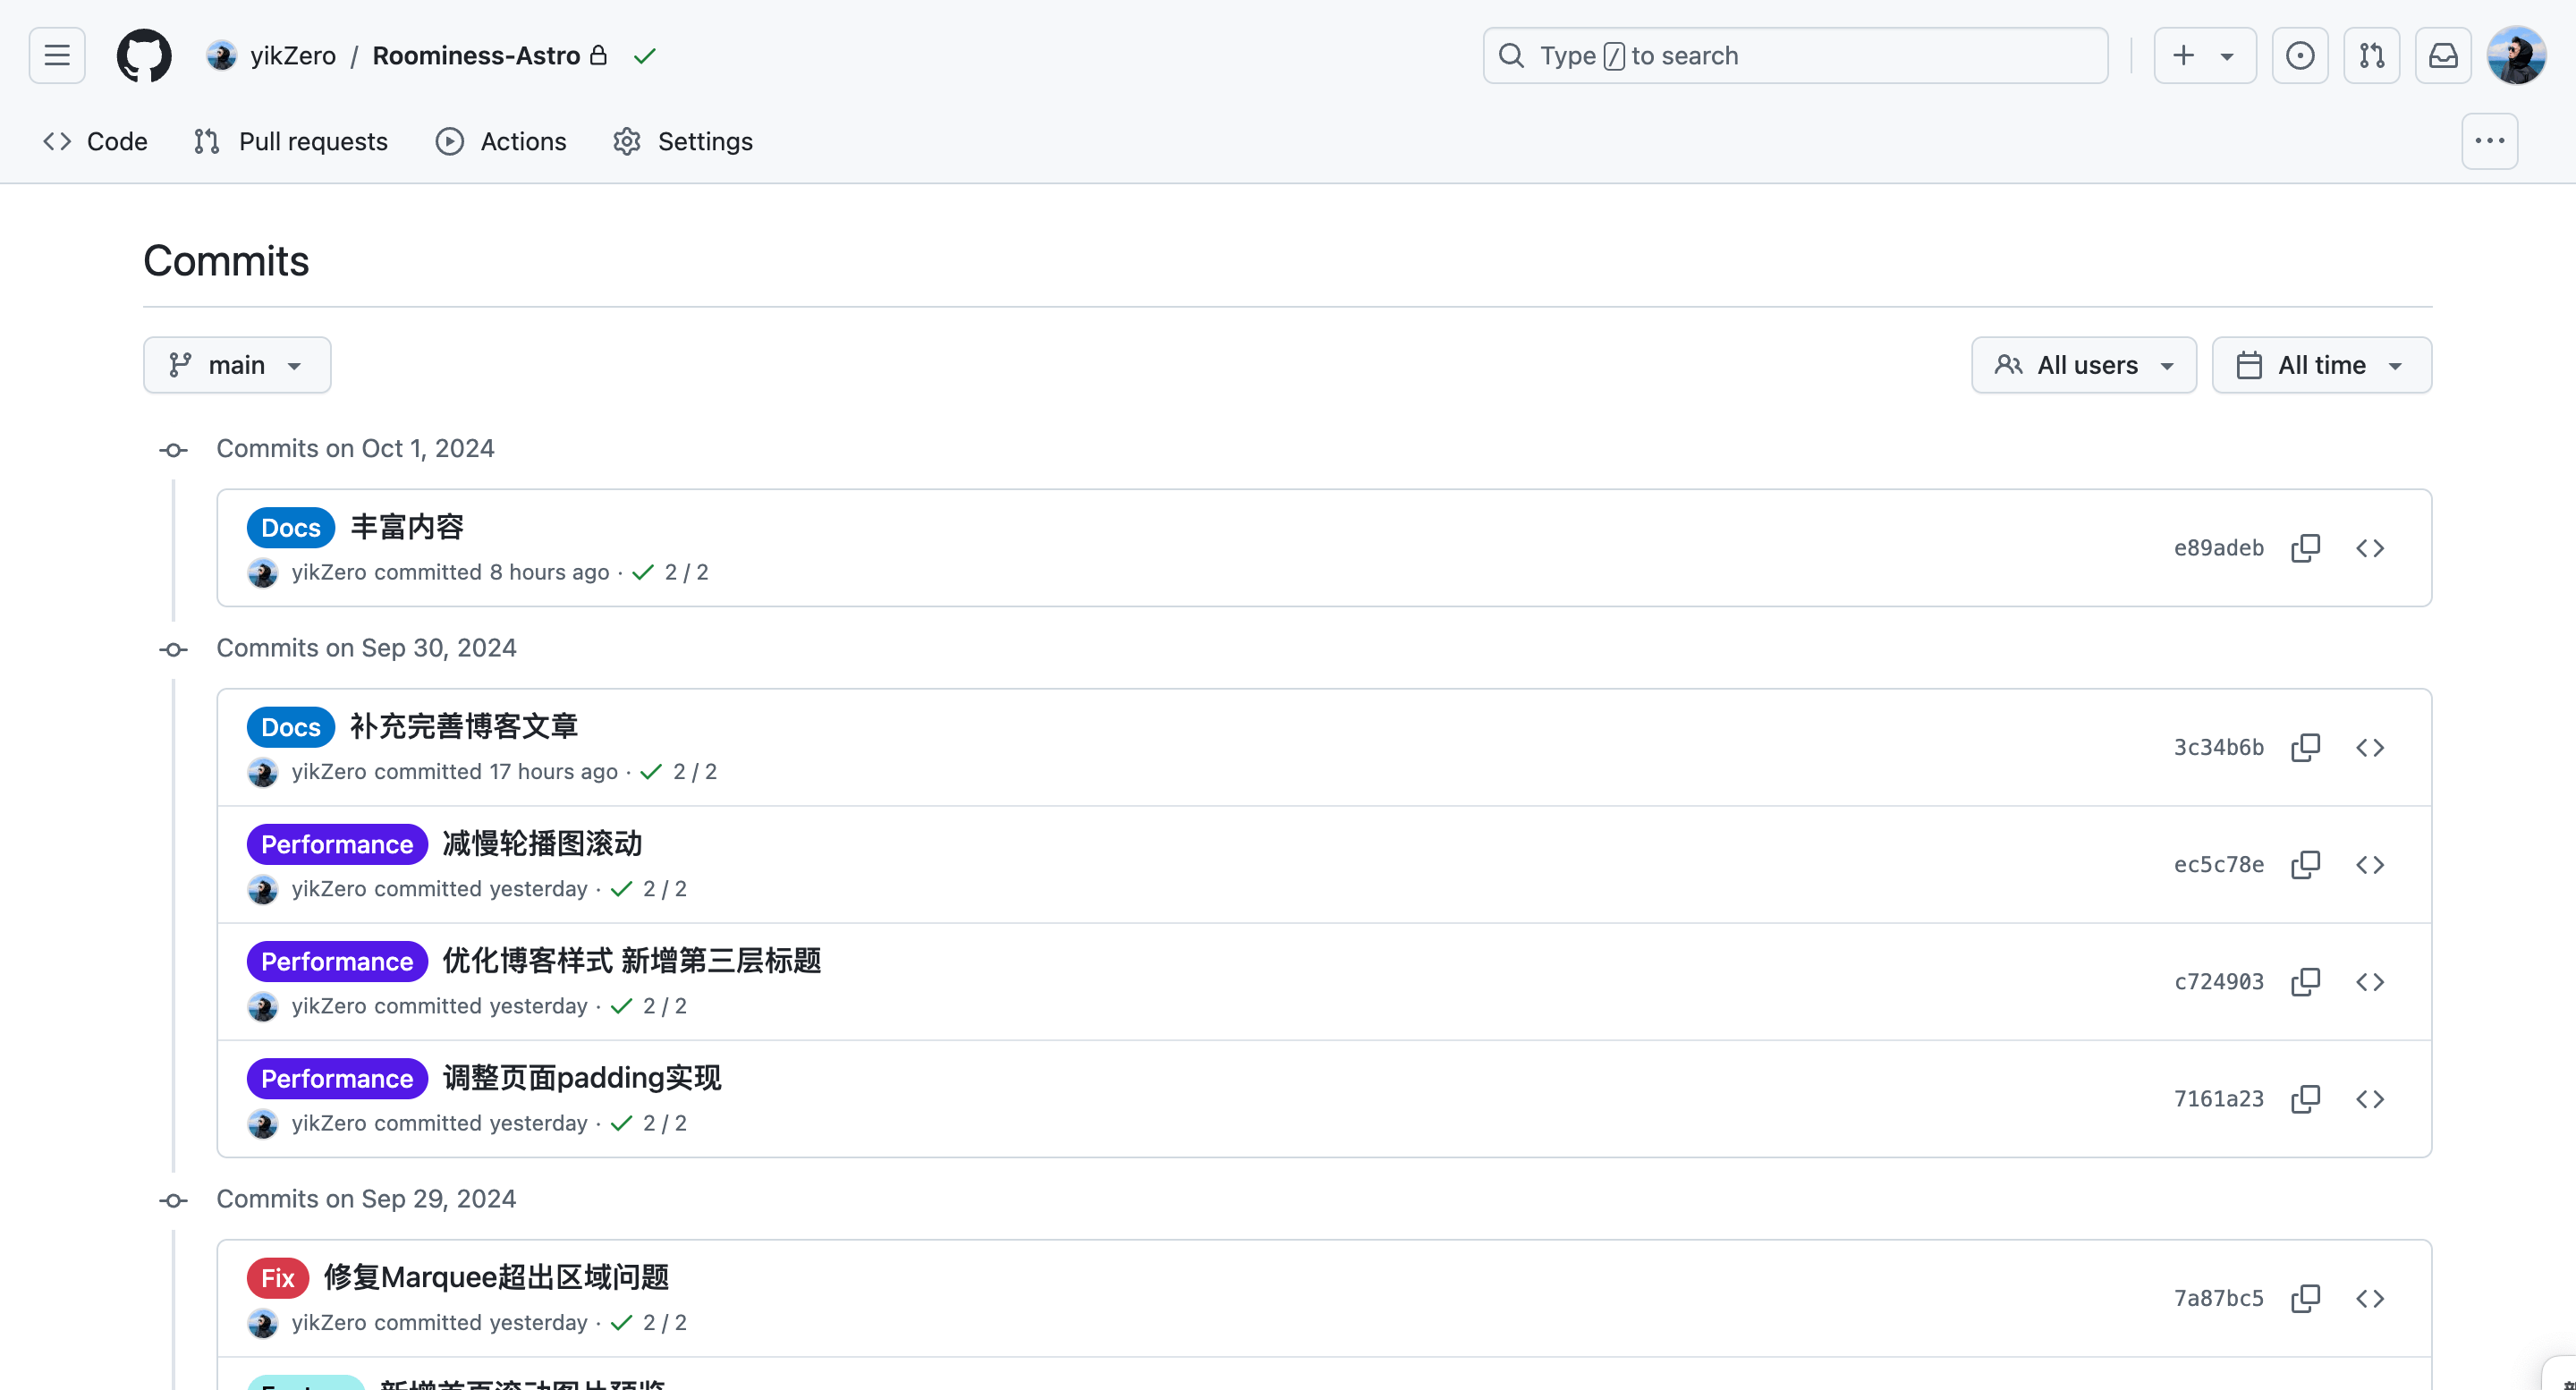
每次修改一个代码的问题,就可以提交到 Github 上。如果哪次项目代码构建出问题了,可以非常方便进行回滚。
博客开发完毕后,我们主要是想其被别人看到。那么,我们就需要有一个地方承载网站,这个地方也需要能够被大家访问到。例如:具有外网 IP 的家庭设备、云服务器、轻量应用服务器、Paas 平台等。
家里的笔记本其实是可以作为承载网站的设备的,前提是你需要有外网 IP,其他人能够在互联网中访问到你。目前外网 IP 都需要跟客服去申请。将笔记本作为服务器的话,你的设备也不能够关机等。也还是有一些局限性的。
所以目前大部分人还是主要会把网站部署在云服务器、轻量应用服务器上,这些都具有外网 IP,同时是 24 小时开机的,非常适合作为网站服务器,性能不需要太好的话,一年 99 元等设备就够了。还是挺实惠的。如果你还是学生,你可以在阿里云拿到免费的服务器。
以云服务器为例简单介绍一下流程:
1. Linux 服务器跟 macOS 系统一样,需要安装配置前端环境,然后进行构建
2. 如果文件不是很大的话,也可以在本地构建完毕然后上传 `dist` 包到服务器上
3. 配置好 nginx 转发,你就可以通过云服务器 IP 地址访问你的网站了
4. 如果不想直接通过 IP 地址访问,你也可以购买一个自己的专属域名,国内几家较大的云商平台都能够购买域名
5. 购买域名之后,你需要进行 DNS 解析,这一步步骤你可以在你购买域名的平台或者专门的 DNS 解析平台来处理,例如 [Dnspod](https://www.dnspod.cn/)
6. 将 A 记录的 IP 地址与域名绑定,这样,你就能通过域名访问到你的网站了
以上介绍了一个简单的流程,如果需要详细的部署上线流程,你也可以参考左子祯老师的文章:[写给设计师的个人网站搭建指南(一):从域名到网站](https://zuozizhen.com/blog/website-for-designer-1/)
如果,你不想用自己的服务器,你只想设计、写写代码,那其实也有很多平台来补齐服务器、域名这两步走,这些平台通过授权之后从你的 Github 仓库中拉取你项目的代码,然后在他们的云平台上构建并发布到网络上。
类似的平台有 [Vercel](https://vercel.com/)、[Zeabur](https://zeabur.com/)、[Cloudflare Page](https://pages.cloudflare.com/)等。如果不想维护自己的云服务器,这种也是不错的方式。
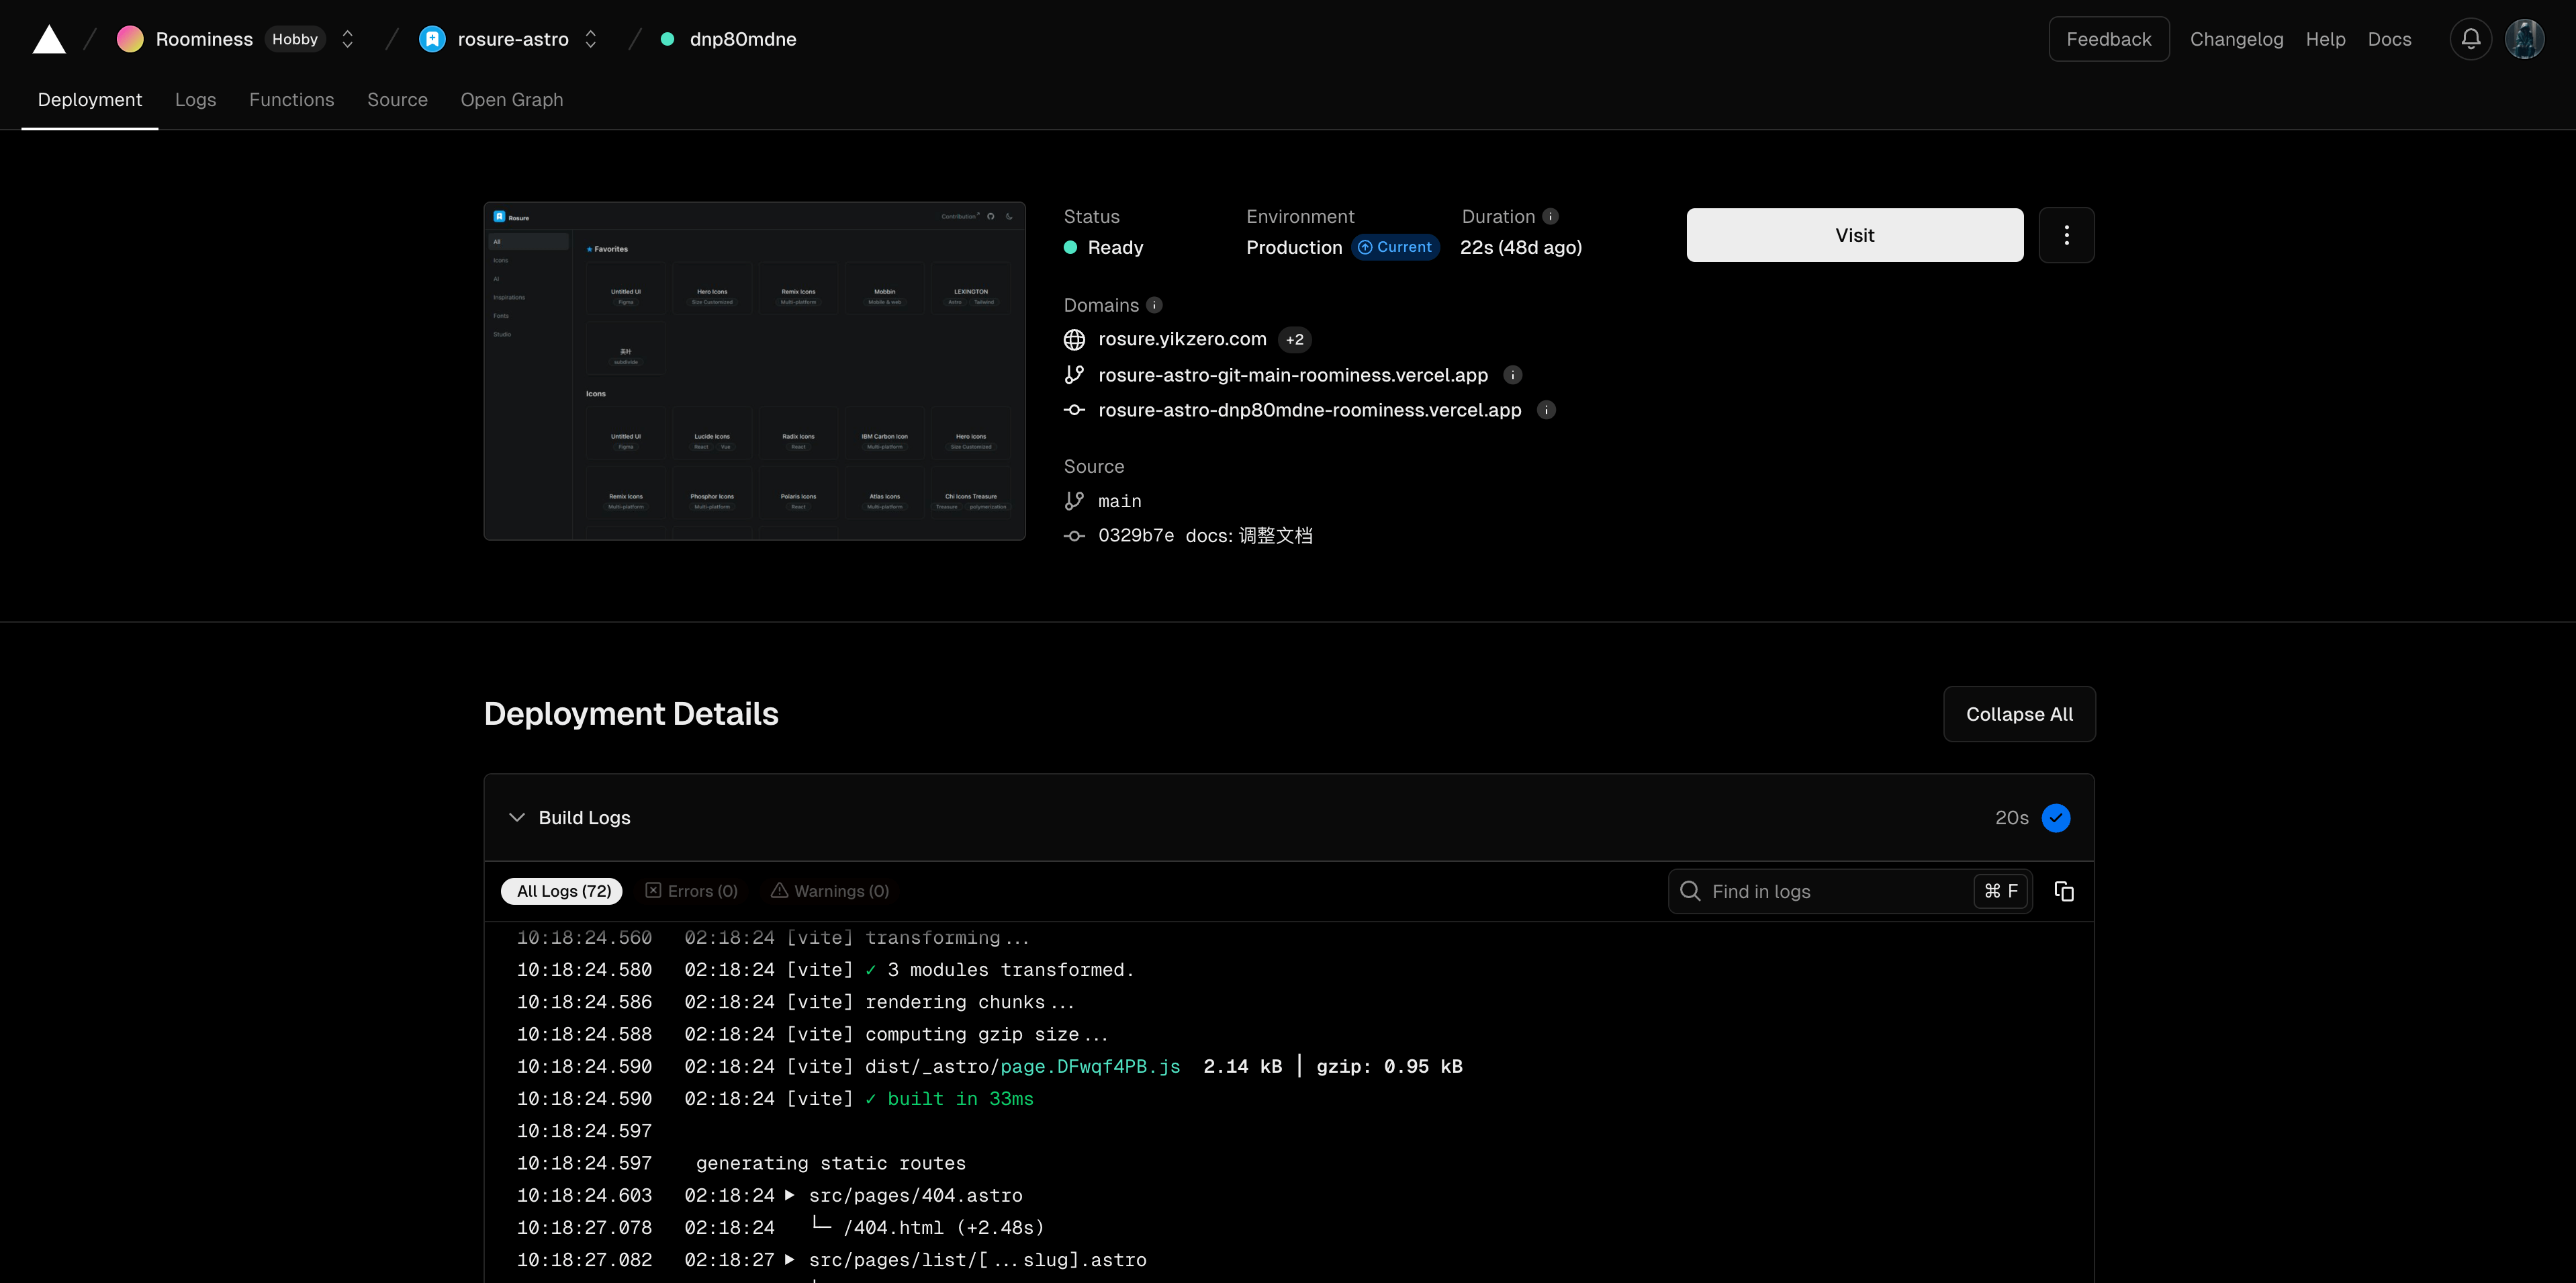
以 Vercel 为例简单介绍一下流程:
1. 创建 Github 仓库,将本地项目代码通过 Git 上传到 Github 私有仓库中。
2. 注册登录 Vercel 平台,赋予平台读取 Github 仓库权限,选择对应项目仓库。
3. 自动识别项目框架,点击按钮进行构建,平台会展示构建日志,如果出问题也可以及时排查。
4. 构建完成,平台会免费提供二级域名供你使用,你直接访问域名就能够在看到你的网站已经发布到网上了。
5. 你也可以选择购买域名,然后根据平台提示,将项目与你拥有的域名绑定。
以上提供了两种将网站部署到外网的方式,你可以按照自己的喜好以及难度进行选择。这两种方式也是可以进行结合的。
### 总结
由于篇幅问题,每一部分流程都讲到了,但是也没有讲的非常细节,还是需要你们自己去多查询其他资料。这篇文章只能提供大致方向性的知道,希望这个开发流程的介绍能够帮助到你。
## 设计&开发工具推荐
众所不知,我挺喜欢屯东西的,所以在网站开发这块,我也收集到不少好用的工具等,趁这个机会跟大家分享下,或许能帮助到你的开发。
### 设计
| 名称 | 描述 | 分类 | 推荐程度 |
| ------------------------------------------------------------------------ | ------------------------------------------ | ---- | -------- |
| [**Figma**](https://figma.com/) | 协作式界面设计工具 | 通用 | ⭐⭐⭐ |
| **Rosure**(已失效) | 我的设计收藏夹,包含图标、字体、网站灵感等 | 灵感 | ⭐⭐⭐ |
| [**Toolfolio**](https://toolfolio.io/) | 设计工具、灵感聚合 | 灵感 | ⭐⭐⭐⭐ |
| [**Tailwind CSS 梯度色彩生成**](https://uicolors.app/create) | 根据你提供的颜色,生成色彩阶梯 | 色彩 | ⭐⭐⭐ |
| [**Palettte**](https://palettte.app/) | 明确的调色板编辑和重映射工具 | 色彩 | ⭐⭐⭐ |
| [**Radix Colors 自定义调色板**](https://www.radix-ui.com/colors/custom) | 生成色板,并且能够预览效果,支持暗黑 | 色彩 | ⭐⭐⭐ |
| [**Huetone**](https://toolfolio.io/) | 创建无障碍色彩系统的工具 | 色彩 | ⭐⭐⭐ |
### 开发
| 名称 | 描述 | 分类 | 推荐程度 |
| ------------------------------------------------------------- | ----------------------------- | ---- | -------- |
| [**Homebrew**](https://brew.sh/) | macOS(或 Linux)软件包管理器 | 通用 | ⭐⭐⭐ |
| [**pnpm**](https://pnpm.io/) | 项目软件包管理器 | 通用 | ⭐⭐⭐ |
| [**nvm**](https://github.com/nvm-sh/nvm) | Node 版本管理器 | 通用 | ⭐⭐⭐ |
| [**Tailwindcss**](https://tailwindcss.com/docs/installation) | 实用至上的 CSS 框架 | CSS | ⭐⭐⭐⭐ |
---
---
title: "人工智能时代的视觉交互新范式"
description: "探讨了人工智能时代视觉交互的新范式,包括硬件和软件两个方面的创新"
canonical_url: https://ro.yikzero.com/blog/ai-ui-future/
locale: zh-CN
date: 2024-04-24
---
# 人工智能时代的视觉交互新范式
## 前言
我一直思考,在人工智能时代,这些我们习以为常的「工具」会以一种什么样的形态展示?
当前,人工智能最普遍的应用方式通常局限聊天界面,它们通常采用一种基于文本的问答模式进行交互。随着技术的不断进步,Vercel 也推出了能够根据对话内容和需求动态生成定制化的交互式用户界面 [Generative UI](https://sdk.vercel.ai/docs/concepts/ai-rsc) 。未来的 UI 会是怎么样的一个形态,会演变成电影中所展示的那样,拥有炫酷的全息显示和直观的交互式 HUD,或者,我们可能会迎来一个不再依赖传统 GUI 的新时代?
> Natural language becoming the fundamental interface for every software application might mean the end of GUIs
## 胡思乱想
以后是不是我可以直接一句「Siri,帮我订个飞机票。」,或者直接就跟马斯克做的脑机实验一样,只需要一个想法即可传递信息。需要呈现的信息,直接展示在眼球前(这样的话,盲人也能看得见吗?),不需要再外接其他设备。需要操控的内容也可像 VR 眼镜一样通过手指、眼球进行交互。以后或许就真的像[黑镜](https://www.themoviedb.org/tv/42009-black-mirror)一样了。
## 调研
### AI Pin
Humane 推出的 Ai Pin(官网已失效)算是一位先行者,这款产品通过磁性夹在衣服上,它没有屏幕,通过语音和小型触摸表面进行控制。有一个激光可以将图像投射到你的手掌上,它还有一个摄像头,可以识别手势进行切换等操作。
其目前及未来可能支持的功能:激光投影显示、手势和语音交互、AI助理、实时翻译、健康监测、音乐播放、消息提醒等等

### Rabbit
[Rabbit R1](https://www.rabbit.tech/rabbit-r1) 是一款由Rabbit公司推出的AI设备,定位为您的口袋伴侣。主要由屏幕、摄像头、滚轮、按钮组成。
其目前及未来可能支持的功能:理解并执行操作(打车、订餐、播放音乐)、实时翻译、教学模式等,可查看[评测视频](https://www.youtube.com/watch?v=ddTV12hErTc)

### Dot
[Dot](https://new.computer/) 是一个iOS上的聊天应用,用户可以通过它发送文字、语音备忘录、图片、PDF文件,并且它还能为你搜索网络信息。目前,Dot 通过文字进行交流,旨在成为一个随时可用的伴侣。与大多数AI对话不同,Dot能够记住你之前说过的话,几乎不会忘记任何事情。

### Amazon Lex
[Amazon Lex V2](https://docs.aws.amazon.com/lexv2/latest/dg/what-is.html) 是 AWS 提供的一项服务,它允许开发者构建应用程序的对话界面,支持语音和文本输入。用户可以利用自然语言进行交互,例如下单等操作。此外,Lex V2 还可以与网页元素(按钮、选择框等)集成,通过半引导式对话(Semi-Guided Conversations)来解决用户的问题或帮助他们完成特定任务。
### 总结
举的这几个例子不一定具有代表性,但也能简单的看出整体趋势:
- 硬件载体发生了转变。除了手机和电脑之外,人们也在尝试将内容呈现在更多便携式设备上,如项链、勋章和寻呼机等。
- 视觉图像的呈现方式更加多样化,例如投影和激光显示。由于尺寸的限制,主要以文本、简单图表和按钮信息为主要形式。
- 自然语言交互形式会运用的越来越广泛。
## 我的想法
#### **生成式 UI 是未来趋势**
目前,界面的设计必须满足尽可能多的人。任何有经验的专业设计人员都知道这种方法的主要弊端 - 你永远无法让任何人完全满意。个性化和定制发挥的作用也比较小。
这个应用场景跟支付宝首屏根据地点实现的动态个性化卡片也有些类似(在机场就展示机场相关信息)。
[Video](https://cdn.yikzero.com/markdown/images/2024042305.mp4)

而且生成式 UI 不只局限于动态卡片,其也可以根据个人数据为你动态展示一整个系统。[Generative UI and Outcome-Oriented Design](https://www.nngroup.com/articles/generative-ui/) 文中举例,这才是真正的千人千面:
- 有阅读障碍 - 应用程序展示特殊字体与颜色对比
- 注重费用、时间的用户 - 显性展示,自动增加对应航班权重
- 虽然是同个应用,但界面、功能等全是个人定制化的

设计师也将从普适设计转变为个性化设计,为各种个性化场景制定边界以加强对人工智能的约束。
#### **传统交互不会被取代,但会被极大简化**
尽管自然语言交互具有优势,但在需要快速精准输入的场景下,视觉元素如按钮、图标和手势仍是必需,纯语音输入可能会降低效率。并且也不是所有任务都能通过语音对话就能够很好完成的。
不同交互方式适合不同情况,视觉和语音输入/输出并存能最大限度满足无障碍设计原则,残障人士也能选择适合自身的方式。LLM 能够完成特定任务以后,界面将被极大简化。
另外,自然语言交互也不是所有场景都适用的,例如在公司、在图书馆等,也会造成隐私泄漏等困扰。
## 写在最后
虽然想尽可能展开写,但写着写着还是回到了 GUI 本身,只是想了想现有产品的未来形态...
## 参考资料
- [ScreenAI: A visual language model for UI and visually-situated language understanding](https://research.google/blog/screenai-a-visual-language-model-for-ui-and-visually-situated-language-understanding/)
- [The AI Device Revolution Isn’t Going to Kill the Smartphone](https://www.bloomberg.com/news/newsletters/2024-04-14/humane-ai-pin-review-the-device-isn-t-going-to-kill-apple-s-iphone-luziqlew)
- [Meet Dot, an AI companion designed by an Apple alum, here to help you live your best life](https://www.fastcompany.com/90975882/meet-dot-an-ai-companion-designed-by-an-apple-alum-here-to-help-you-live-your-best-life)
- [Malleable software in the age of LLMs](https://www.geoffreylitt.com/2023/03/25/llm-end-user-programming.html)
- [Generative UI and Outcome-Oriented Design](https://www.nngroup.com/articles/generative-ui/)
- [UFO: A UI-Focused Agent for Windows OS Interaction](https://arxiv.org/abs/2402.07939)
- [Ferret-UI: Grounded Mobile UI Understanding with Multimodal LLMs](https://arxiv.org/abs/2404.05719)
---
---
title: "UI 设计模块化研究:图标篇"
description: "全面介绍了 UI 设计中图标的重要性及其应用"
canonical_url: https://ro.yikzero.com/blog/icon-learn/
locale: zh-CN
date: 2023-11-11
updated: 2024-01-11
---
# UI 设计模块化研究:图标篇
## 背景
现有高质量图标库很多,例如 [Untitled](https://www.untitledui.com/icons)、[Lucide](https://lucide.dev/icons/)、[Remix](https://remixicon.com/),更加全面的也可以参考 [React Icons](https://react-icons.github.io/react-icons)、[Iconfont](https://www.iconfont.cn/)。
虽现有图标库这么多,但如果只是会根据含义选取图标的话...不是设计师,也可以做到。
不能「只知其然而不知其所以然」,那便从图标开始,了解设计背后的理论。
## 概述
UI 设计领域中,图标扮演着核心角色。它们将文字信息转化为视觉符号,简化用户对内容的理解,并增强界面的美观性。特别是在 B 端设计上,尽管图标的使用不如 C 端频繁、复杂,但在以表单为主的页面布局中,恰当合适的图标设计能够突显出产品甚至整个企业的风格和品牌调性。
最早的视觉传达方式基本上是通过图形进行的。这是北美印第安人在史前的岩洞壁画,虽然壁画都说是文字的前身,但个人感觉跟图标也很像。图标更像是一种通用语言,跨越了简体中文、英语、韩语等各种语言。
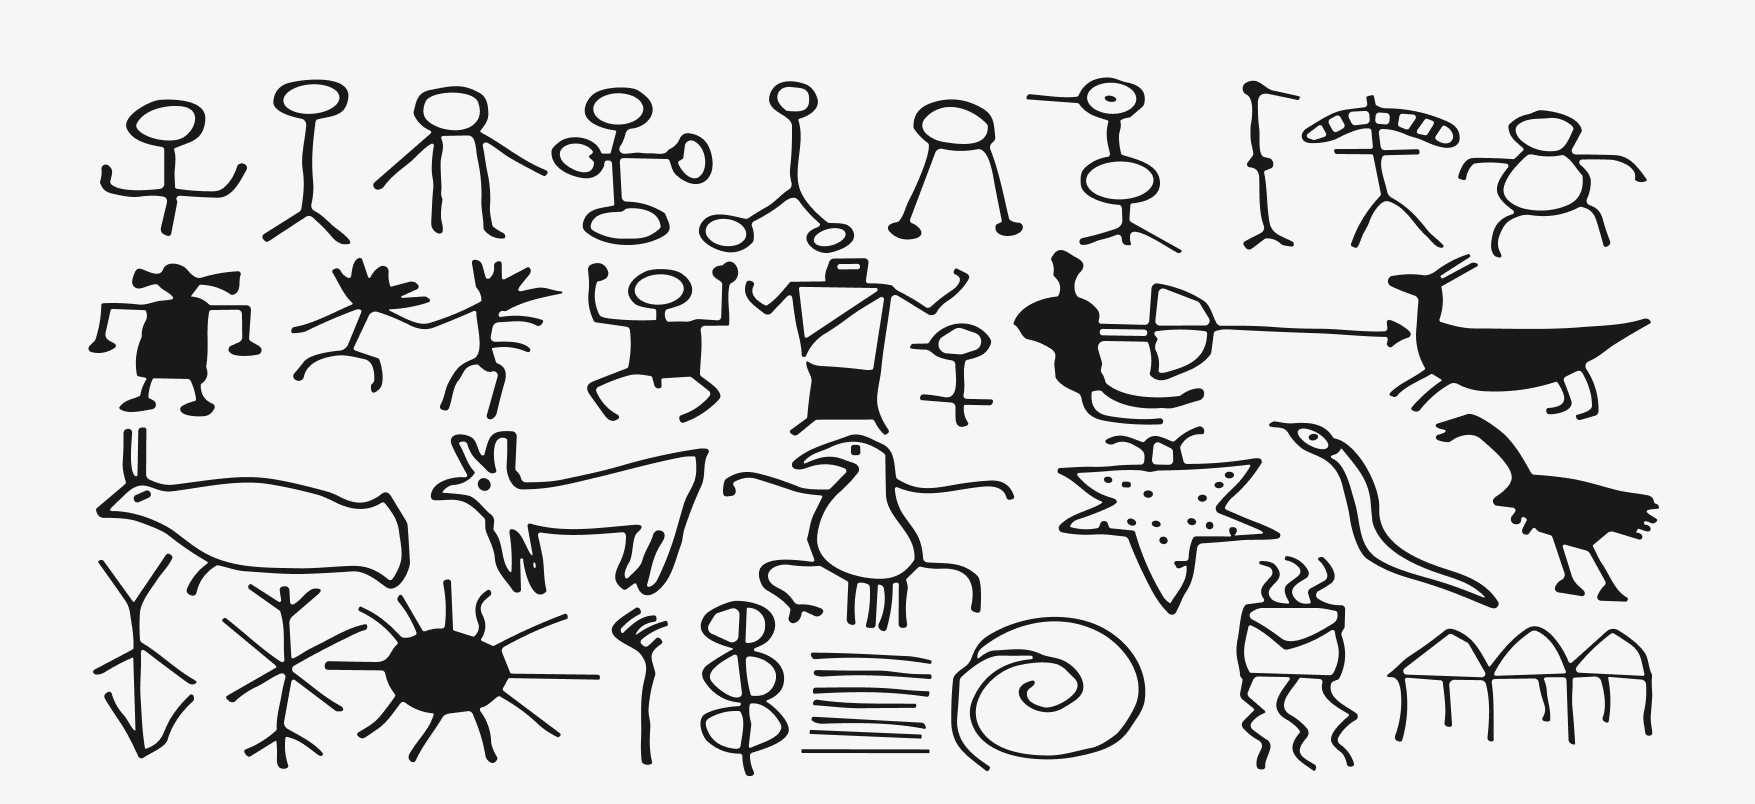
## 图标中的道道
首先,图标应清晰地表示物体、操作或创意。若用户无法查看/理解其含义,图标便成为华而不实的装饰,甚至阻碍任务完成。
### 图标尺寸
其实在使用各种组件库的时候,我便发现,这些库的图标都是基于 `24px` 尺寸。
找遍了网上资料,我发现了其可能的理由:
- 24px 尺寸确保图标在各种屏幕分辨率和设备上都保持清晰和易读。
- 24px 尺寸适应多种网格系统(例 [8-Point Grid System](https://medium.com/built-to-adapt/intro-to-the-8-point-grid-system-d2573cde8632#.5h95d066j)),便于设计师和开发者合作。
- 24dp\*24dp @x1 是 [Material Design 3](https://m3.material.io/styles/icons/applying-icons#661945dc-8621-41c6-b88d-bdb7c945b4e7) 规范推荐的图标「完美尺寸」。同时,Material Design 推荐最小触控区域 48dp。
暂未找到背后的数据支撑,且按照约定俗成来应用:
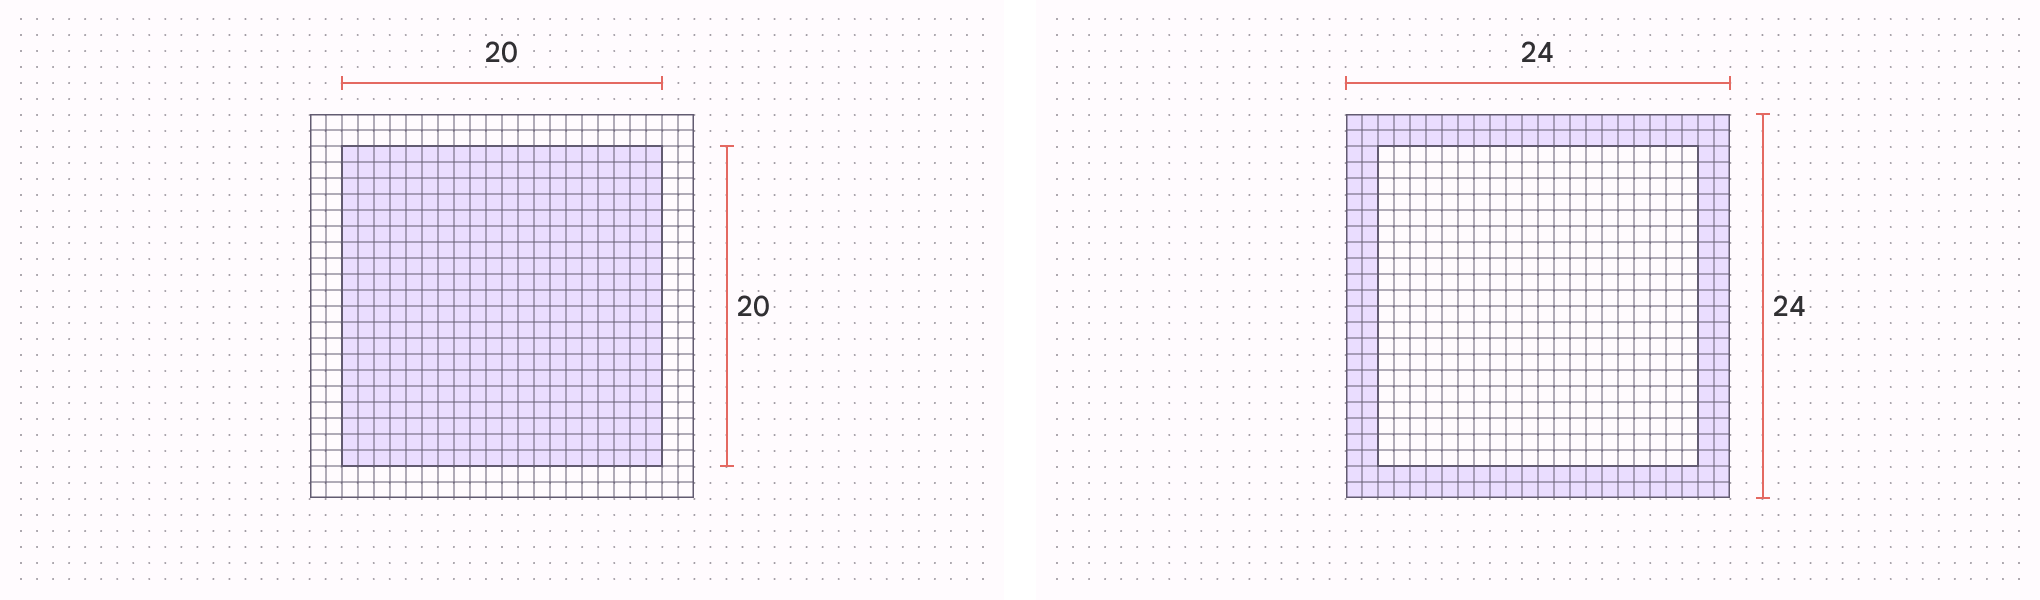
- 推荐的标准图标尺寸为 24px\*24px,通常周围留有 2px 的内边距,但这不是绝对的,具体边距应根据 Keyline 判断。相应的推荐触控区域尺寸为 48px\*48px。
- 在桌面环境中,图标大小可以调整为 20px\*20px,对应的触控区域建议为 40px\*40px。
- 16px 通常作为最小尺寸,在该尺寸下,图标应设计得更为简洁,此时其装饰性作用会更大于功能性。
「规矩是死的,人是活的」。我们可根据该指导原则,同时结合实际情况来应用。
px 与 dp 、pt 并不相等,其相互之间有自己的换算关系,具体可网上寻找资料。
### 图标样式
现有的图标样式纷繁复杂,早就不局限于线性、面性了。C 端的图标是更加的百花齐放。在这里我们暂且基于基础样式进行分析。
下面是我寻找到的 Untitled Icons 的图标样式:Line(线性)、Duocolor(线性多色)、Duotone(面性多色)、Solid(面性)。
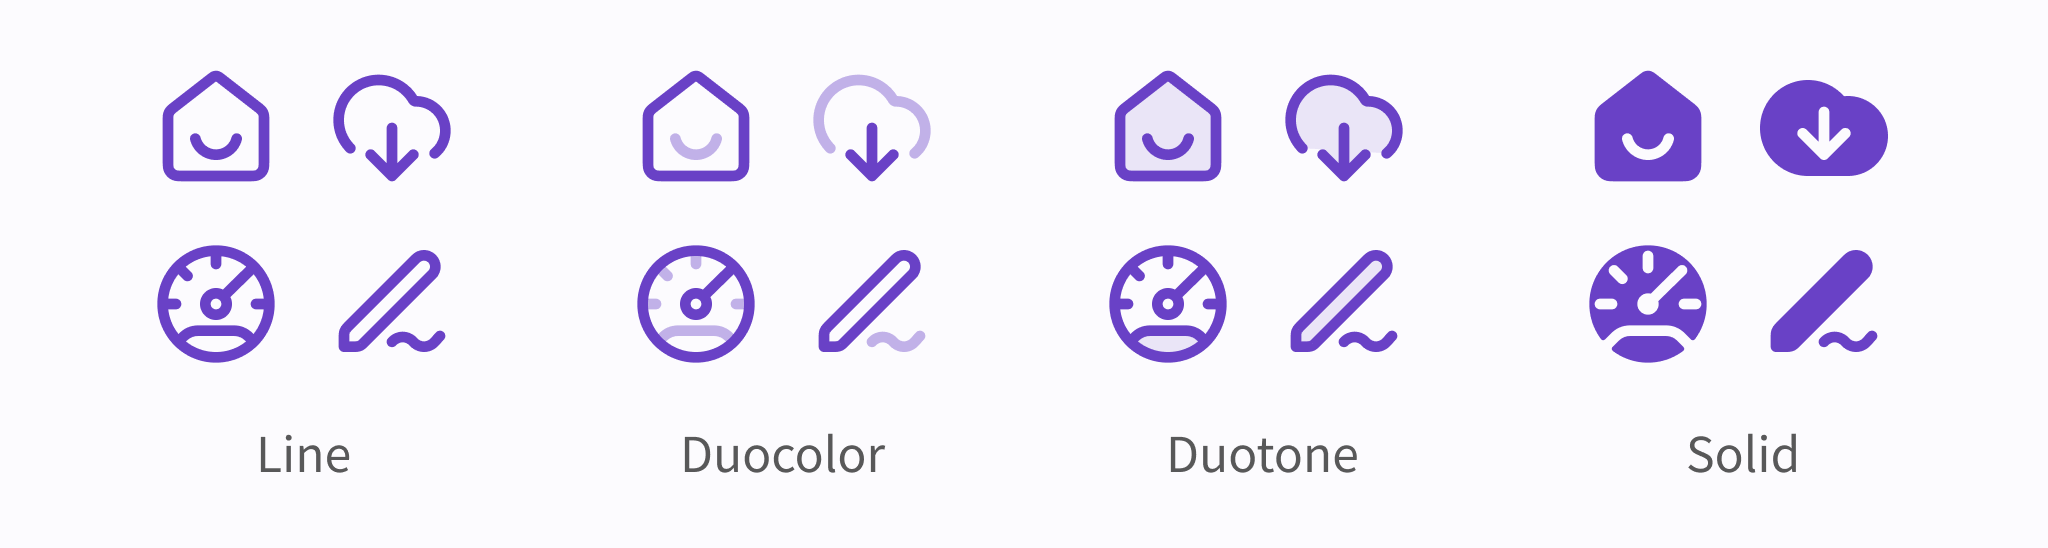
以上四种图标样式,基本能够满足 B 端设计所有的需求了。
如果按照更加细致的分法,Material Design 还将「线性图标」分成了:OutLine(轮廓)、Rounded(圆角)、Sharp(锐利)。
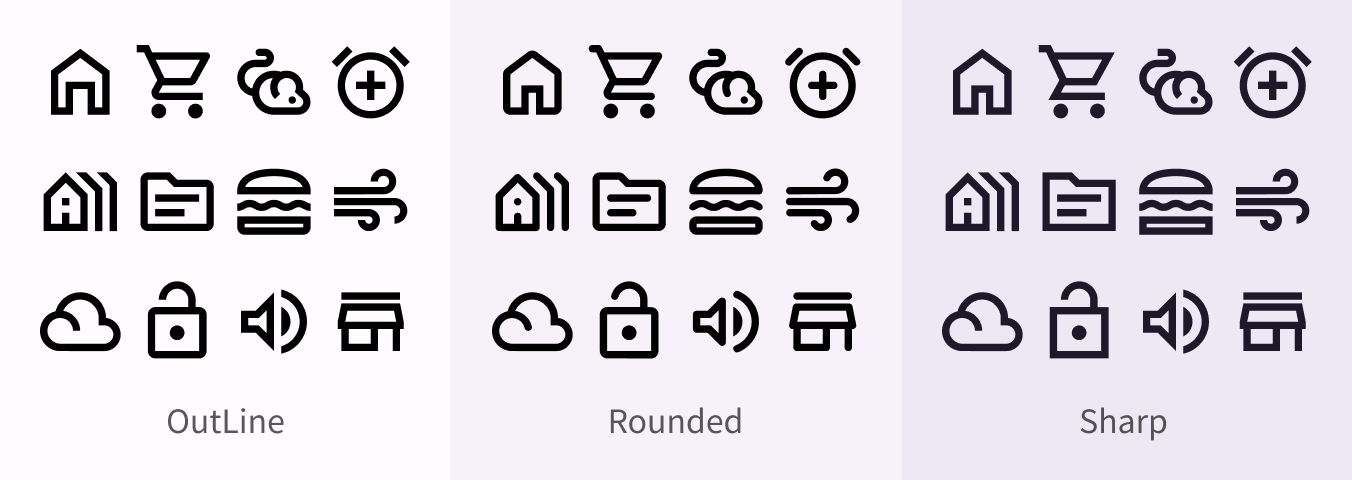
再加上线性图标的描边(Stroke)粗细、圆角(Radius)大小,这基本就能够满足企业、产品性格的定制化需求了。
另外,图标的风格不仅影响整体界面风格,还会影响图标的功能性和用户体验:
- 复杂的图标就不适合过小的尺寸(16px \* 16px 的图标需要更加简洁的线性样式)
- 面性图标整体上会比线性图标更容易识别,但具体需根据图标形状判断 [结论来源](https://cdr.lib.unc.edu/concern/masters_papers/6w924g35w)
## 图标设计
首先我想说,我从来就没有完全独立的设计过一个图标。以往如果没有满足需求的图标,我基本也是拿个类似含义的图标,然后简单调整一下其形状。
故,借着这个机会,我也可以接触一下图标的设计。Ant design 的[图标设计指引](https://ant.design/docs/spec/icon-cn)其实已经写了很多相关内容了,推荐先了解一下。
### Keyline 的使用
Keyline 是网格的基础。通过使用这些核心形状作为指导,我们可以在系统图标之间保持一致的视觉比例。
下图是根据 [Material Design 3 Icon design template](https://m3.material.io/styles/icons/designing-icons#8754553f-29d9-4671-b163-123b8e7b8f1e) 的规范绘制的 Keyline 网格。基于该网格,基本能够绘制各式各样的图标了。
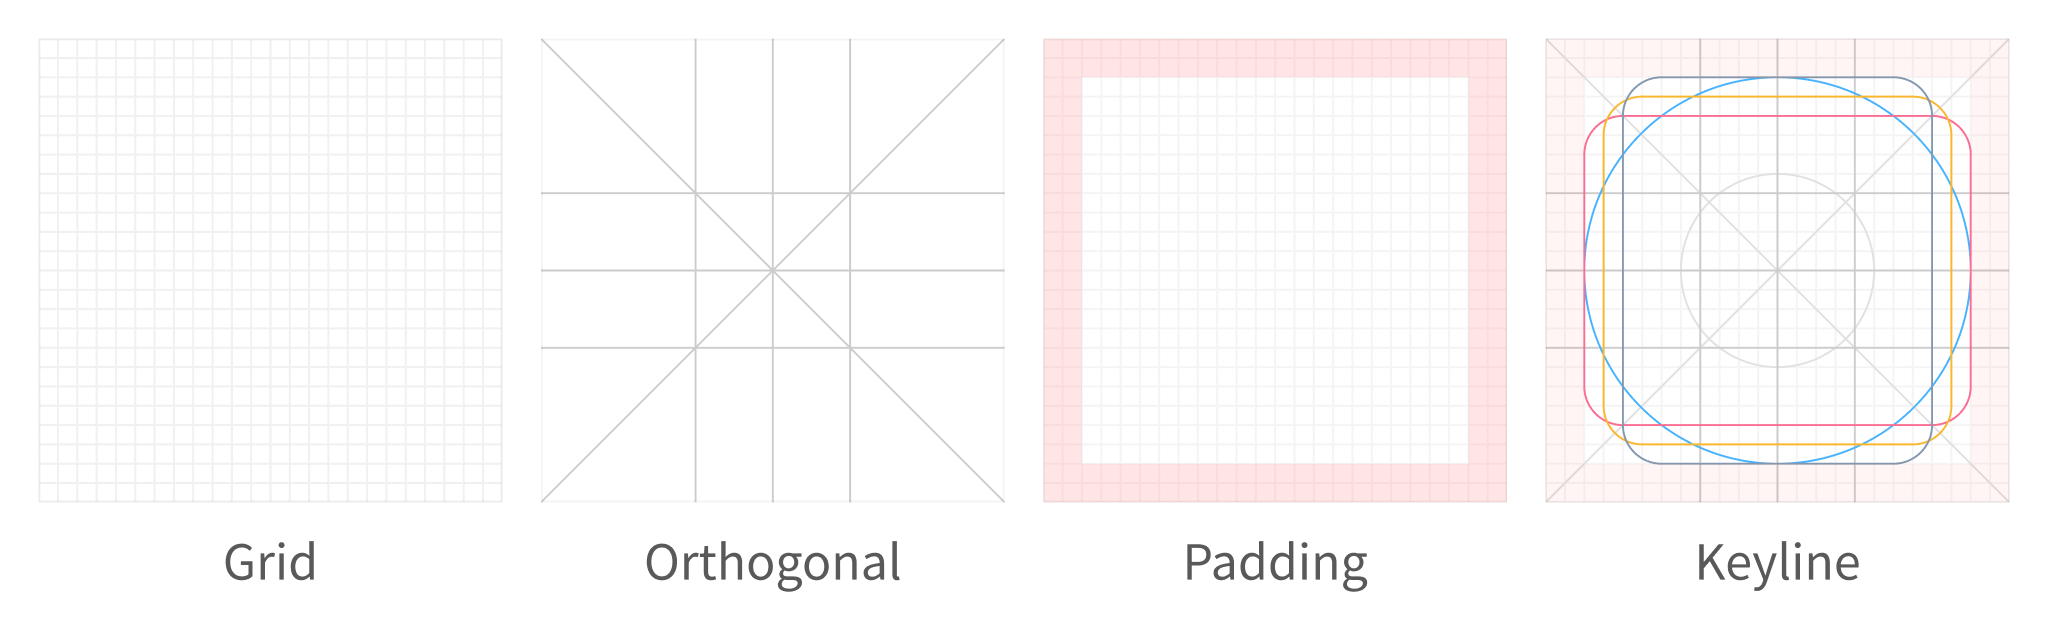
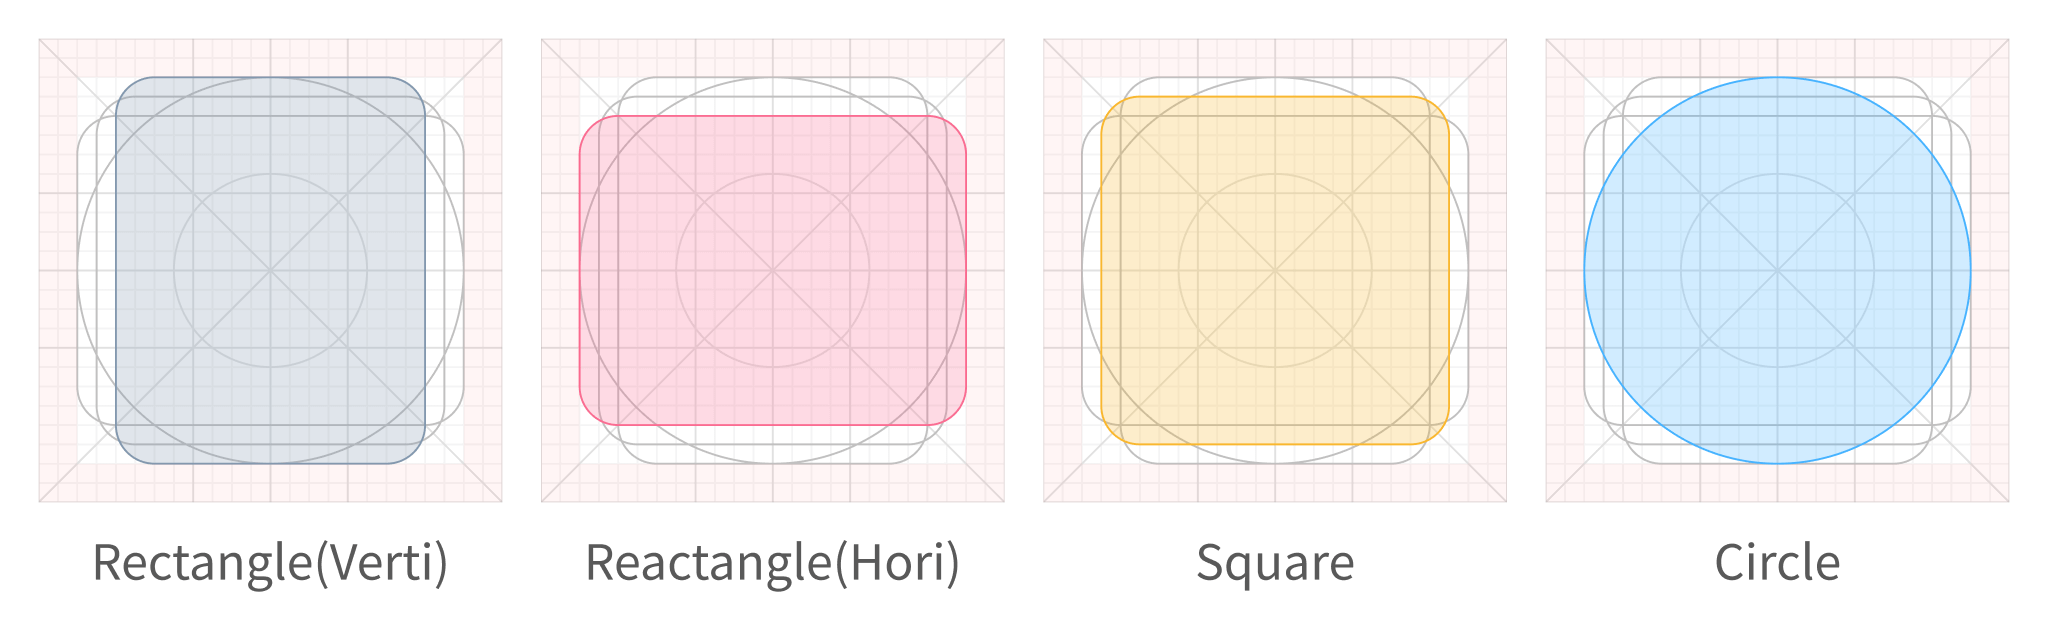
在设计资源满天飞的现在,你完全可以在 [iconfont](https://www.iconfont.cn/) 上找到样式符合需求的图标。然后根据产品的风格,进行重绘即可,真正需要设计师来完全创造的就很少了。
我也尝试应用 Keyline 绘制了几个基本的图标:主页、卡片、锁、文件,这也是 Keyline 上的四种基本形状。
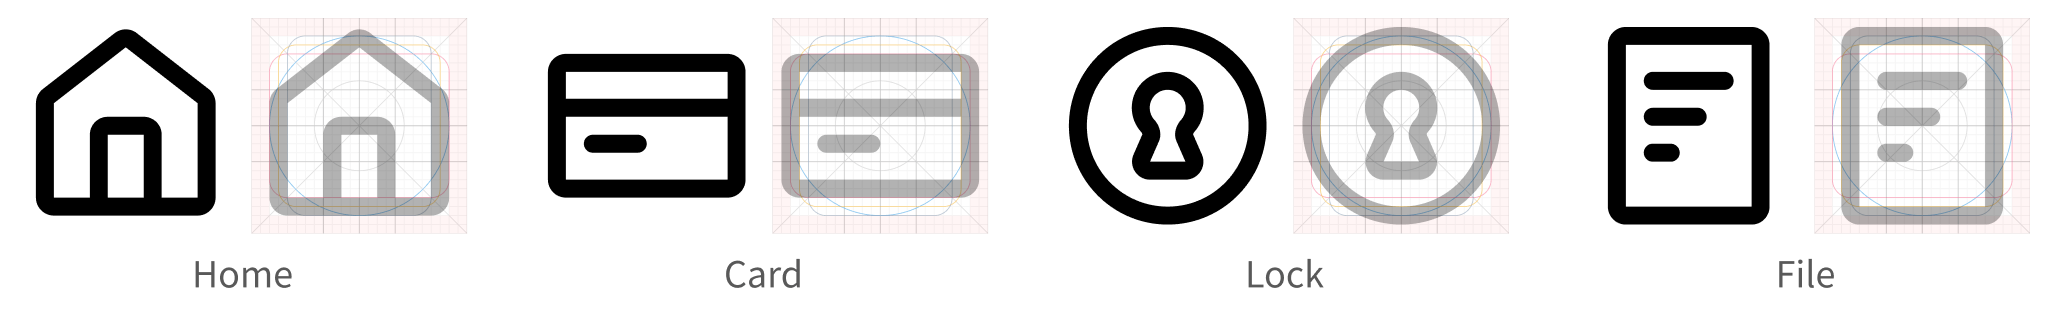
在自己上手实操过程中,我发现了几个图标设计小 Tips:
- 尽量应用「基础形状」布尔运算来构成图标。
- Keyline 提供的是数值上的平衡,但数值相等不等于视觉上的平衡(例如:播放图标)。
- 在选择描边对齐(Stroke Alignment)方式时,图标设计中大多应用中心对齐(Center)或内侧对齐(Inside)。中心对齐的图标在相同情况下看起来会更大些。
- 在 Figma 中,使用 `Shift + Backspace` 删除点和利用钢笔工具的中心点功能可以大幅提高图标设计的效率。
- 图标设计完毕后,可应用 Flatten 来将图标线条整合在一起,方便统一处理。不需要将描边变成面,因为这不利于后期调整线段粗细。
## 图标应用
在图标设计完成后,接下来的步骤是考虑如何将这些图标有效地展示给观众。正如俗语所说,「丑媳妇最终也要见公婆」,这意味着无论设计结果如何,都需要有一个展示和反馈的过程。这不仅是为了展示成果,也是为了获取反馈、改进和优化设计。
### 图片方式
最传统的展示方式自然是图片。设计师将图标按照默认、悬停、按下、激活、禁用等状态分别切出 @1x @2x 的图标,打个压缩包,发给前端。亦或者设计师切图后上传蓝湖,前端自行在「蓝湖」下载自己所需要的图标。
如果前端需要图片格式的图标时,我一般会通过 [TinyPNG](https://tinypng.com/) 压缩一下图标,在保证图标清晰度的情况下使得图标占用尽量小。我最常用工具是 [TinyPNG4Mac](https://github.com/kyleduo/TinyPNG4Mac),比较方便。部分前端脚手架也自带了图片压缩功能,占用小于某个值的图片还会被转为 Base64 编码来存放。

往更早的技术回溯,我们会遇到「雪碧图」,这是一种将多个图标整合到一张带有透明背景的图片中的做法。设计师把所有图标放在一张图上,然后前端通过每个图标的位置和尺寸来在网页上显示它们。这种方法的优点是减少了网页请求的次数。实际上,现在一些网站在制作动态图像时,也常采用类似「雪碧图」的方法,通过连续的静态帧来创建动画效果。
JPG / PNG 格式的图片属于最保险的展示方式,所有浏览器都支持,虽然是一种位图格式,放大后不够清晰,但图片格式基本能够解决网站的大部分需求了,解决方案也足够成熟了。
现有的 CDN 服务商和或一些框架,如 Next.js,能够智能识别浏览器是否支持 WEBP 或 AVIF 格式。这两种图片格式可以提供更高压缩率但是更高的清晰度。
### 字体方式
前面我们也说过了,图标需要设计师按照各种状态分别切图,然后再提供给开发。如果官网整体色彩调整,全部图标都需要重新切图的话,这或许就是一场浩劫。
也或许因为其他原因一起,图标字体的方案出现了。国内最常用的字体图标平台也就是 iconfont。这需要设计师将图标轮廓化,然后上传至 iconfont 上。前端便可以根据图标名称引用图标,也可以方便的调整图标的色彩、大小。
字体图标直到我写这篇文章的时候,应用的也还是挺广泛的,调用方便、占用较少。但主要有以下几个缺点影响着字体图标的使用:
- 图标需要设计师一个个处理。部分图标轮廓化之后还不够,还需要通过 Figma [Fill Rule Editor](https://www.figma.com/community/plugin/771155994770327940/fill-rule-editor) 插件,将图标填充模式调整成「Non-zero rule」才能够正常展示在 iconfont 中。 具体方案可[参照](https://zhuanlan.zhihu.com/p/137298478)
- 如果通过 Fill Rule Editor 调整填充样式时,发生了图标消失事件,可以尝试将图标原封不动的复制到 illustrator / Sketch ,然后复制回来即可解决该问题。(误
- 字体图标对于多色图标的支持程度不够,自定义程度不够高。
- 字体图标还存在无法正常渲染的情况,还需要特殊处理(我曾天真以为是我浏览器的问题)。
字体样式图标我只能从设计师的角度来评价,因为我没有在开发时应用过该方式。推荐文章 [Icon Fonts vs SVG Icons: What Works Best for You?](https://getdevdone.com/blog/icon-fonts-vs-svg-icons.html),里面比较详细的对比了字体与 SVG 优缺点。
### SVG 方式
SVG 图标不仅继承了字体图标的主要优势,还解决了字体图标的一些局限性,其主要优点包括:
- 支持每个图标拥有多种颜色,包括渐变。
- 支持更加复杂的图形和形状,其不限于字体的基本形状。
- 支持直接嵌入 HTML 代码中,方便编辑、控制图标。
- 支持 CSS 和 JavaScript 动画
iconfont 也不仅仅只支持字体图标的方式,官方几年前也已经支持通过 symbol 方式来引用 SVG 图标。
我们可以通过一个例子来简单了解 SVG。以下是一个在 Figma 中导出的 SVG 格式的「主页」图标,其代码如下:
```html
```
这个 SVG 包含几个关键属性:
- **path:** path 元素定义了图形的轮廓,通过一系列命令和参数描述路径上的点,形成图形。在这个例子中,这些命令和参数共同构成了一个房子的形状。
- **fill:** fill 属性用于设置图形的内部颜色。它可以是16进制的颜色代码(例如 #FF0000),也可以是常见的颜色名称(例如 `black` )。none 表示没有填充,而 currentColor 使用元素或其父元素的 color 属性值。
- **stroke:** stroke 属性用于定义图形轮廓的颜色,使用方式与 fill 相似。
- **stroke-width:** stroke-width 属性指定描边的宽度。
如果 SVG 包含多个路径,会有多个 path 元素。每个 path 可以有独立的 fill 和 stroke 属性,控制各自的填充和描边样式。如果某个图形部分不需要描边,可以将其 stroke 属性设置为 none 。
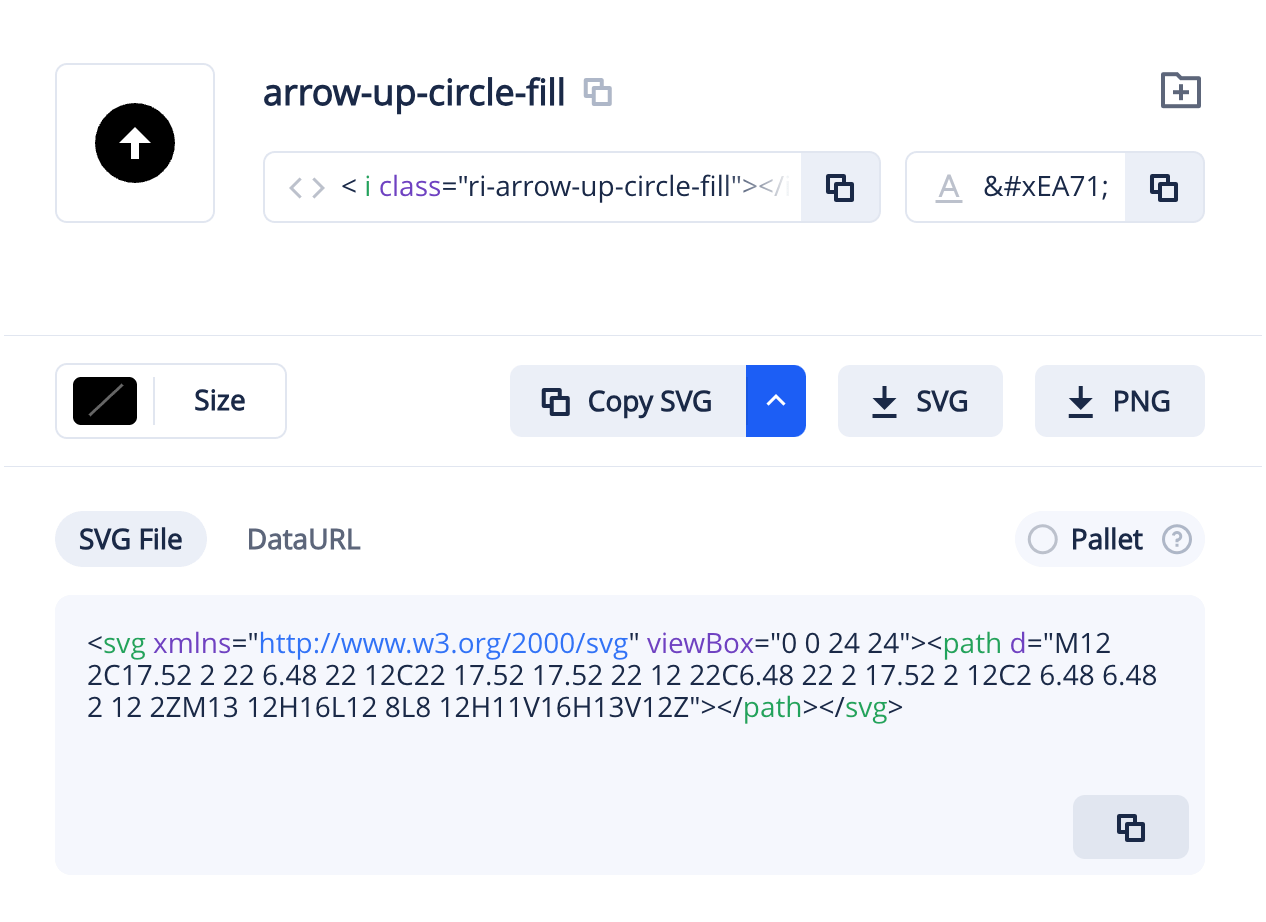
如上图所示,我们看到的是一个图标的预览和对应的代码。仔细观察,你会注意到代码中并未指定图标的宽度、高度、填充色和描边色。
这种做法旨在提供尽可能简洁的 SVG 图标代码,仅包含图标路径等核心信息。这样设计的目的是允许前端开发者更灵活地控制图标的颜色和尺寸。例如,如果 SVG 图标代码中默认包含了 `fill` 属性,前端开发者在应用这些图标时可能会发现无法改变其颜色。为解决这一问题,一种方法是移除 `fill` 属性,或将 `fill` 设为 `currentColor` ,然后通过CSS来定义颜色。另一种方法是直接在 `fill` 属性中指定所需颜色。
不建议使用诸如 filter 这样的 Hack 方法来调整颜色,因为这种方法可能既复杂又不精确。
同样,SVG图标支持压缩,可以使用工具如 [SVGO](https://github.com/svg/svgo) 清理 SVG 代码中的冗余部分。
对于前端调用SVG的实践,可以参考下面的示例,其中使用了 Tailwindcss 和 Lucide Icons :
**直接调用示例**
这段代码示例展示了如何使用简单的类控制图标的尺寸、颜色以及暗黑模式下的显示效果。操作非常直观方便:
```tsx
```
**软件包应用示例**
以下示例展示了如何通过软件包来应用图标,这种方式同样简单,只需引入所需图标并设置样式:
```tsx
import { Home } from 'lucide-react';
const App = () => {
return (
);
};
export default App;
```
要将设计图标交付给开发团队,你可以选用 iconfont 或使用 [figma-icon-automation](https://github.com/leadream/figma-icon-automation) 插件打包图标为 npm 库,便于开发团队通过安装包调用。此方法配置一次即可,效率高。
SVG 图标应用方式虽然涉及到代码,但是该部分介绍也还是为设计师准备的。目的只想告诉大家,SVG 不存在不好调整色彩的问题,也不存在不好调用的问题。积极推动开发跟进吧~
## 结束语
这个微小的图标背后隐藏着丰富而复杂的内容,而本文仅仅是对这一广阔主题的初步探索。作为一个初学者,我在文章中的错误在所难免,我诚挚地欢迎读者提出宝贵的意见和指正。
## 参考内容
- [Material Design 3](https://m3.material.io/)
- [Icon Fonts vs SVG Icons: What Works Best for You?](https://getdevdone.com/blog/icon-fonts-vs-svg-icons.html)
- [Design Icons from Scratch](https://blog.yarsalabs.com/guide-to-design-icons/)
- [Intro to The 8-Point Grid System](https://medium.com/built-to-adapt/intro-to-the-8-point-grid-system-d2573cde8632#.5h95d066j)
- [Apple - Human Interface Guidelines](https://developer.apple.com/design/human-interface-guidelines)
- [Ant Design 5](https://ant.design/index-cn/)
- [Lucide Icons](https://lucide.dev/)
- [Remix Icons](https://remixicon.com/)
---
---
title: "Next.js 调用 Notion API 记录"
description: "使用 Next.js 调用 Notion API 构建博客时的开发记录,包含数据获取、图片优化和样式渲染等踩坑经验"
canonical_url: https://ro.yikzero.com/blog/brogbuild-1/
locale: zh-CN
date: 2023-10-04
---
# Next.js 调用 Notion API 记录
## 踩坑集合
坑一方面来源于 Next.js,另一方面来源于 Notion API。当然,我自己才是最大的坑。
1. Next.js 服务端渲染
2. Notion API 数据过滤
3. Notion Block 数据渲染
4. Notion 临时图片过期
5. Next.js Image 组件使用
6. Notion 文章页面样式渲染
以上基本就是我踩的所有坑了,在介绍踩坑经验之前,还是简单的说一下项目的初衷。
## 初衷
最初是因为,我学了前端,然后就想了解后端,最初是做了一个基于 edge-tts 的语音转文字全栈项目 Rotts(前端 React + 后端 Flask),但这个项目很简单,后端基本就是请求 API,获取声音列表,然后将声音、音高、文字等信息传递给 edge-tts,等待声音返回,然后播放/下载就行了。后台感觉还没有怎么体验就感觉结束了。
所以,就想着找另外一个项目,继续学习下后端。首先想到的是 Node.js,调研过程中,看到了很多人推荐的 Next.js,也是基于 Node.js。那就一拍即合,我也想简单造一个轮子,做一个将 Notion 作为 CMS 的博客系统。视觉上一切从简,减少负担,着重于内容的渲染。
本来想着有 ChatGPT,不会的问问他就行了。结果 Next.js App 太新了,他的资料库里都没有,每次问他相关内容都回答的不够准确。
## 项目信息
- 名称: **Brog**
- 介绍: Next.js 构建,CMS 为 Notion 的简约博客系统
- 技术栈:React + Next.js + Typescript + TailwindCSS
- Github:[https://github.com/yikZero/Brog](https://github.com/yikZero/Brog)
## Next.js 的坑
### 重复请求
其实我在刚开始的获取数据的时候,就有疑问,我这边 fetch 一下,那边 fetch 一下。都是相同的数据,会不会多次请求,会很浪费呀?
为了这个,我也一直在将函数功能与请求分离开,传递好几个 props 就行……. 但其实至少在 React 里不用在意这个。
> Passing data between a parent layout and its children is not possible. However, you can fetch the same data in a route more than once, and React will automatically dedupe the requests without affecting performance.
如果你 fetch 的链接和参数不变,那么你多次的请求,React 也会帮你合并成一次进行请求。所以也不用一直在组件之间转发 props,你就请求多次相同数据吧,没什么问题。React 会自行合并请求,不会多次重复请求,影响网络。
### 服务端组件
怎么样算是服务端组件呢,放在 `app/` 目录下的应该都属于服务端组件。我不知道是不是服务端组件的时候,我把我用到的 components、lib 文件目录,全部扔到 `app/` …… 就为了服务端组件。
想让其变成客户端组件,那就加一个 `use client` 在顶部,那就会被识别为客户端组件。Next.js 官方推荐能服务端就服务端。
### next/image 应用
Next.js 官方因为 [LCP performance](https://almanac.httparchive.org/en/2022/performance#lcp-image-optimization) 的原因,优化了 img 元素的应用,推荐使用官方 Image。
具体使用方法可参照 [Image Optimization](https://nextjs.org/docs/app/building-your-application/optimizing/images)
我以为会很简单喽,替换个名字就好,但是其要求我提供明确的高度和宽度。我动态获取的图片,我咋知道图片的高度和宽度呢。所以也就使用了奇技淫巧…….也是 [stackoverflow](https://stackoverflow.com/questions/65169431/how-to-set-the-next-image-component-to-100-height) 上的方案。
```html
```
## Notion-Client 的坑
### 数据获取
Notion 官方有 [@notionhq/client](https://www.npmjs.com/package/@notionhq/client),同时 react-notion-x 也有一个 [notion-client](https://www.npmjs.com/package/notion-client)。我是先了解到的 notion-client ,所以样式写完之后,尝试集成的是第三方实现的。
怎么说呢,notion-client 也挺好,提供一个公开的 `NOTION_PAGE_ID` 环境变量,即可获取到数据。但是获取到是全量数据,没办法跟官方的 API 一样根据字段名进行筛选的功能,所以整理数据会麻烦很多。这对于我这新手还是麻烦太多了…….毕竟,在 Notion 获取的数据是一层一层套娃的,每一个块都有其 ID,搞得我晕头转向。
最后也还是参考 [notion-blog-nextjs](https://github.com/samuelkraft/notion-blog-nextjs) 应用的官方 API,来获取到相对应的数据。
### 图片过期
Notion 官方提供的数据中的图片链接是 Amazon 临时链接,一个小时就会过期。然后就会导致图片挂了。
**Vercel Cron:** 很多人也会选择使用 Vercel cron 功能,每个小时重新构建渲染一下。但我觉得这也太浪费资源、太不环保了 (:
**临时地址转化为永久地址:** 方案的话可以参考 [fix: solve linked img crash #524](https://github.com/tangly1024/NotionNext/pull/524/files)
**PicGo 上传至又拍云:** 因为我迁移过数据,Markdown 图片如果都是相对地址的话,简直是个灾难。所以,我现在就会选择通过 PicGo 上传至又拍云中,返回一个我的 CDN 地址。如果要迁移的话,那至少图片不会丢。
---
---
title: "HomeLab 家庭环境配置"
description: "记录光猫、R4S 软路由和 Linksys 硬路由的配置"
canonical_url: https://ro.yikzero.com/blog/homelab-config/
locale: zh-CN
date: 2023-09-12
---
# HomeLab 家庭环境配置
## 背景与目的
家庭网络配置通常涉及光猫作为 ISP 连接的入口,R4S 软路由(基于 OpenWrt 的 NanoPi R4S)和 Linksys 硬路由用于管理内部网络。本文的目标是通过桥接模式优化网络性能,减少 NAT 冲突,并利用 R4S 和 Linksys 实现高效的网络管理和无线覆盖。
## 拓扑图
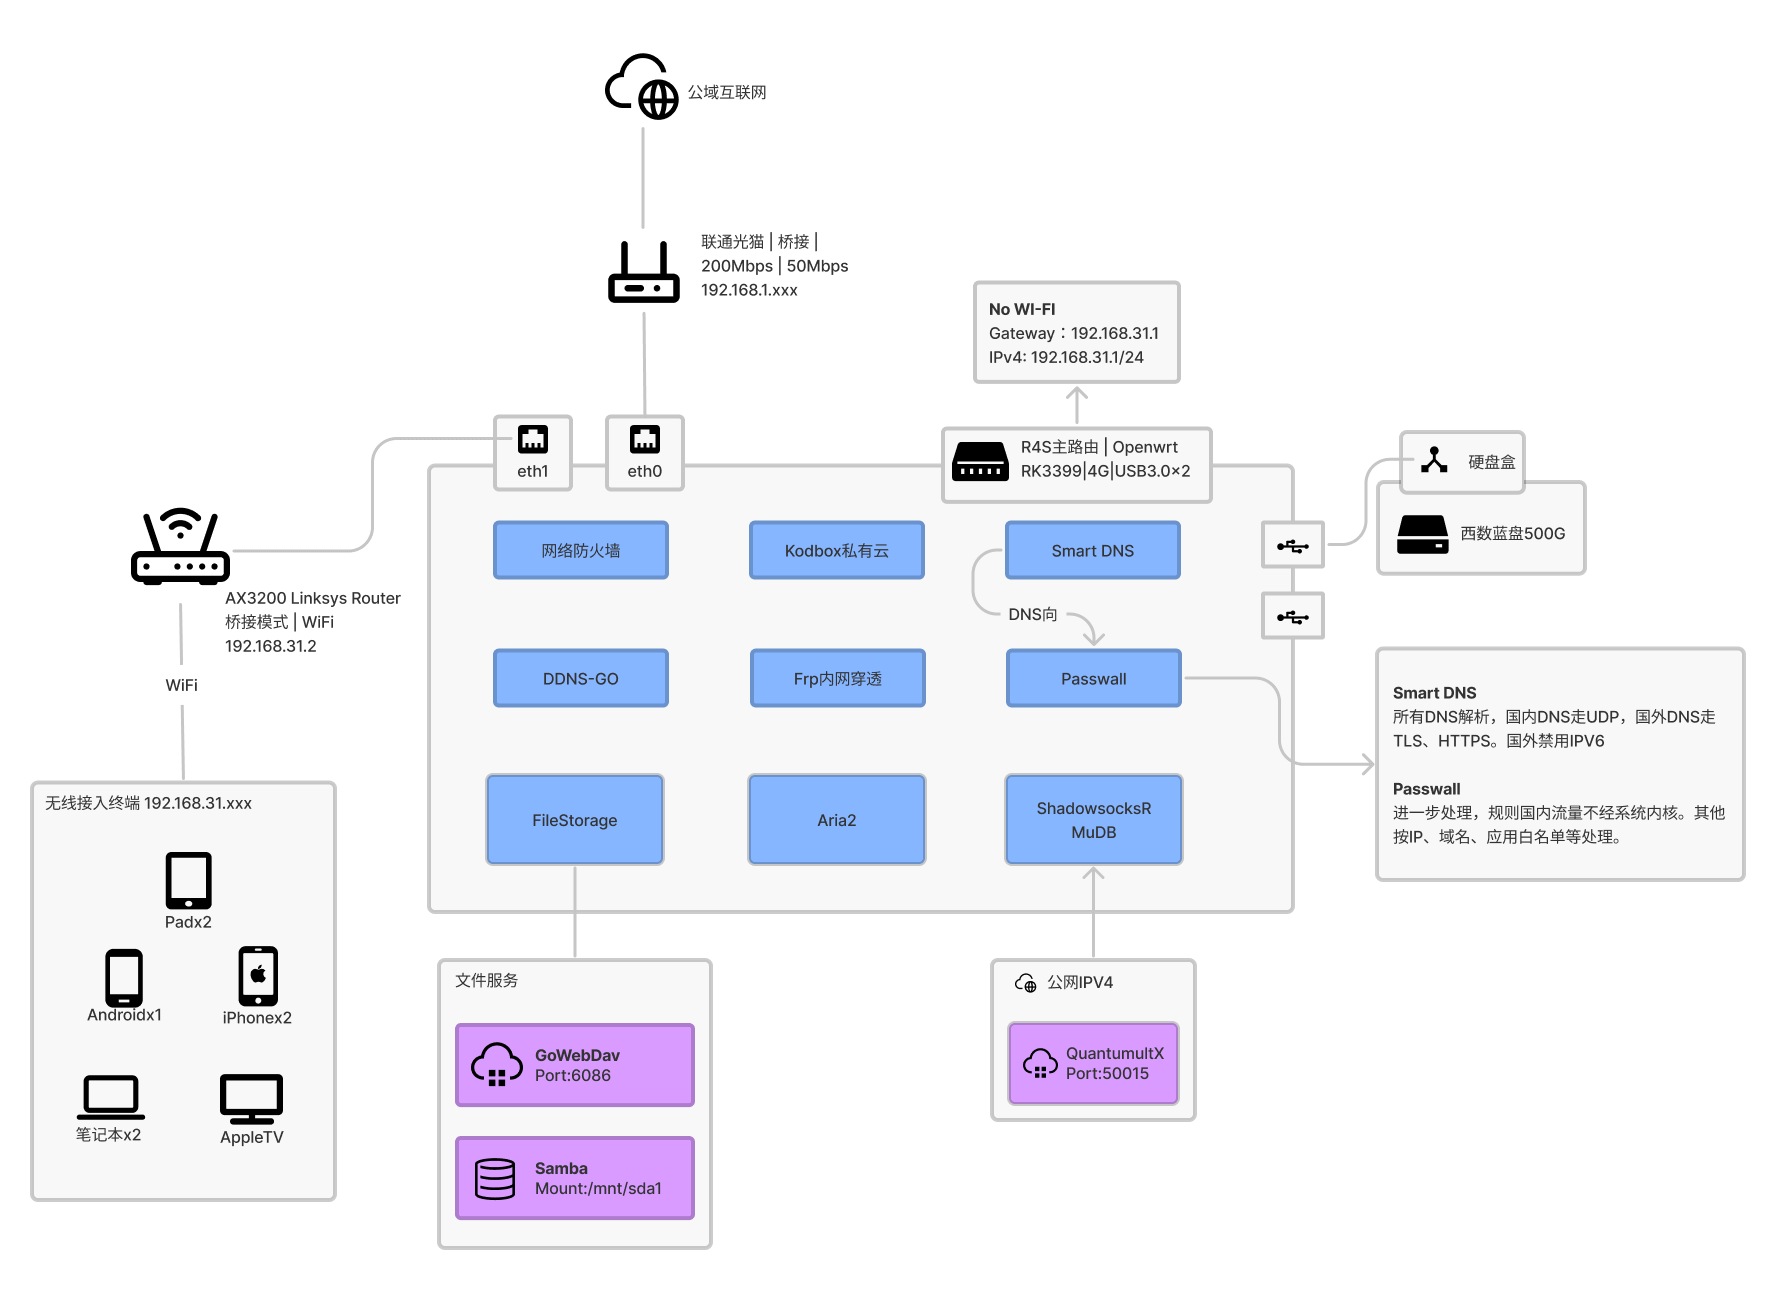
光猫桥接模式连接 R4S WAN 口,R4S 作为主路由处理 PPPoE,Linksys 通过 WAN 口连接 R4S LAN 口,设置为桥接模式作为无线接入点。
## 光猫桥接配置
### 桥接理由
- 防止 NAT 转发重复,避免双 NAT 问题影响某些应用。
- 减轻光猫网络压力,光猫仅负责光电信号转换,不进行路由。
- 光猫功能受限,桥接后可利用 R4S 或 Linksys 提供更强大的路由功能。
- 光猫 WiFi 信号弱,桥接后可使用 Linksys 提供更好的无线覆盖。
### 具体配置步骤
#### 杭州联通光猫
- **登录信息**:
- 地址:`http://192.168.1.1/cu.html`
- 账号:`CUAdmin`
- 密码:`CUAdmin`
- **PPPoE 设置**:
- 账号:通常以 0571(杭州区号)开头,需查看后台获取。
- 密码:账号后六位。
- **桥接模式设置**:通过登录界面找到 WAN 设置,将模式调整为桥接,保存并重启。
#### 杭州移动光猫
- **登录信息**:
- 地址:`http://192.168.1.1/`
- 账号:`CMCCAdmin`
- 密码:`aDm8H%MdA`
- **PPPoE设置**:
- 账号:以`hz`开头,后面加区域首字母(如滨江区为`hzbj`),再加a-z字母按宽带开通顺序(如第一条为`hzbja`)。
- 密码:尝试`000000`、`888888`、`123456`、账号后六位或身份证后六/八位。
- **桥接模式设置**:登录后调整 WAN 为桥接模式,保存并重启。
### 桥接模式使用 PPPOE
桥接后,R4S 或 Linksys 需通过 PPPoE 账号密码进行网络拨号,确保互联网连接正常。
---
## Linksys 桥接模式
### 初期配置
不管你后续想改成「桥接模式」还是「自动配置 - DHCP」,你初期都需要先进行初始化设置。按照「配置向导」正常设置路由器密码,配置 WiFi 密码。不额外配置且网线没问题,能够正常上网了。
### 高级设置
#### 桥接模式
1. **连接**:将 R4S LAN 口连接到 Linksys WAN 口(Internet 端口)。
2. **登录界面**:访问 Linksys web 界面(默认192.168.1.1),跳过初始设置提示。
3. **设置桥接模式**:
- 进入`Configuration > Connectivity > WAN Setup`。
- 选择`Bridge Mode`,将路由器作为无线接入点使用。
- 选择“自动获取 IP 地址”或手动指定IP(如192.168.31.2,默认网关为192.168.31.1)。
- 保存并重启路由器。
设置完毕,点击「保存」重启路由器
#### 额外优化
- **无线网络 - 高级设置 - 漫游助手**:选择关闭,可提升稳定性。
- **无线网络 - 高级设置 - 地区**:选择澳大利亚,可能增强信号强度,但需注意合规性,可能不适用于所有地区。
- **如使用 Homeassistant**:建议关闭 WiFi 双频合并模式,以避免兼容性问题。
## 总结
本文提供了光猫桥接模式、R4S PPPOE 配置和 Linksys 桥接模式的详细步骤,确保家庭网络高效运行。
---
---
title: "R4S 安装 Plex 服务端记录"
description: "在 R4S 软路由上安装 Plex 媒体服务器的完整记录,解决架构兼容、远程访问和端口转发等问题"
canonical_url: https://ro.yikzero.com/blog/plex-server-1/
locale: zh-CN
date: 2023-03-18
---
# R4S 安装 Plex 服务端记录
## 配置环境
- 型号:FriendlyElec NanoPi R4S
- 固件版本:OpenWrt R22.3.13 (2022-06-22)
- 架构:ARMv8 Processor x 6
- 环境:Google Direct
## 前期准备
1. 自行配备访问谷歌的网络
1. 安装好带 docker 的 openwrt 系统
1. 内存卡给 docker 扩容
## 踩坑记录
### 架构问题
现有大部分教导 docker 搭建 plex 的都是基于 X86 架构的,如果你根据 [plexinc/pms-docker](https://hub.docker.com/r/plexinc/pms-docker/) 的 docker 镜像搭建的话,会在 docker 容器日志中报错:`stderr: exec /init: exec format error`
这就是因为你安装的也是跟你系统架构不相同的 docker 容器。
所以寻找到 [linuxserver/plex](https://hub.docker.com/r/linuxserver/plex) 的 ARM 架构的 PLEX 开始安装:
```shell
docker run \
-d \
--name plex \
-p 32400:32400/tcp \
-p 3005:3005/tcp \
-p 8324:8324/tcp \
-p 32469:32469/tcp \
-p 1901:1900/udp \
-p 32410:32410/udp \
-p 32412:32412/udp \
-p 32413:32413/udp \
-p 32414:32414/udp \
-e TZ=Asia/Shanghai \
-e PLEX_CLAIM=claim-xfczZtmEH5QPvZQc1HsF \
-e ADVERTISE_IP="http://192.168.31.1:32400/" \
-h Zero-R4s \
-v /myplex/plex/database:/config \
-v /myplex/transcode/temp:/transcode \
-v /mnt/sda/Media:/data \
--restart unless-stopped \
lscr.io/linuxserver/plex:latest
```
具体操作教程在 [linuxserver/plex](https://hub.docker.com/r/linuxserver/plex) 也可以找到,根据自己的情况进行调整即可。
## PLEX 无初始化页面
这句话的意思是,在初次进入 Plex 应用界面时,可能会由于未开启远程访问而出现“找不到服务器”的问题,此时可以使用以下两种方法来解决:
**一、SSH 转发端口**
需要在本地计算机上打开 PowerShell 工具,然后运行上述命令,将远程服务器的 Plex 端口(默认为 32400)转发到本地计算机的端口(例如 8888)。转发端口成功后,可以在本地计算机的浏览器中访问 `localhost:8888/web` 来打开 Plex 应用界面。
**二、直接连接**
如果远程服务器已经允许了远程访问,可以尝试在浏览器中直接访问远程服务器的 IP 地址和 Plex 端口(例如 http://13.124.4.66:32400/web)来打开 Plex 应用界面。
### 解决方法
在 macOS 上,可以使用 iTerm 应用程序来设置 SSH 转发端口,具体步骤如下:
**一、连接远程服务器**
输入以下命令来连接远程服务器,其中 username 是远程服务器上的用户名,remote_server_ip 是远程服务器的 IP 地址:
`ssh -L 8888:localhost:32400 username@remote_server_ip`
这将会在本地计算机的 8888 端口将远程服务器上 Plex 的 32400 端口转发到本地计算机上。
**二、输入远程服务器上的密码并验证**
现在,可以打开本地计算机上的浏览器,然后输入`http://localhost:8888/web` 来访问远程服务器上的 Plex 界面。
### 再次报错
```shell
@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@
@ WARNING: REMOTE HOST IDENTIFICATION HAS CHANGED! @
@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@
IT IS POSSIBLE THAT SOMEONE IS DOING SOMETHING NASTY!
Someone could be eavesdropping on you right now (man-in-the-middle attack)!
It is also possible that a host key has just been changed.
The fingerprint for the ED25519 key sent by the remote host is
SHA256:OC9qmnB9nQtFN/OiPH7jGEoKb/zbX4NghGv/glu5dwQ.
Please contact your system administrator.
Add correct host key in /Users/yikzero/.ssh/known_hosts to get rid of this message.
Offending ED25519 key in /Users/yikzero/.ssh/known_hosts:1
Host key for 192.168.31.1 has changed and you have requested strict checking.
Host key verification failed.
```
这个错误提示表明之前连接的远程服务器的密钥发生了变化,可能是服务器进行了系统更新或者管理员更改了服务器的密钥。为了保护信息安全,SSH 客户端会检查远程服务器的密钥并进行验证,如果密钥发生变化,就会出现这个错误提示。
更新本地计算机的远程服务器密钥数据以解决问题。操作步骤如下:
1. **删除旧密钥:**
执行 `ssh-keygen -R ` 删除本地计算机上的旧密钥数据。
2. **连接远程服务器:**
使用 `ssh username@remote_server_ip` 连接。
- 系统会提示“Are you sure you want to continue connecting (yes/no)?”。输入 yes 并回车。
- 输入远程服务器密码以验证。
- 连接后,重新运行命令以设置 SSH 转发端口。
完成后即可访问 PLEX 服务端。
---
---
title: "Hugo 折腾记录:从 0 到 1"
description: "从零搭建 Hugo 博客的完整过程,涵盖安装配置、页面结构和 CSS 布局技巧"
canonical_url: https://ro.yikzero.com/blog/hugo-build-1/
locale: zh-CN
date: 2022-03-23
---
# Hugo 折腾记录:从 0 到 1
## Hugo 安装
### 官方文档教程
官网针对不同系统都有详尽的安装教程介绍:https://gohugo.io/installation/
### Brew
如果您是 Mac 用户,可以使用`brew`命令来安装。
```bash
brew install hugo
```
**注意:** 这种安装方式可能安装的不是最新版本的 hugo,如果要使用最新版的 hugo,请使用其他方式安装。
## 配置文件格式
作为一个小白,配置文件格式是选 yaml、toml、json 就成为了我第一个疑问。
**TOML**
1. 区分大小写
2. 文件只能包含 UTF-8 编码的 Unicode 字符
3. 对缩进不敏感
**YAML**
1. 文件以' - '开头,标记文档的开始
2. 键值对由冒号分隔
3. 列表以连字符开头
4. 使用具有一个或多个空格的缩进来描述嵌套集合
**JSON**
1. 数据存储在名称/值对中
2. 记录用逗号分隔 没有以下属性的尾随逗号是不允许的
3. 双引号包装属性名称和字符串
4. 单引号是不允许的
### 字符串差异
任何格式都支持 Strings,但 JSON 不支持多行字符串,还不支持注释。
```toml
# TOML
key = "String Value"
multiline = """\
The quick brown \
fox jumps over \
the lazy dog.\
"""
```
```yaml
# YAML
key : String Value
multilinePreservedLinebreaks:
|
L1 - The quick brown
L2 - fox jumps over
L3 - the lazy dog.
multilineReplaceLinebreaksWithWhitespace:
>
This sentence ist just too long to keep it
on the same line.
```
```json
// JSON
{
"key": "String Value"
}
```
由于`JSON`较为麻烦的注释形式,`YAML`严格的缩进形式,我最终选择`TOML`作为配置文件格式,我也可以自由进行缩进,方便我查看。
## 零零散散的知识点
1. 此符号`:=`是 Python 语言中的赋值运算符(主要称为海象运算符),海象操作符压缩了我们的代码以使其更短。
```jsx
var a; //定义
a = 1; //赋值
```
2. `layout/baseof.html` 是所有页面的基础
3. `layout/partials` 文件夹中可以分部分 `header` 、`footer`等
4. 新增页面步骤:
5. 需要在 `content` 中添加一个 `.md` 文件
6. `layouts/_default` 中增加同名页面
7. 菜单激活 `active` 状态代码:
8. 根据官网[说明](https://gohugo.io/templates/menu-templates/#readout)的方式并不能成功添加 `active` 状态,因此寻找了其他方式来判断 `active`
```jsx
{{ range .Site.Menus.main }}
{{- $menu_item_url := (cond (strings.HasSuffix .URL "/") .URL (printf "%s/" .URL) ) | absLangURL }}
{{- $page_url:= $currentPage.Permalink | absLangURL }}
{{ end }}
```
6. css 中 `position` 功能小知识点!
```css
.outer {
position: relative;
}
.inner {
position: absolute;
top: 0px;
left: 0px;
}
```
7. `Shortcode` 可以简短代码,写一些方法。类似 `function` ,具体参照写法:[Hugo-basic](https://www.letswrite.tw/hugo-basic/)
## 参考资料
- [JSON vs. YAML vs. TOML](https://martin-ueding.de/posts/json-vs-yaml-vs-toml/)
- [深入对比 TOML,JSON 和 YAML](https://www.cnblogs.com/sunsky303/p/9208848.html)
---
---
title: "IFTTT 自动化推送通知"
description: "利用 IFTTT 实现学校通知推送到微信、邮箱等"
canonical_url: https://ro.yikzero.com/blog/ifttt-1/
locale: zh-CN
date: 2021-10-14
---
# IFTTT 自动化推送通知
## 前言
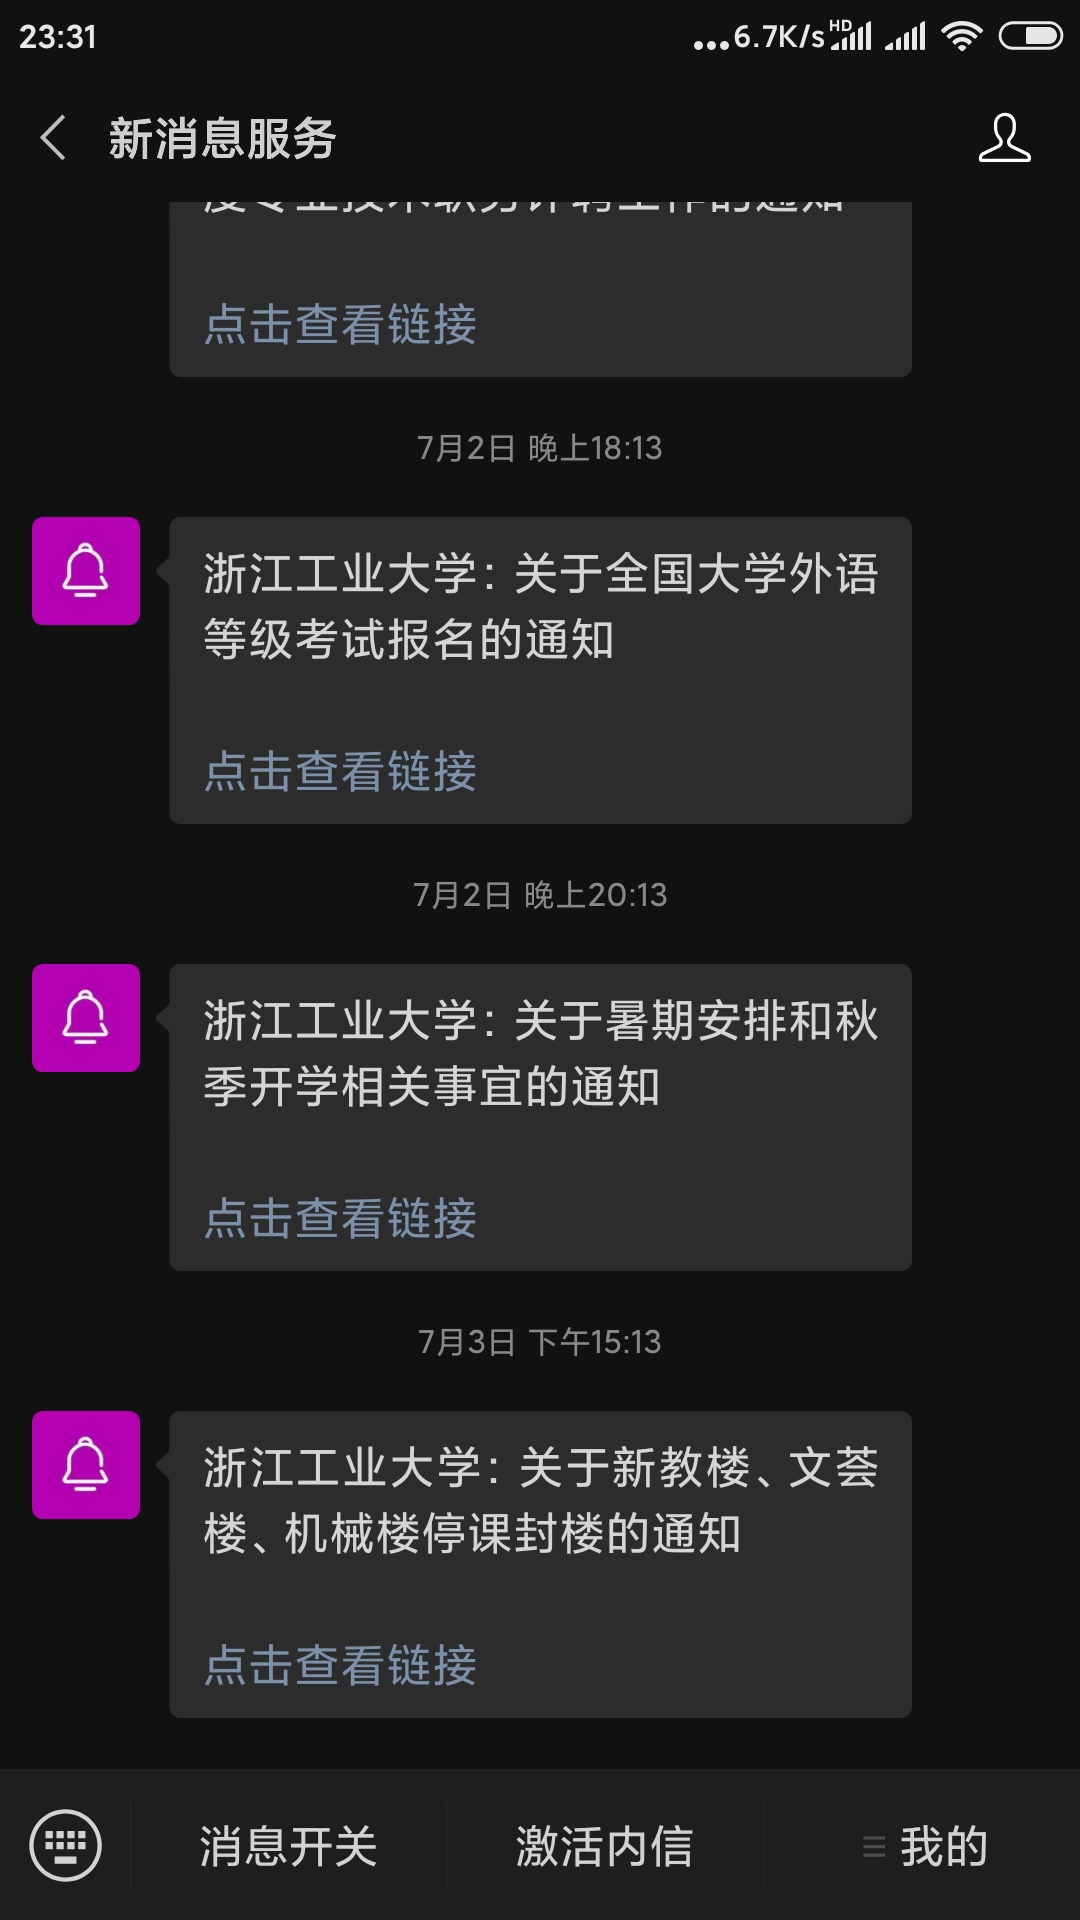
之前有发过一篇文章,是关于学校官网 RSS 订阅的文章。有了 RSS 订阅地址,我们可以将 RSS 推送到我们的「RSS 客户端」来阅读网站更新的文章。写那一篇文章的时候,我只会在[Telegram](https://telegram.org/)上自己的「RssBot」上设置学校官网通知更新推送。没办法实现直接推送到微信,现在写一篇能够实现推送到微信的。
## 获取 RSS 订阅地址
💡 首先,我们要明确,网站不一定提供 RSS 订阅,只有部分网站提供 RSS ,没有 RSS 订阅的网站只能靠自己制作订阅源,或者寻找别人制作好的 RSS 订阅。在这里我推荐一个订阅源分享网站:**[RssHub](https://docs.rsshub.app/)** 作者:**[DIYgod](https://github.com/DIYgod)**
**我以我们学校的订阅来演示:**
```html
1. 在RssHub中中找到我们学校的订阅地址: #路径:路由-大学通知-浙江工业大学
https://docs.rsshub.app/routes/zjut
2.根据需要修改参数,这里我们需要公告栏(板块ID:1)的通知更新,因此我们的订阅链接为:
https://rsshub.app/zjut/1
#如果需要每周会议的RSS订阅地址,那么将1改成2,即:https://rsshub.app/zjut/2
```
第一步完成了,我们得到的 RSS 订阅源地址是:https://rsshub.app/zjut/1
## 学校通知更新推送邮箱
- 打开 IFTTT 网站,并注册账号。**(可用谷歌账号一键登录)**
- 单击右上角 Create ,进行项目的创建
> IFTTT 是“if this then that”的缩写,简单来说的意思就是如果这样,那么那样。如果完成了这个操作,那么他会自动完成那个操作。例如:茶杯放在饮水机下,饮水机检测到有茶杯,这就是 this。水自己会流下来,填满茶杯。这是 that。如果检测到有茶杯,饮水机就会放水。
- 我们今天要实现 **如果检测到工大官网更新了通知,那么就以 邮件 的形式发送给我们这个新的通知标题及内容。**
- 单击 this,找到 RSS Feed
- 选择 New feed item ,在 Feed URL 中填入:**https://rsshub.app/zjut/1**,点击 Create trigger 。完成 this 的操作
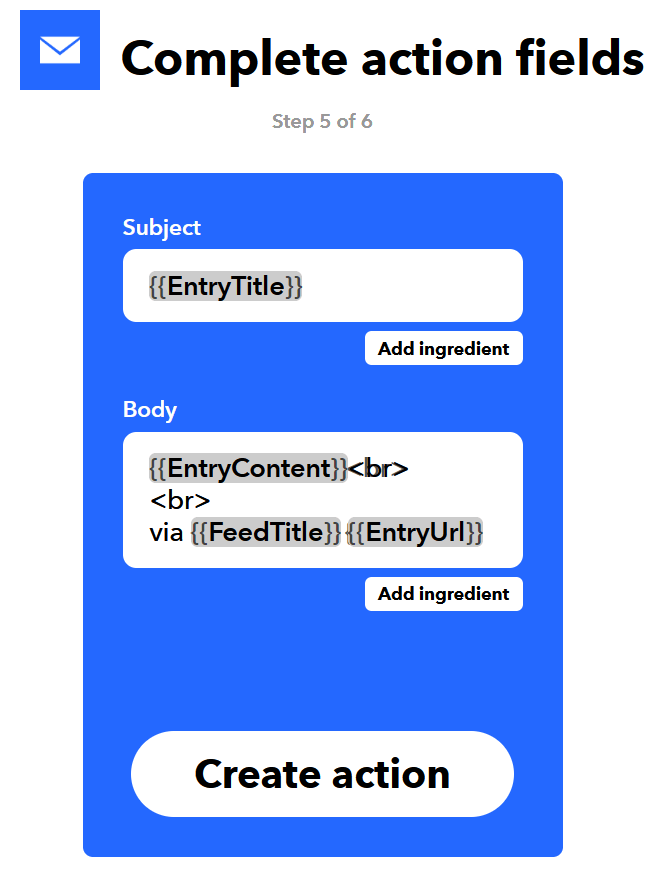
- 同理,在 that 中搜索 email ,先根据提示绑定自己的邮箱,以后官网通知都会发到这个邮箱。
- 这里不用修改,直接 Create action ,然后 Finish
💡 这就实现了官网通知更新推送到你的邮箱,由于网站原因,可能存在十几分钟的延迟,请多理解。
---
## 推送至微信
推送至微信难度稍微高一些,如果想自己配置的,可以继续看下去。如果不想自己配置,可以扫描下方二维码关注公众号就能够收到学校官网更新通知,以后会增加学院网站通知。
推送 RSS 更新到微信用到了[WxPusher](http://wxpusher.zjiecode.com/docs/#/)和[IFTTT](https://ifttt.com/)。配合 Webhook 实现的功能。
> WxPusher (微信推送服务)是一个使用微信公众号作为通道的,实时信息推送平台,你可以通过调用 API 的方式,把信息推送到微信上,无需安装额外的软件,即可做到信息实时通知。 你可以使用 WxPusher 来做服务器报警通知、抢课通知、抢票通知,信息更新提示等。
**1.** 点击地址,微信扫描关注并登录[WxPusher 后台](http://wxpusher.zjiecode.com/admin)
**2.** 首先创建一个应用,记得保存 APP_TOKEN
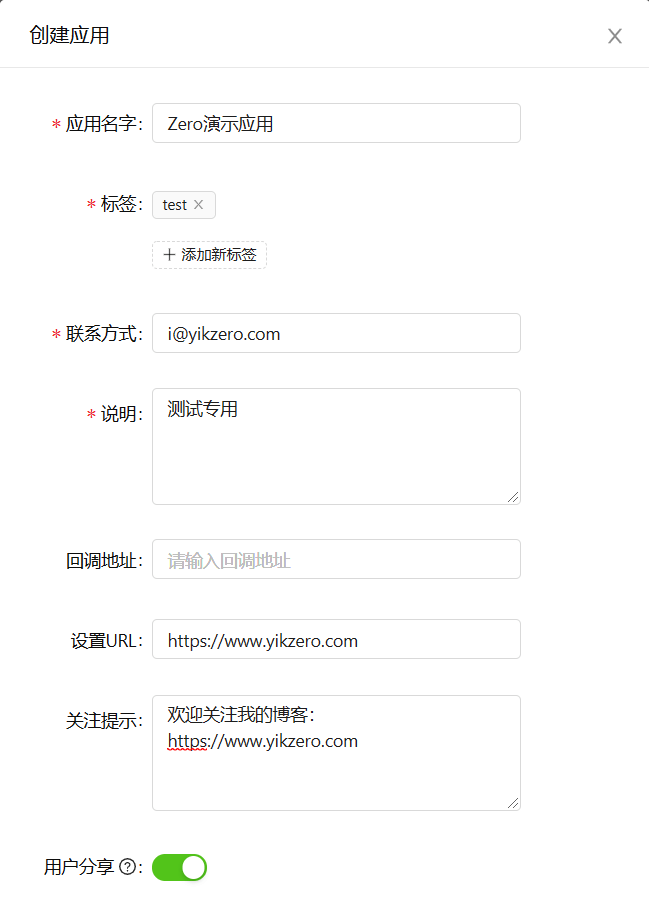
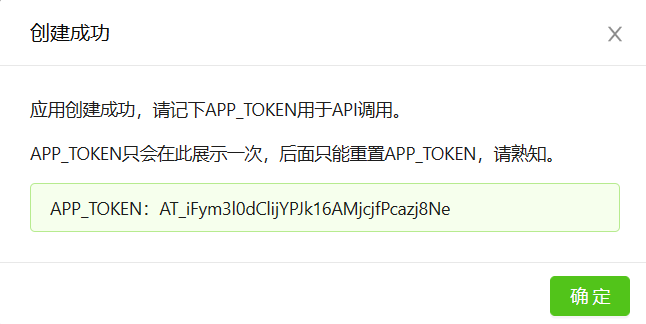
```html
APP_TOKEN:AT_iFym3l0dClijYPJk16AMjcjfPcazj8Ne
#每个人获取到的APP_TOKEN都不一样,请勿复制我的
```
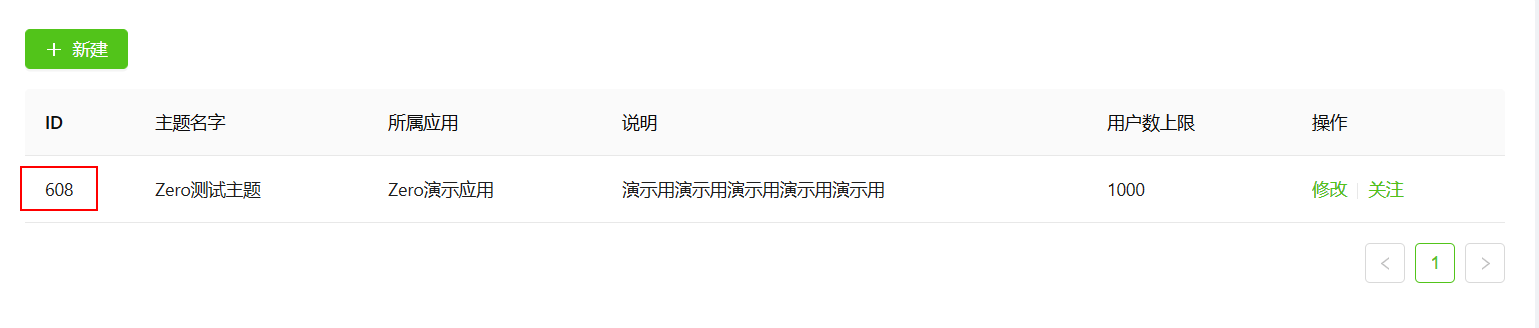
**3.** 创建一个主题
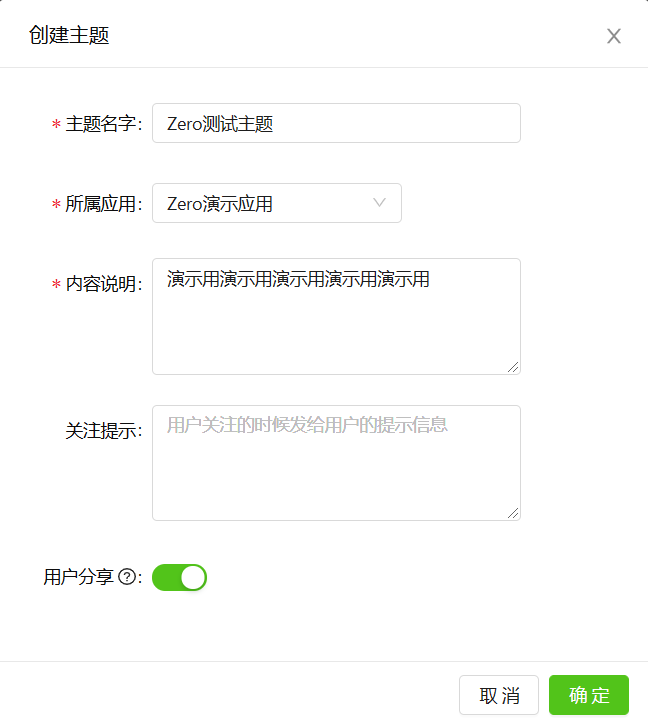
记住刚刚创建的主题 ID
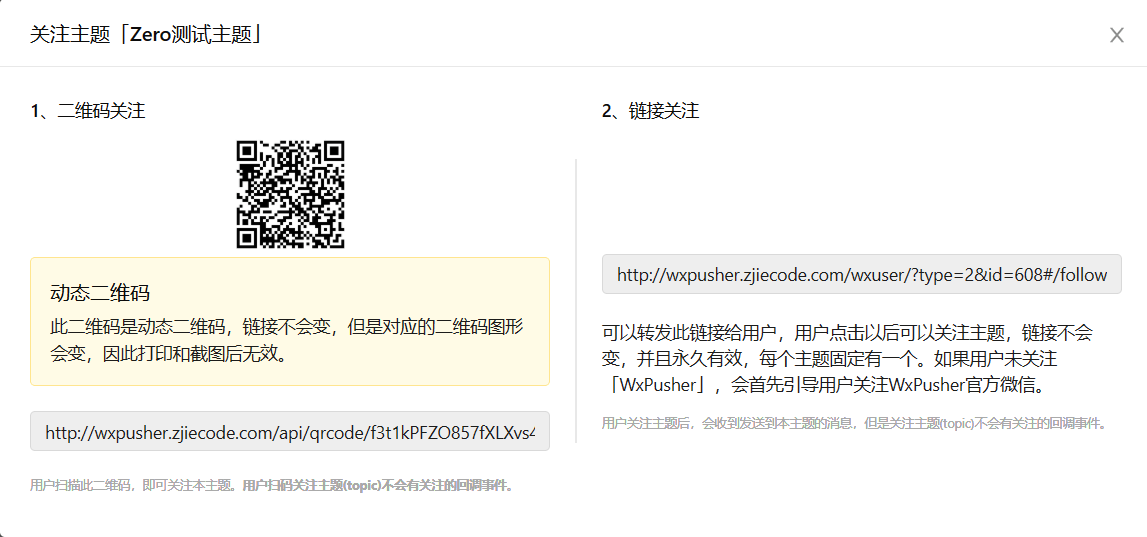
**4.** 点击关注,出现二维码,微信扫描二维码关注主题
**5.** 通过 GET 接口测试功能能否正常使用
- `GET`接口是对`POST`接口的阉割,主要是为了某些情况下调用方便,只支持对文字(`contentType=1`)的发送,举例:
```html
http://wxpusher.zjiecode.com/api/send/message/?appToken=AT_iFym3l0dClijYPJk16AMjcjfPcazj8Ne&content=Zero测试&topicId=608&url=https://example.com
请求参数:appToken、uid、topicId、content、url ,其中 content 和 url 请进行
urlEncode 编码。
```
```html
appToken:AT_iFym3l0dClijYPJk16AMjcjfPcazj8Ne topicId:608 #即主题ID
```
按照你的`appToken`与`topicId`修改上方地址。`Content=`后填写推送内容,`url`如果不需要可以选择删除`&url=https://example.com`
修改完毕后,将地址粘贴到浏览器地址栏

如果失败也是有提示哪里出错了,按照提示修改一下即可这时,不出意外的话,你的微信能收到你刚刚发送的信息。
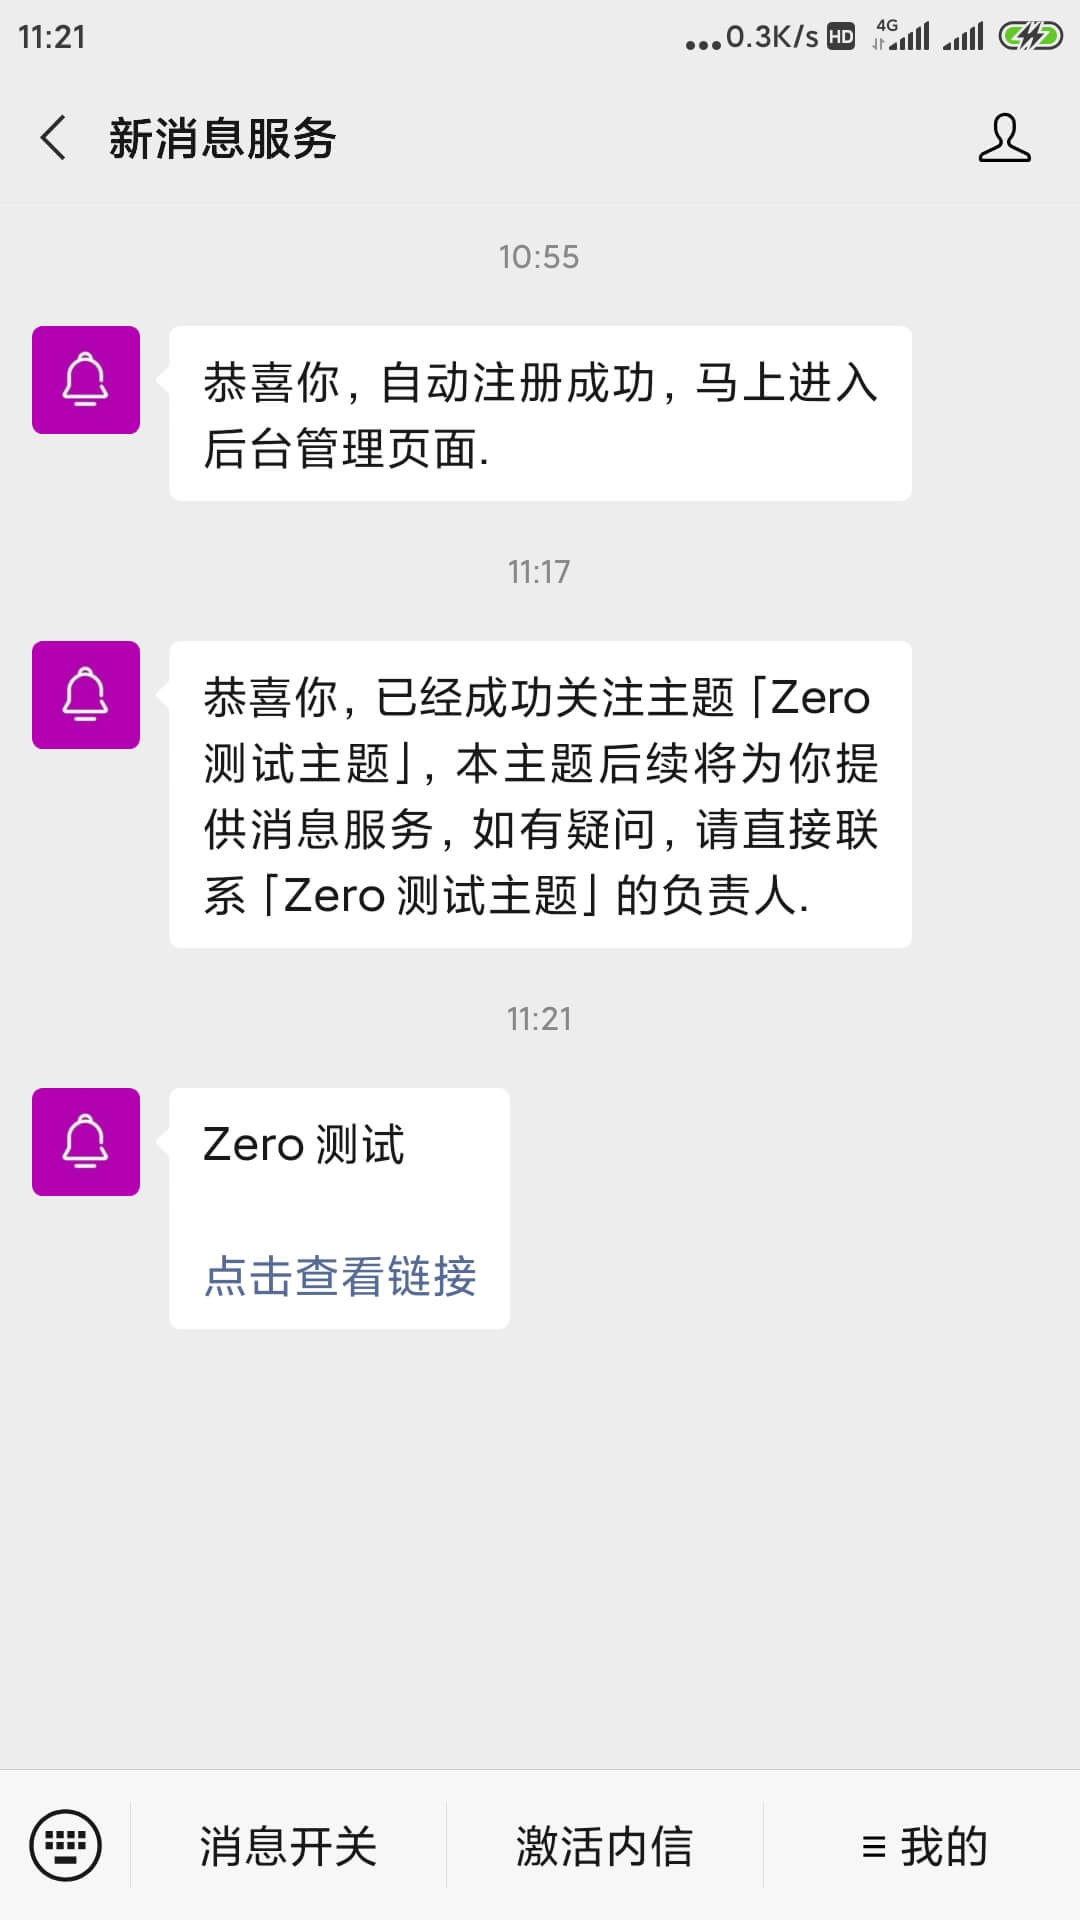
到这里,`WxPusher`部分配置完毕
---
**6.** 创建 IFTTT 新项目, this 部分仍然选择 RSS,具体请查看 IFTTT 推送到邮件部分
that 部分选择 Webhooks 可按图进行配置。
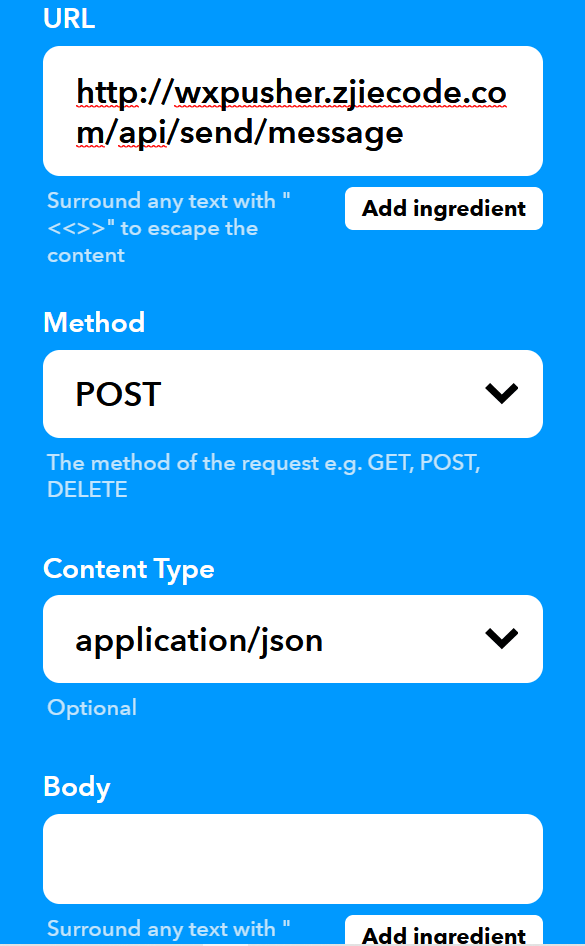
```html
http://wxpusher.zjiecode.com/api/send/message #URL POST #Method application/json
#Content Type
```
Body 部分按照自己的实际情况与参数自行修改,完整参数请点击查看:[POST 完整使用方法](http://wxpusher.zjiecode.com/docs/#/?id=http%e8%b0%83%e7%94%a8#/?id=http%e8%b0%83%e7%94%a8#/?id=http%e8%b0%83%e7%94%a8)
我是这样配置的:
```json
{
"appToken": "AT_iFym3l0dClijYPJk16AMjcjfPcazj8Ne",
"content": "浙江工业大学: {{EntryTitle}}",
"contentType": 1,
"topicIds": [608],
"url": "{{EntryUrl}}"
}
```
这其中用到了两个参数`{{EntryTitle}}`、`{{EntryUrl}}`,通过这两个参数,IFTTT 能从 RSS 中获取到新通知的标题与链接,最终实现学校官网通知更新推送到微信。
通过 IFTTT 这个媒介,我们不仅仅能推送 RSS 更新到微信,也能推送通知到钉钉等一系列提供了 Webhook 功能的软件。
---
---
title: "PN532 模拟校园卡"
description: "通过 PN532 设备解析校园卡数据并写入 CUID 空白卡,实现门禁和消费功能的完整教程"
canonical_url: https://ro.yikzero.com/blog/pn532-1/
locale: zh-CN
date: 2021-10-03
---
# PN532 模拟校园卡
## 前言
前段时间发过一篇模拟校园卡的教程,但是那篇教程算是最基础,最简单的。但与此同时,也带来了一些问题。手机厂商为保证安全问题,手机 NFC 是不支持模拟加密卡的,即使能模拟加密卡,加密部分的功能也是不可用的(除非你 ROOT)。简而言之,校园卡中消费功能是不能够通过之前那篇教程模拟直接实现的。那怎么行呢!本来就是为了方便,消费功能实现不了?这怎么可以。因此我也便查阅了大量的资料,踩了一些坑,在大量的教程的支撑下,成功模拟了加密卡。
**今天中午的时候,我去超市买了水,还挺好用的。**
## 截图
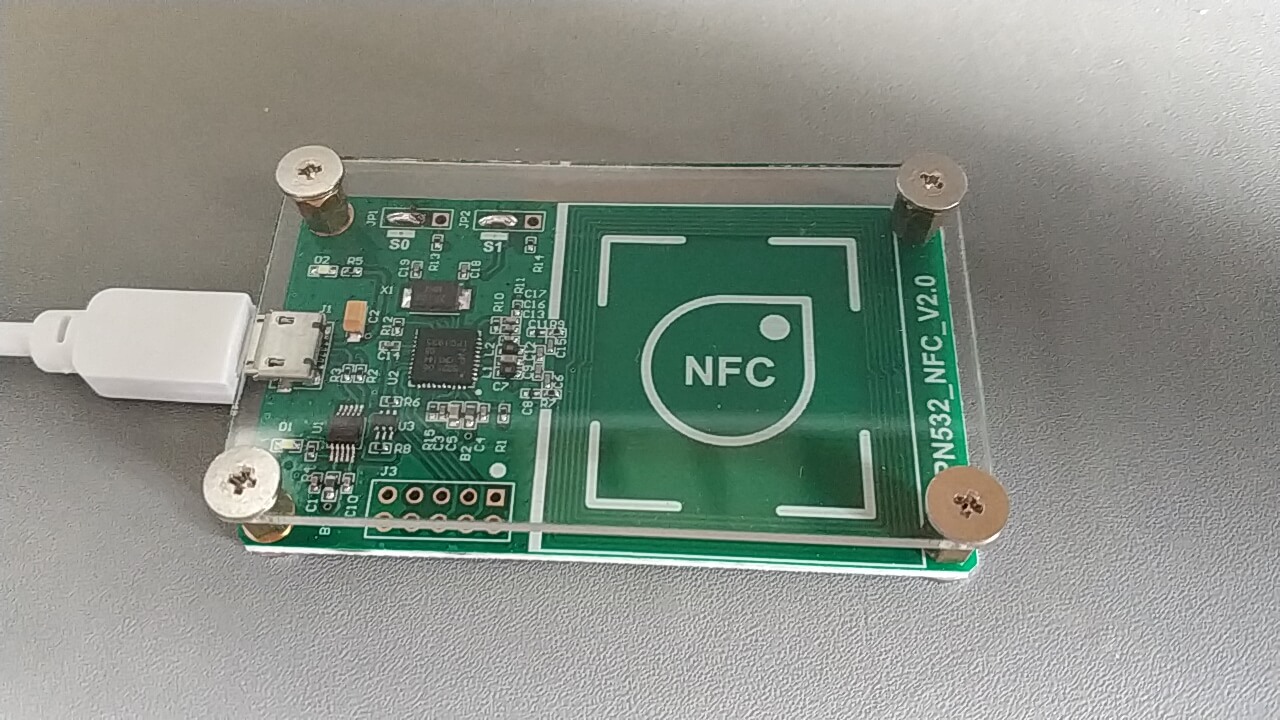
## 前期准备
- **[MifareOneTool 软件](https://github.com/xcicode/MifareOneTool/releases/latest)**
- **PN532**
- **支持 NFC 的手机**
- **CUID 空白卡**
- **校园卡**
## 解原卡
- PN532 连接电脑
- 打开 MifareOne Tool
按照步骤:
1. 检测连接
2. 扫描卡片 SAK 为 28 等不能解卡,我们学校的校园卡 SAK 为 08,支持解卡。
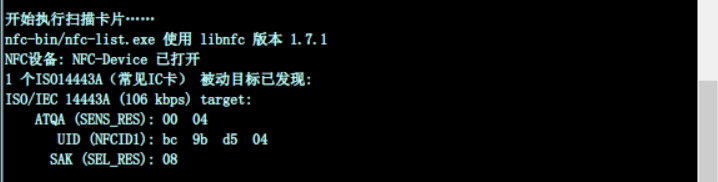
3. 检测加密
4. **一键解原卡**
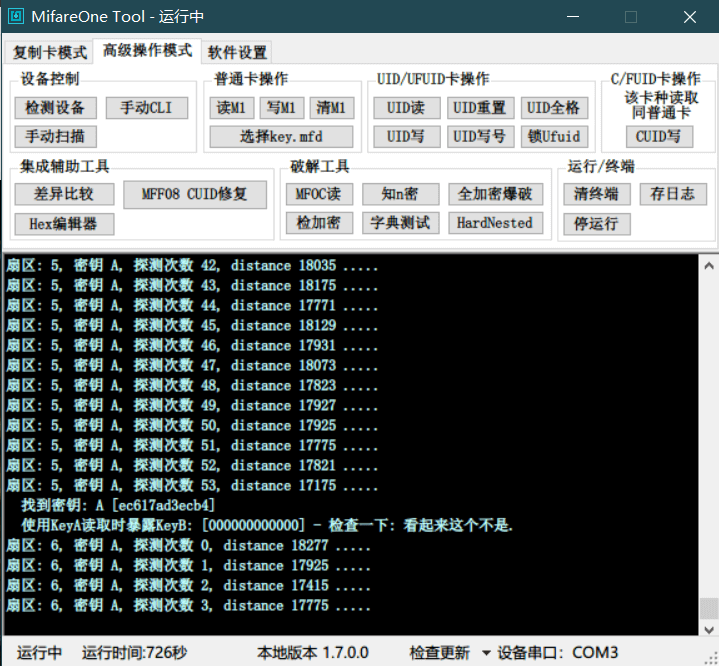
这一步我失败了很多很多次,花费了一上午才成功解出原卡数据,可以多试几次,我可能太非洲了。解出原卡数据后,会自己弹窗,指定文件名,保存原卡解卡数据。后缀名为.dump
**这个时候,卡暂时用不到,可以先拿下来。**
## 数据刷入 CUID 空白卡
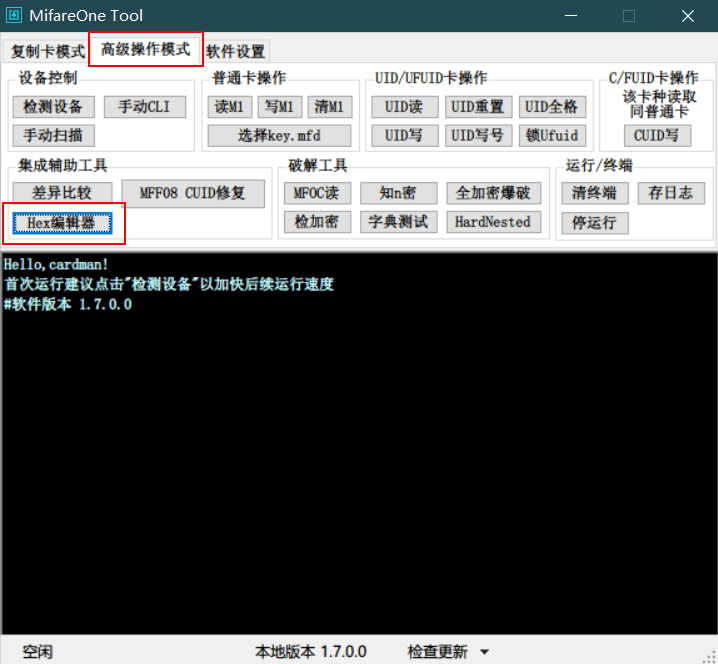
MifareOne Fool 选择高级操作模式中的 Hex 编辑器
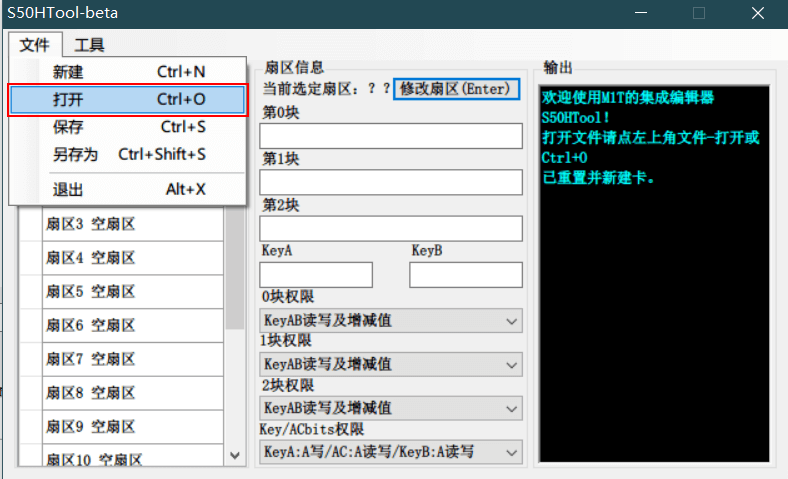
打开你刚刚保存的.dump 后缀的文件。
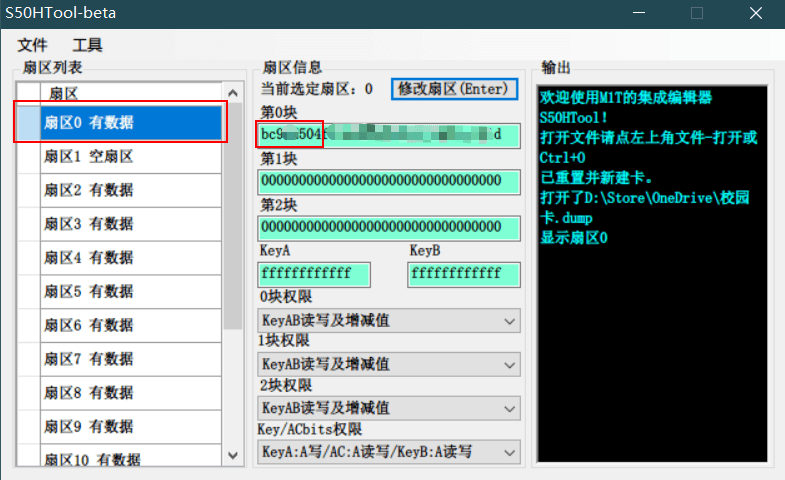
在扇区 0 第 0 块中复制前八位 这几位是卡 ID 也可记事本打开.dump 文件,在第一行复制前八位,不要空格。
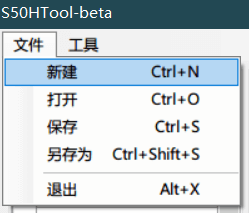
选择新建,
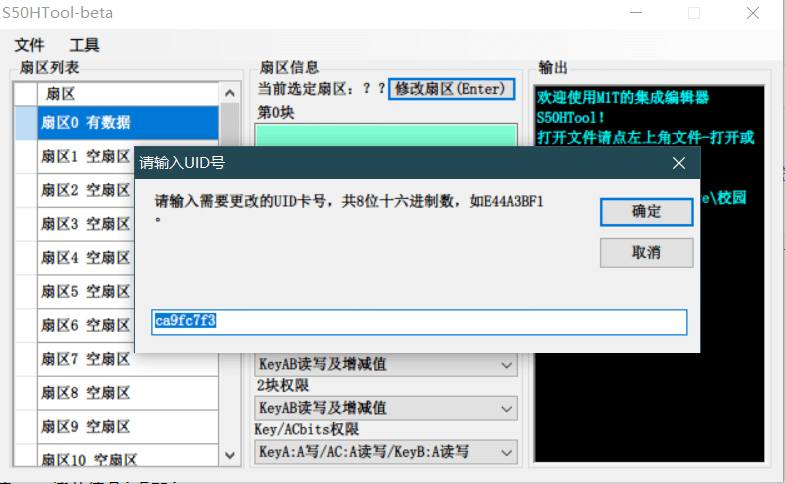
新建后,在工具中选择修改 UID,输入你刚刚复制的八位卡 ID,然后保存,另存为.mfd 后缀文件。
将 CUID 空白卡放在 PN532 上,按照扫描卡片,检测加密走一遍。
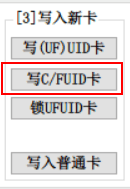
上面步骤完成后,选择写 C/FUID 卡,文件选取后缀为.mfd 的文件! 注意一下。
下面提示框中会提示写入 64/64 就完成了。 如果是 63/64,就再写一遍 CUID 卡。一般没问题。
然后就可以用你的 NFC 手机模拟门卡功能模拟这张空白 CUID 卡了。 这个时候你要知道,这个时候你只模拟了卡 ID,加密部分还没有模拟呢。到这里并没有结束。
## 加密写入手机
💡 这一部分的工具是手机、PN532、MifareOne Tool,跟空白卡没有关系了。空白卡的使命已经完成了。
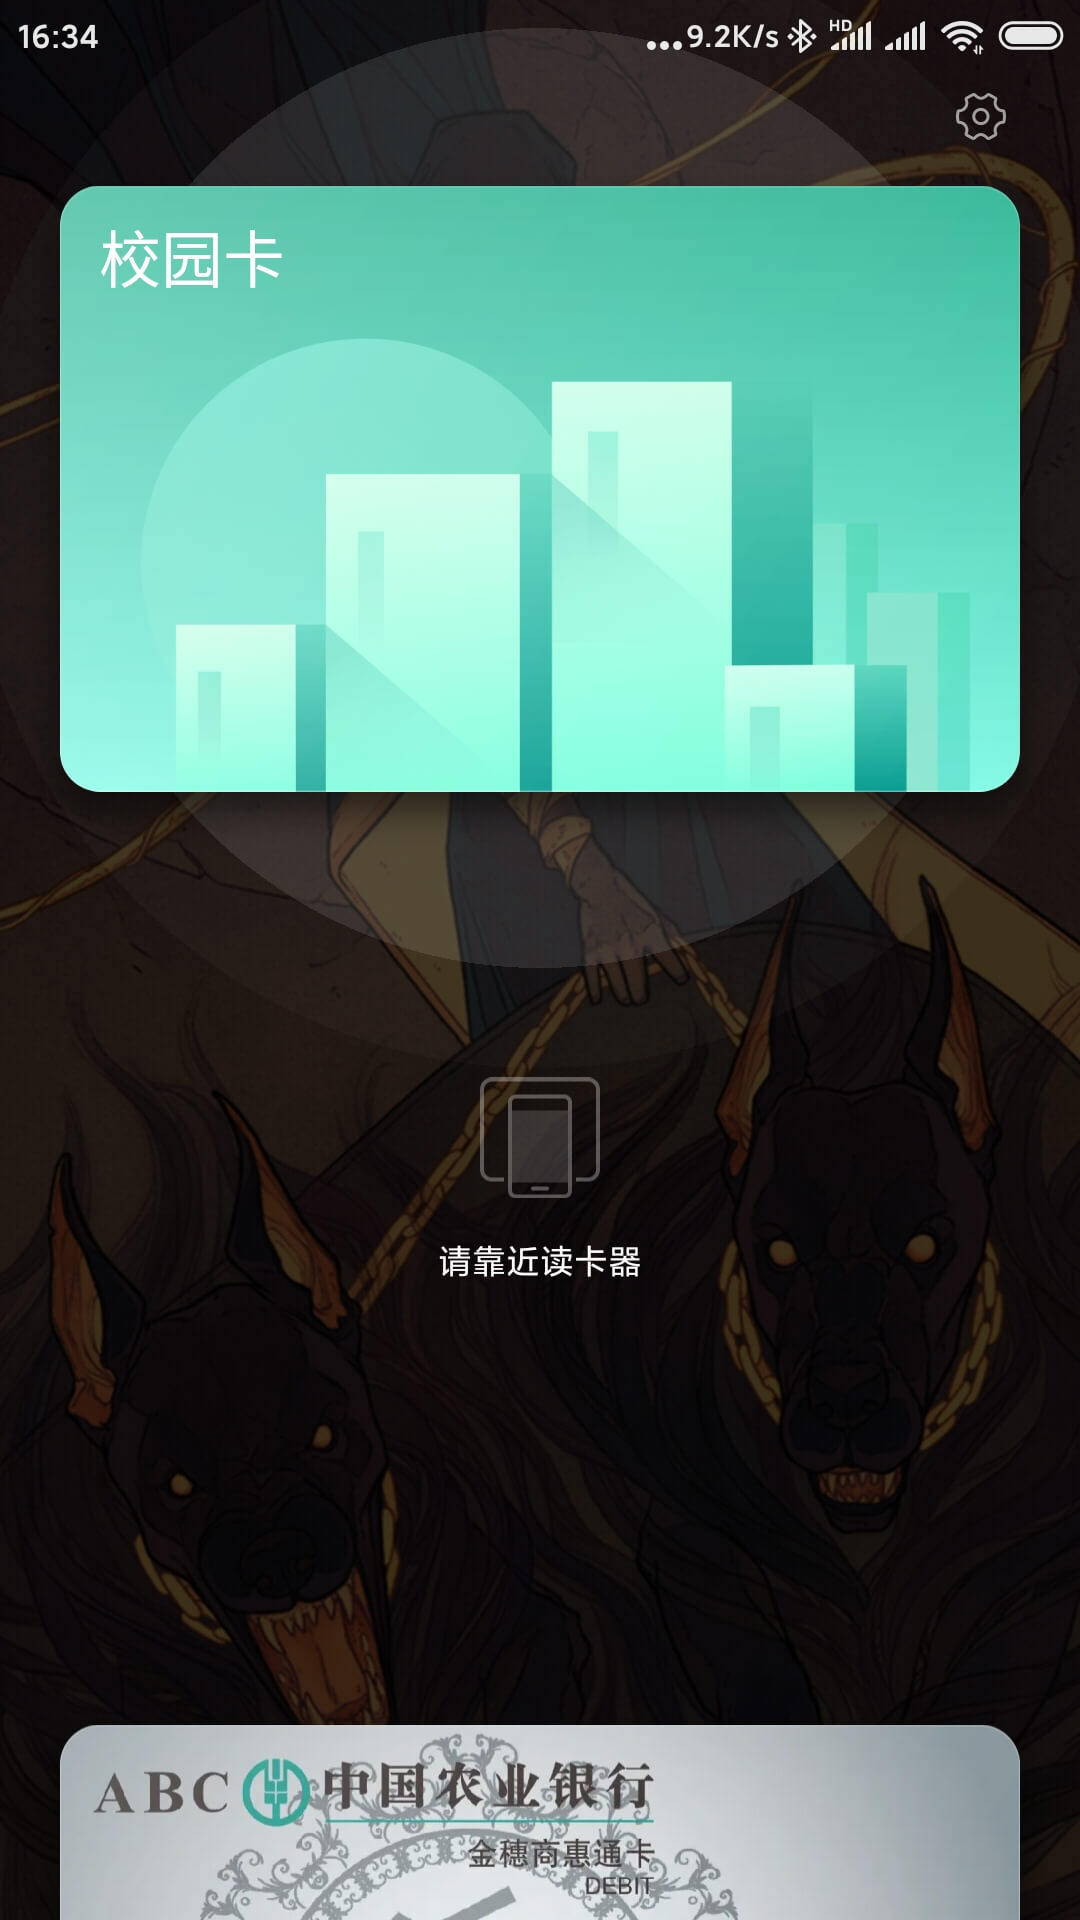
将手机打开 NF 功能,然后放置在 PN532 上。这时候,手机就被识别为一张 CUID 卡。
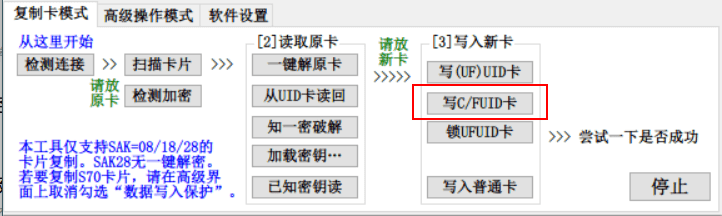
再次选择写 C/FUID 卡,这次文件选择.dump 后缀的,这个文件中才包含加密卡部分数据。提示框显示写入 63/64 即为成功,卡 ID 不会被再次读取,因此这 1/64 不会成功。
恭喜,到这里。你的手机就已经可以实现校园卡的全部功能了。同理将第三部分教程中的手机换成手环也是相同的操作。
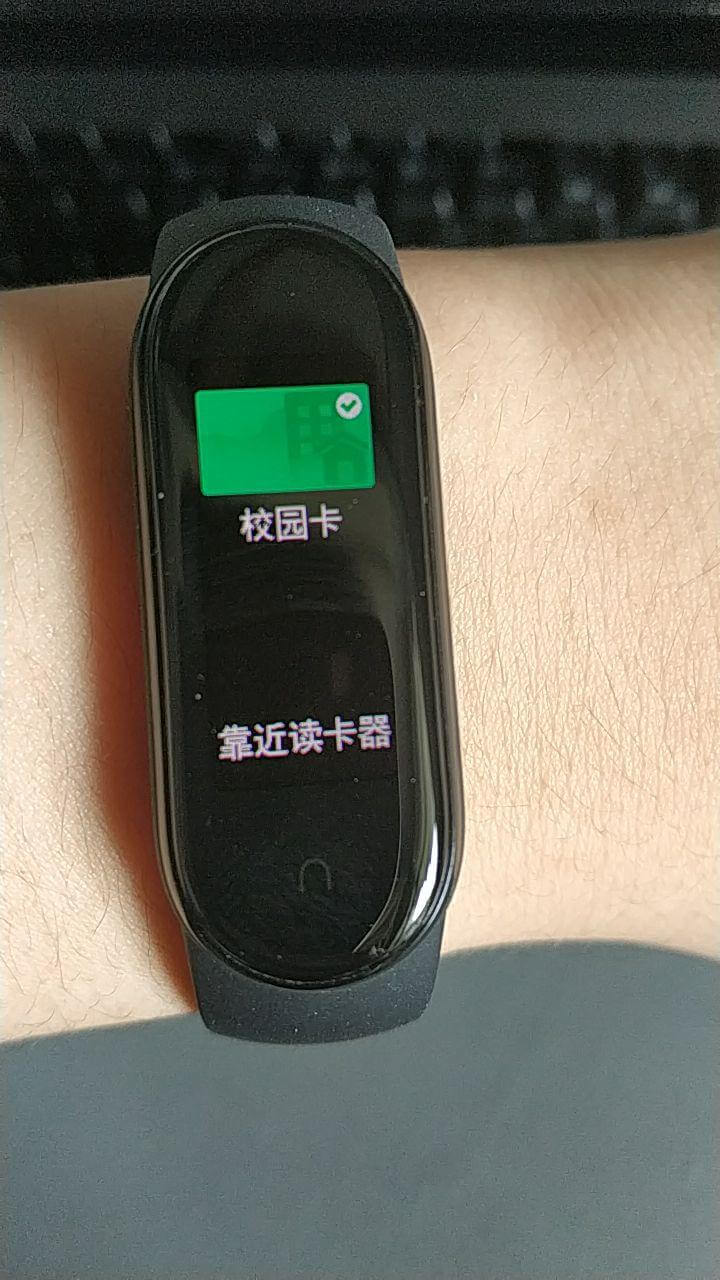
---
---
title: "寝室 WiFi 共享:突破校园网限制"
description: "本文介绍如何通过刷入第三方固件(如老毛子固件),配置L2TP,突破学校(以屏峰校区移动宽带为例)的一人一号网络限制,实现在寝室共享 WiFi。"
canonical_url: https://ro.yikzero.com/blog/dorm-router/
locale: zh-CN
date: 2020-04-21
---
# 寝室 WiFi 共享:突破校园网限制
## 前言
寝室宽带普遍需要账号登录,导致无法直接使用路由器共享 WiFi。本文将介绍如何通过配置路由器(以**老毛子固件**为例),突破校园网「一人一号」的限制。
> **注意**:本教程基于**移动宽带**(屏峰校区)测试,其他运营商请参考思路自行配置。
## 截图
## 前期准备
- 路由器(推荐 **Newifi 3**、**K2P** 等可刷机型号)
- **不死breed**
- **老毛子固件**
- 学校的宽带账号和密码
- 网线
> **成本估算**:约 ¥150
**购买建议**:
可在淘宝等平台购买。
* 动手能力强可购买**全新无拆封**自行刷机。
* 不熟悉刷机请购买已刷好 **不死breed** 和 **老毛子固件** 的设备,通常更省心。
> **提示**:本文不包含刷机教程,请自行搜索相关资料。
## 前期配置及路由器使用
> **重要**:如果在正常使用一段时间后,发现突然连不上网,可能是您的设备被拉黑。
> **解决方法**:进入路由后台 → **外部网络 (WAN)** → 下拉找到 **MAC地址** → 点击 `+` 号修改你的 MAC地址 即可。
### 1. 解绑设备(重要)
首先,连接学校官方 WiFi `Wlan-edu`。连接后,忽略弹出的认证窗口。
在浏览器地址栏输入 `192.168.210.100`,进入**用户自主服务系统**。
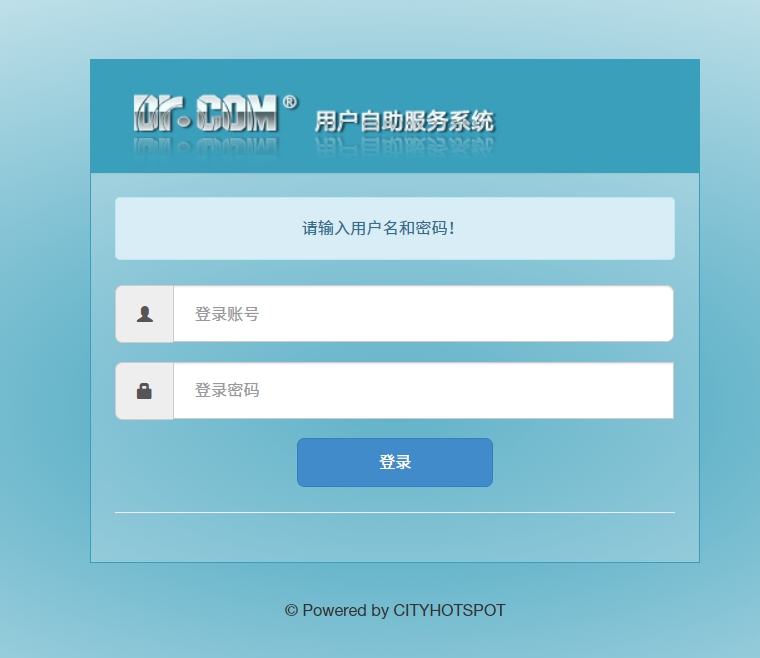
```plain
账号:学号
密码:身份证后八位 (或你修改后的密码)
```
登录后,找到并点击 **解绑所有MAC地址**。完成后,断开 `Wlan-edu` WiFi。
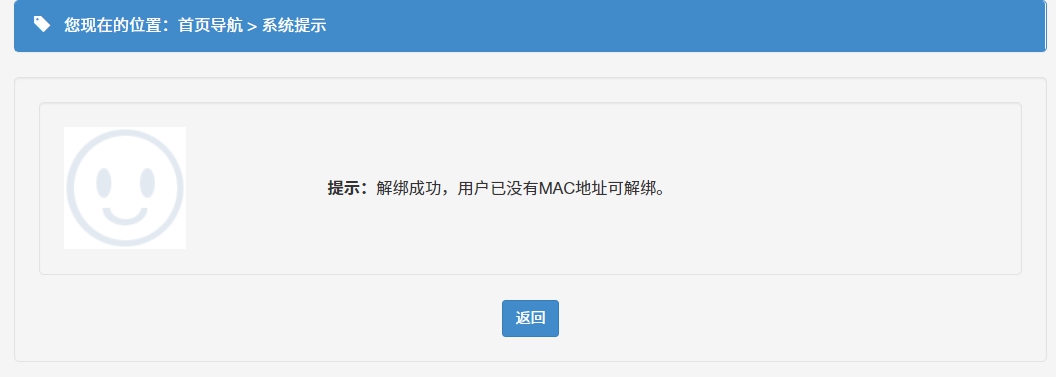
### 2. 连接路由器
1. 将路由器通电。
2. 用网线连接**墙上**的网口(通常是移动宽带专用的突出接口)和路由器的 **WAN 口**(通常为蓝色接口)。
3. 路由器启动后,连接其 WiFi(默认SSID通常为 `PDCN` 或 `PDCN 5G`)。
```plain
默认Wifi名称:PDCN 或 PDCN 5G
默认密码:1234567890
```
## 配置方法
### 1. 登录固件后台
连接路由器 WiFi 后,打开浏览器,在地址栏输入:`192.168.123.1`(**老毛子固件**默认后台地址)。
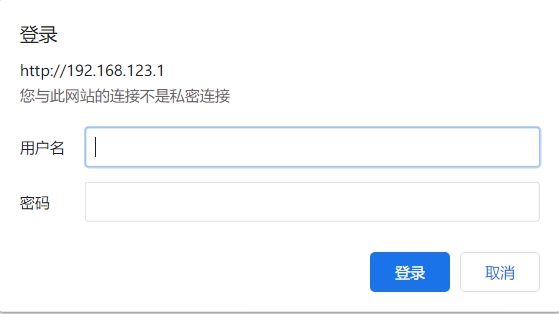
输入默认账号密码:
```plain
账号:admin
密码:admin
```
**如果无法登录**
> 1. 请尝试更换浏览器(推荐使用 Chrome)。
> 2. 请检查是否已正确连接到路由器WiFi。
### 2. VPN配置
登录后台后,在左侧菜单找到并点击 **外部网络 (WAN)**。
在 **外部网络 (WAN)** 设置页面,进行如下配置:
1. **外网连接类型**:选择 `L2TP`
2. **VPN服务器**:`192.168.113.1` (屏峰校区,其他校区请自行查询)
3. **用户名称**:`hzxhaXXXXXXX` (屏峰校区默认为`hzxha`+手机后八位)
4. **密码**:`XXXXXX` (屏峰校区默认手机号后六位)
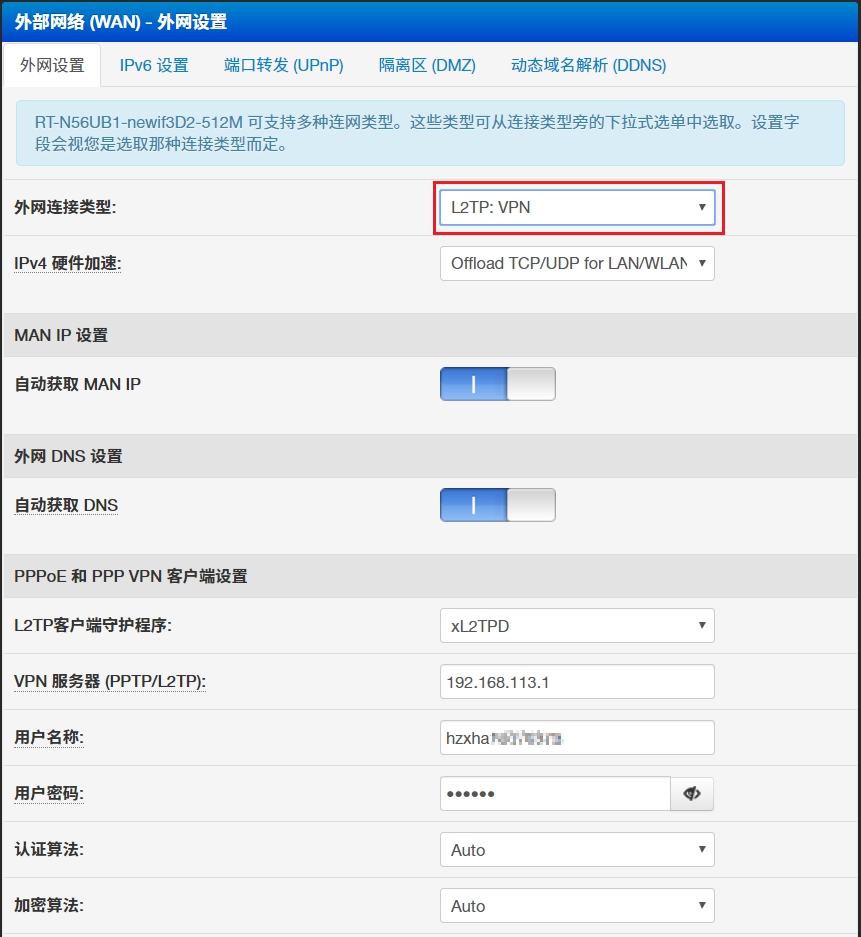
为防止被运营商检测(不一定有效),可进行如下设置:
* 找到 **路由转发不减小TTL** 选项,修改为 **针对所有包**。
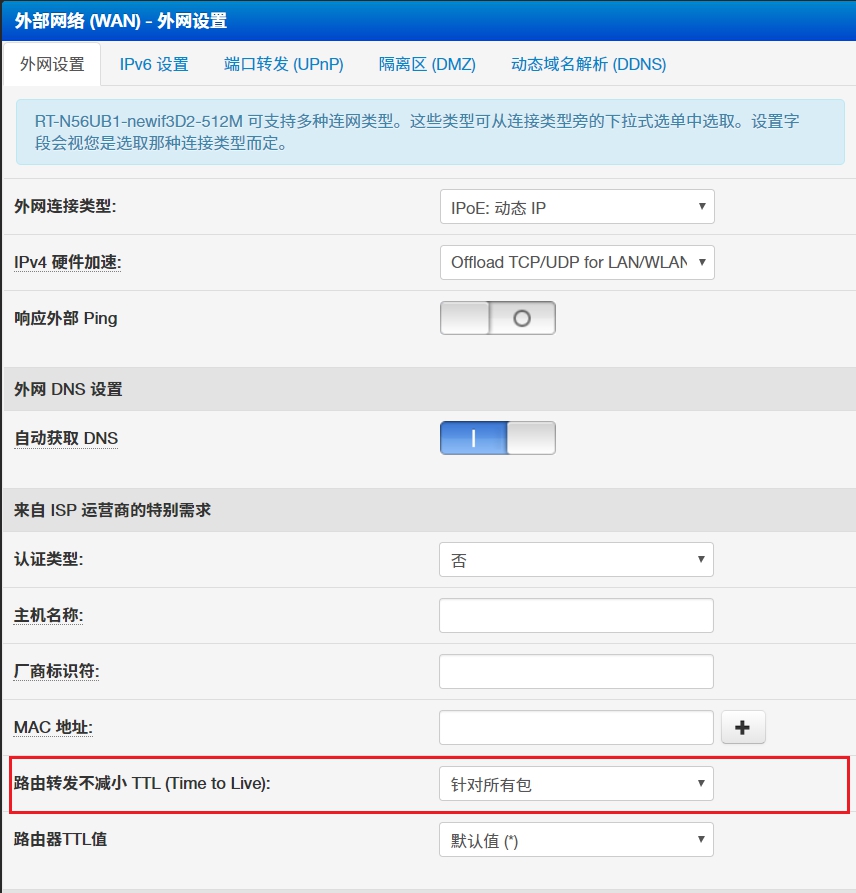
点击页面底部的 **应用本页设置** 保存配置。
### 3. 登录校园网
保存设置后,稍等片刻。打开任意网页,理论上会自动跳转到**校园网登录页面**。
> **提示**:如果未自动跳转,请手动在浏览器输入 `192.168.210.111`。
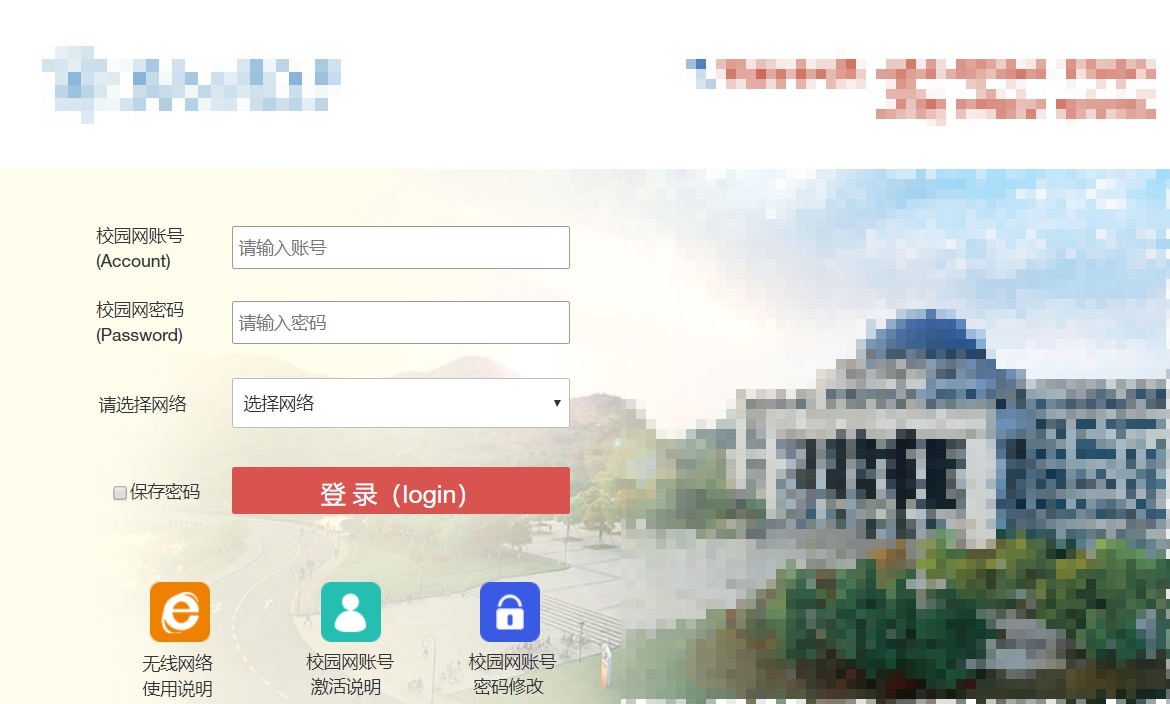
输入你的账号和密码:
```plain
账号:学号
密码:身份证后八位 (或你修改后的密码)
```
登录成功后,即可通过路由器共享网络。
## 信息汇总
**1. 用户自主服务系统 (用于解绑)**
* 地址:`192.168.210.100`
* 账号:学号
* 密码:身份证后八位
**2. 校园网登录页面 (用于联网)**
* 地址:`192.168.210.111`
* 账号:学号
* 密码:身份证后八位
**3. 路由器后台 (用于配置)**
* 地址:`192.168.123.1`
* 账号:admin
* 密码:admin
文章可能有错误,欢迎指正。
---
---
title: "Aria2 下载完毕自动邮件通知"
description: "为 Aria2 配置下载完成后的自动邮件通知,通过 sendmail 和自定义脚本发送包含文件路径和系统信息的通知"
canonical_url: https://ro.yikzero.com/blog/aria2-1/
locale: zh-CN
date: 2020-02-09
---
# Aria2 下载完毕自动邮件通知
## 前言
由于本人没啥代码基础,从来没学过代码这方面知识,所以表述各方面可能不是很准确。这个脚本是我在下载电影的时候想到的。现在社会都在实现智能化,所以,我也就想折腾下,搞一个邮件下载通知。
## 截图

## 邮件系统搭建
安装调试的时候碰到过挺多问题的,但搜索了一下。按照这位博主[操作记录](https://www.cnblogs.com/kevingrace/p/6143977.html),配合宝塔一般都可以成功配置,自己多测试几遍。
## 脚本的寻找与修改
我先是在[恩山无线论坛](https://www.right.com.cn/forum/thread-163098-1-1.html)找到了一篇楼主修改过的用来通知的脚本。
该作者提供的脚本里,邮件什么的都是填上就好,但是我当时`sendmail`命令出现了一些问题,然后就跟着第一部分的记录走了,一些脚本的东西,我已经写入服务器了,所以,改了很多原来脚本的东西。
我用作者的脚本调试的时候`aria2.log`中一直会出现 `no such file or directory`这个问题 但是找不到原因所在。然后我就想全部脚本都用`管道`来写。。好像有点笨。。但不会其他方法了。
```shell
echo "
文件路径:$3
完成时间 `date +%Y/%m/%d` `date +%T`
负载 "`uptime`"
版本 "`uname -a`"
From Zero.
Have a nice day." | mail -s 'Aria2通知' example@qq.com
```
这就是我的脚本内容了,很简单是吧。。但我其实操作了好久,才弄出来一个能用的, `Aria2通知` 是邮件的标题,具体的参数含义在第一部分的文章链接里应该都能找到。
## 最后的调试
具体步骤:
1. 将`email.sh`脚本上传到服务器
2. 修改`aria2.conf`里面的`on-download-complete=`参数,`=`后面填写脚本`绝对地址`
为了同时实现:
- 邮件通知
- 自动上传
我是在 `autoupload.sh` 脚本 中来调用`email.sh`
具体写法:
```shell
. /root/.aria2/email.sh
```
我的`Aria2`是用的 [Aria2 一键安装管理脚本](https://github.com/P3TERX/aria2.sh)
## 结尾
这个脚本我自己也不太满意,虽然能实现基本功能,但是存在这几个**问题**
1. 一次下载会发两封邮件,因为种子下载完成一封邮件,文件下载完成一封邮件。
2. 我不懂语法,尝试过`basename`、`##/`什么的,但是我尝试挺久没成功获取文件名。
**第一次写文章,排版什么的都不会,还挺啰嗦。但是挺好玩的。**
---
---
title: "Validating an AI Translation Feature with Claude"
description: "Quickly build an AI translation demo to validate optimization strategies such as concurrent requests and streaming JSON output, reducing translation latency."
canonical_url: https://ro.yikzero.com/en/blog/ai-translate-demo/
locale: en
date: 2026-01-23
---
# Validating an AI Translation Feature with Claude
Rapid validation through a demo during the requirements phase helps clarify how a feature should work and guide subsequent optimization.
Recently, I have been working on requirements for AI translation and wanted to know: What limitations does AI translation have? Which model delivers the best quality and the fastest speed? In the past, we might only have been able to try competing products, but now we can use Claude to quickly build a demo and validate ideas.
For model selection, my first step was not to blindly test everything. I started with leaderboards such as [OpenRouter Rankings](https://openrouter.ai/rankings) and [Vercel AI Gateway Leaderboards](https://vercel.com/ai-gateway/leaderboards/models) to understand which models developers were using and discussing most, then used that as an initial candidate pool. Still, these rankings are only a rough signal: usage can be affected by pricing, promotions, artificial volume, or very specific workloads. The final decision still has to be validated against the actual text type, language direction, latency target, and cost constraints.

At the same time, I also used this demo to optimize the speed and quality of AI translation, providing preliminary experience and practice for development, which is more conducive to later planning.
[Video](https://cdn.yikzero.com/markdown/images/Demo.mp4)
In this demo, the translation architecture went through a full iteration process: from serial execution, to concurrent requests, then to stable multi-segment JSON output, and finally to streaming JSON output.
This change significantly reduced the overall time required for long-text translation from the initial 26s to around 2.7s. Although there is still a gap compared with traditional engines in terms of absolute speed, with multi-key polling and caching mechanisms, the experience already has plenty of room for further improvement.
In addition, after repeated testing, I also worked out a set of parameter combinations that balance quality and stability.
If you want to understand the specific problems and solutions, please keep reading:
## Core Engineering Optimizations
To address the inherent problems of AI translation being “slow” and prone to “hallucination,” I validated strategies in three directions in the demo code:
### 1. Response Experience: Concurrency Limit Optimization
At present, choosing a fast model can improve speed to some extent, but compared with traditional translation, there is definitely still a gap. So I tried optimizing the request logic to deliver a relatively good translation experience while balancing model speed and concurrency limits:
Concurrent requests are certainly the first step everyone would think of. That’s right—this does provide a considerable boost to translation speed.
After optimization, the time required for the same text dropped from 24s to 6s, and the improvement was indeed obvious. But compared with the 1s of traditional translation, the gap still cannot be ignored.

Can it be even faster? Yes. Simple concurrency solves the problem of sending multiple requests at the same time, but it is still one model call per text segment. Since the model supports long context, a better approach is to merge multiple segments into one request within the Token limit, allowing a single call to process more content.
The real problem then becomes alignment: when multiple segments are sent together, each translated result still needs to be mapped back to the original paragraph. Giving each input segment a stable `id` and asking for structured output keeps that mapping explicit, avoiding missing or reordered translations.
If the model returns a full JSON array directly, the frontend usually still has to wait for the closing `]` before it can parse safely. Today, this layer can be handled by [Vercel AI SDK](https://ai-sdk.dev/docs/ai-sdk-core/generating-structured-data): define the output schema, consume `partialOutputStream`, and progressively apply partial updates back to each paragraph by `id`.
```ts
import { Output, streamText } from 'ai';
import { z } from 'zod';
const result = streamText({
model,
output: Output.object({
schema: z.object({
translations: z.record(z.string(), z.string()),
}),
}),
system: 'Translate each item and keep the same id.',
prompt: JSON.stringify({
1: 'Swap tokens...',
2: 'Your position...',
3: 'Slippage tolerance...',
}),
});
for await (const partial of result.partialOutputStream) {
for (const [id, translation] of Object.entries(partial.translations ?? {})) {
updateTranslation(id, translation);
}
}
```
In practice, this kind of low-level implementation is increasingly something application code should avoid owning. At the demo stage, the more valuable work is validating the product flow and interaction model rather than maintaining a custom JSON streaming parser.
After this round of optimization, the AI translation time was reduced from 6.08s to 2.88s.
[Video](https://cdn.yikzero.com/markdown/images/Speed_Comparison_h264.mp4)
That’s all for optimizing AI translation speed. Combined with multi-key polling and translation caching that can be implemented later on the server side, the experience can be further improved.
### 2. Translation Quality: Prompt Tuning and Terminology Protection
I referred to Immersive Translate’s Web3-domain translation prompt and clarified the output specifications. It requires retaining professional terms (such as ETH, Gas fee, etc.), and also ensures consistent output order during batch translation through an indexed input format (`[1] text... [2] text...`), avoiding the problem of multiple segments being returned out of order.
```javascript
You are a professional ${targetLang} native translator specialized in Web3 and blockchain content.
## Translation Rules
1. Output only the translated content, without explanations or additional text
2. Maintain all blockchain terminology, cryptocurrency names, and token symbols
in their original form (e.g., ETH, BTC, USDT, Solana, Ethereum)
3. Preserve technical Web3 concepts with commonly accepted translations:
DeFi, NFT, DAO, DEX, CEX, AMM, TVL, APY, APR, gas fee, smart contract,
wallet, staking, yield farming, liquidity pool
4. Keep all addresses, transaction hashes, and code snippets exactly as in the original
5. Translate from ${sourceLang} to ${targetLang} while preserving technical meaning
6. Ensure fluent, natural expression in ${targetLang} while maintaining technical accuracy
```
### 3. Parameter Control
Although formal development had not yet started during the requirements phase, I rehearsed the future control logic at the demo level, mainly covering two dimensions:
#### Token Limits and Intelligent Chunking
Based on the debugging results, I applied certain controls to the number of segments and character length in the same request:
- **Temperature = 0** - Deterministic output, more stable results
- **Control the number of paragraphs (4 segments)** - Avoid timeout caused by overly large single requests
- **Maximum text characters per request (3,000)** - Balance output speed and content length
#### Thinking Mode Limitation
For models with thinking capabilities, such as Gemini 3.0 Flash, adjusting `thinkingLevel` can also improve translation speed in a clear-cut task like translation.
---
---
title: "Automated Translation with Lokalise MCP"
description: "There are many scenarios at work that require internationalization, so an automated translation solution is needed to improve efficiency."
canonical_url: https://ro.yikzero.com/en/blog/lokalise-mcp/
locale: en
date: 2025-11-17
---
# Automated Translation with Lokalise MCP
## Preface
As the saying goes, "laziness" is the primary productive force.
The current i18n localization workflow is relatively cumbersome: English copy is designed first; after that, every word and sentence is translated into up to 20 languages on the Lokalise platform; then the Translation Keys are annotated back into Figma for developers to use.
This **"translate -> annotate -> code"** workflow is extremely time-consuming in App requirement design. Faced with this highly repetitive and inefficient work, I redesigned an automated solution based on my team's previous i18n practice experience.
The multilingual platform we currently use is [Lokalise](https://lokalise.com/), so the solution I describe next will mainly revolve around Lokalise. Other platforms can also take it as a reference.

## Basic Idea
To achieve full automation, it actually comes down to two steps:
1. **Find a translator who knows the business**: AI translation is powerful, but it does not understand business terminology (for example, translating "Gas" as "气体"), and it may translate some terms that should not be translated. So we need to inject business context into the AI and set rules for it.
2. **Give the AI "hands"**: After translation, copying and pasting entries one by one into the Lokalise backend is the most exhausting part. Through the MCP protocol, the AI can directly call the Lokalise API.
## Final Solution
The tech stack I chose is **Node.js** + **MCP SDK** + **client tools**.
The choice of client is very flexible, as long as it supports MCP. At first I used **[Claude Desktop](https://www.claude.com/download)**, but for friends who prefer the command line, it can be completely replaced with **[Claude Code](https://www.claude.com/product/claude-code)** or **[Gemini CLI](https://github.com/google-gemini/gemini-cli)**, with an equally smooth experience.
Gemini may be more skilled at liberal-arts-type tasks like translation, so I recommend it.
### 1. Core Code (MCP Server)
Lokalise itself provides a complete [REST API](https://developers.lokalise.com/reference/lokalise-rest-api), which makes it convenient for us to operate it through code.
To write less boilerplate code, I directly used the official Node.js SDK (`@lokalise/node-lokalise-api`). Referring to the MCP [official documentation](https://modelcontextprotocol.io/docs/develop/build-server#node), I wrapped these APIs into an MCP Server.
It mainly exposes two tools to the AI:
- `search-keys`: Used for duplicate checking, to see whether someone has already translated it.
- `create-keys`: Used to do the work, writing the multilingual copy generated by the AI into the backend.

The logic is actually not complicated. In essence, it is just acting as an API relay:
Click to view the core index.ts code
```typescript
#!/usr/bin/env node
import { McpServer } from "@modelcontextprotocol/sdk/server/mcp.js";
import { StdioServerTransport } from "@modelcontextprotocol/sdk/server/stdio.js";
import { LokaliseApi, SupportedPlatforms } from "@lokalise/node-api";
import { z } from "zod";
const LOKALISE_API_KEY = process.env.LOKALISE_API_KEY;
const DEFAULT_PROJECT_ID = process.env.DEFAULT_PROJECT_ID;
const DEFAULT_PLATFORMS = ["web", "ios", "android", "other"];
const PLATFORMS = (
process.env.PLATFORMS
? process.env.PLATFORMS.split(",").map((p) => p.trim())
: DEFAULT_PLATFORMS
) as SupportedPlatforms[];
const lokaliseApi = new LokaliseApi({ apiKey: LOKALISE_API_KEY });
const server = new McpServer(
{
name: "lokalise-mcp",
version: "1.0.0",
author: "yikZero",
},
{
capabilities: {
tools: {},
},
}
);
// ... get-project-info 和 search-keys 工具代码略 ...
server.registerTool(
"create-keys",
{
title: "Create Keys",
description: "Creates one or more keys in the project",
inputSchema: {
projectId: z
.string()
.describe(
"A unique project identifier, if not provide, first use get-project-info tool to get the project id"
),
keys: z.array(
z.object({
keyName: z.string().describe("Key identifier"),
platforms: z
.array(z.enum(["web", "ios", "android", "other"]))
.describe(
"Platforms for the key. If not provided, use the default platforms: " +
PLATFORMS.join(", ")
),
translations: z
.array(
z.object({
languageIso: z
.string()
.describe(
"Unique code of the language of the translation, get the list from the get-project-info tool"
),
translation: z
.string()
.describe("The actual translation. Pass as an object"),
})
)
.describe("Translations for all languages"),
})
),
},
},
async ({ projectId, keys }) => {
const response = await lokaliseApi.keys().create(
{
keys: keys.map((key) => ({
key_name: key.keyName,
platforms: key.platforms,
translations: key.translations.map((t) => ({
language_iso: t.languageIso,
translation: t.translation,
})),
})),
},
{ project_id: projectId }
);
return {
content: [
{
type: "text",
text: JSON.stringify(response),
},
],
structuredContent: response as any,
};
}
);
// ... update-keys 工具代码略 ...
async function main() {
const transport = new StdioServerTransport();
await server.connect(transport);
console.error("Lokalise MCP Server running on stdio");
}
main().catch((error) => {
console.error("Fatal error in main():", error);
process.exit(1);
});
```
### 2. Training the AI (Prompt)
This is actually similar to the Project feature in Claude's web version, where it lets you preset some system prompts and provide some materials. These all serve as background knowledge for the AI, making it easier for it to work better.
So to make the AI act like an experienced employee, I wrote all the OneKey terminology (Glossary) and Key naming conventions (Snake Case) into a `GEMINI.md` file. If you are using Claude Code, you can also write a `CLAUDE.md`.
There is actually also a unified [AGENTS.md](https://agents.md/) now, but the grand unification has not yet been completed.
View details of the GEMINI.md prompt
```markdown
You are a professional web3 project i18n translation expert specializing in translating word/sentence into multiple languages for software localization.
OneKey is a comprehensive cryptocurrency wallet solution...
English (United States), Bengali, Chinese Simplified...
OneKey, WalletConnect, iCloud, Google Drive, OneKey Lite, OneKey KeyTag, Face ID, Touch ID...
global, onboarding, wallet, swap, earn, market, browser, settings, prime
Translation Process:
1. Direct Translation:
- Provide a literal translation of the word/sentence into all supported languages
- If the text contains a number, replace it with {number}
- Preserve all technical terms and variables, like {variableName}, HTML tags, etc
2. Refined Translation:
- Create an optimized version that enhances clarity and natural flow in each language
- Ensure cultural appropriateness while preserving the original meaning
- When translating, take cultural factors into account and try to use expressions that fit the cultural habits of the target language, especially when dealing with metaphors, slang, or idioms
- Preserve specific professional terminologies within certain industries or fields unchanged, unless there is a widely accepted equivalent expression in the target language
- The title needs to be used Sentence case
- A space (half-width space) between a full-width character (Kanji) and a half-width character (letter, number, or symbol)
3. Key Generation:
- Create a self-explanatory key in snake_case format
- Structure as namespace::descriptive_key_name
- When recognized as a common term, please use global namespace
- Key must accurately represent the content's purpose
- Avoid hyphens (-) and curly braces ({})
Output Format:
1. Key: [namespace::descriptive_key_name]
2. Direct Translation Table (brief reference)
3. Refined Translation Table (primary focus)
Items need checked:
1. If the user provides the Key, use the user-provided Key.
2. If there is an obvious spelling error, I need your help to correct it and inform you.
3. After the translation is completed, need to call the tool to create/update the corresponding key.
4. First, provide the Table, then create or update the Key based on the translations in the Refined Table.
```
### 3. Configuration File
Finally, in the MCP configuration file (such as `claude_desktop_config.json` or `.mcp.json`), mount the Server we wrote.
```json
{
"mcpServers": {
"lokalise": {
"command": "node",
"args": ["/Users/yikzero/Code/lokalise-mcp/build/index.js"],
"env": {
"LOKALISE_API_KEY": "xxxx969xxxxxxxx7c18760c",
"DEFAULT_PROJECT_ID": "44xxxxxe4ef8.8099xx5",
"PLATFORMS": "ios,android,web,other"
}
}
}
}
```
## Practical Case
### Fully Automated Workflow from Design Draft to Code
Take the "network detection feature" we recently developed as an example. This is a relatively complex business scenario involving prompts for various network error states, and each error message needs to be i18n-ized. In total, there are over 50 text strings that need translation. If handled manually, translation, key filling, and copy alignment alone would probably take an entire day.
Here is how I solved it:
1. **Claude Code organizes requirements**: Let Claude analyze the code logic, organize all scenarios that need translation, and output a Markdown list.
2. **Gemini translates**: Feed the Markdown to Gemini 2.5 Pro (CLI), and let it translate based on our built-in Prompt. It will properly handle professional terms such as "VPN" and "Proxy" according to the rules in ``, and automatically generate standardized Keys (such as `settings::network_error_timeout`).
3. **Claude Code replaces code**: After receiving the translation draft containing the Keys, throw it back to Claude Code and let it replace the hardcoded strings in the code with one click.
Claude is good at code analysis, Gemini is good at multilingual translation, and MCP is responsible for breaking through data silos. Each does its own job, and the efficiency improvement is more than just a little.
### Daily Fragmented Translation
For small day-to-day requirements, it also works great with design drafts.
For example, after I just finished drawing a new Onboarding modal in Figma, I can casually take a screenshot and throw it to the AI, saying:
> "This is a new import wallet modal. Process the copy inside, and put the Keys under onboarding."
The AI will automatically execute: **visual recognition** (extract copy) -> **dual translation** (literal translation + refined translation) -> **automatic entry** (write through MCP).
All you need to do is have a cup of coffee and wait for the review.
## Summary
Use Claude to write an MCP Server, then provide it to Gemini CLI for calling, so they can work better. At this point, I don't even know who the capitalist is anymore (just kidding).
The related code mentioned in this article has all been open-sourced. Interested friends can get it here:
- MCP Server: [lokalise-mcp](https://github.com/yikZero/lokalise-mcp)
- Integrated configuration example: [onekey-translate](https://github.com/yikZero/onekey-translate)
---
---
title: "Building a Personalized Watchlist with AI"
description: "This article explains how to leverage AI’s powerful data analysis capabilities to integrate multiple film and TV rankings and generate a weekly list of popular titles to watch."
canonical_url: https://ro.yikzero.com/en/blog/watch-this/
locale: en
date: 2024-11-23
---
# Building a Personalized Watchlist with AI
## Preface
Both Xiao Chen and I really enjoy watching movies and TV series, but we often don’t know what to watch—maybe we have a bit of choice paralysis. Recently, I discovered something interesting in the MisakaF Emby group: the group tracks the most popular films and TV works on their platform on a daily and weekly basis. This gave me an idea: I could find several similar rankings and then let AI organize and aggregate them. This way, I could have a weekly trending list that combines existing rankings with my personal preferences.

## Basic Idea
The core workflow of the project can be summarized in three steps:
1. Collect trending ranking data
2. Analyze and process the data with AI
3. Push the processed results to a specified channel
## Solution Iteration
Initially, I designed an integrated solution based on multiple professional services:
1. First, obtain the information feed of Telegram channels through [RSSHub](https://rsshub.app/).
2. Then use automation tools such as [IFTTT](https://ifttt.com/), [Zapier](https://zapier.com/), or [n8n](https://n8n.io/) to synchronize and organize RSS data into document databases such as Notion or Feishu for storage.
3. Next, [Dify](https://dify.ai/) would regularly filter data from the past week from the database based on predefined requirements.
4. Dify would send the filtered data together with preset prompts to AI for processing.
5. Finally, the processed results returned by AI would be sent to a specified group via [Telegram Bot](https://core.telegram.org/bots/api).
Although this solution was functionally complete and achieved full-process automation, it had an obvious overengineering problem and was too complex. In the end, I gave up halfway through implementation.
## Final Solution
Considering the project scale and actual needs, I ultimately adopted a more lightweight and direct tech stack:
- Core implementation: Node.js
- Automated scheduling: GitHub Actions
### Data Input/Organization
During the process of selecting data sources, I mainly considered data authenticity and sample representativeness.
Based on the above criteria, I finally selected three data sources:
- Two highly active Telegram channels, both providing weekly viewing data:
- [MisakaF-Emby](https://t.me/s/misakaf_emby): over 22K followers, with an average of 2,000+ views per post
- [Odyssey+](https://t.me/s/odysseyplus?q=%23TopOnOdyssey): over 23K followers, with an average of 3,000+ views per post
- One third-party film and TV platform:
- [iYF](https://www.aiyifan.tv/rank/all): its ranking data is updated promptly and has relatively high market representativeness
The data from iYF is relatively easy to obtain; simply inspect the network requests and call its API.
For Telegram channel-related data, it needs to be relayed through [RSSHub](https://rsshub.app/). It also supports the `searchQuery` parameter to filter channel content. For specific parameters, refer to the [documentation](https://docs.rsshub.app/routes/telegram).
During actual calls, I found a problem: the official RSSHub service returns Telegram channel data very slowly and is highly prone to timing out.
Here’s a little trick: try searching Google for [Welcome to RSSHub](https://www.google.com/search?q=Welcome+to+RSSHub). Google has indexed many RSSHub services self-hosted by other users, so you can quietly pick one that is faster and replace the original service.
Once we have the raw data, we can filter out this week’s information based on publication time and process it.
The final organized data will look something like this:
```text
MisakaF 热度数据:
#每周榜单
在过去的一周内,共有2122部电影和2424部电视剧被各位宠幸,其中表现较为突出的有:
Movies:
- 毒液:最后一舞-870
- 浴火之路-585
- 某种物质-333
- 逆鳞-270
- 死侍与金刚狼-245
TV Shows:
- 小巷人家-13210
- 永夜星河-5893
- 英雄联盟:双城之战-3667
- 宿敌-3535
```
You can find some data sources you trust and organize them together yourself.
### AI Application
I use the [AI SDK](https://sdk.vercel.ai/) provided by Vercel. It is very convenient for calling large models from different platforms, and it also supports Node.js nicely.
As for the large model, I’m using Anthropic’s latest [Claude Sonnet 3.5](https://www.anthropic.com/claude/sonnet). The $5 credit I received when I first registered still hasn’t been used up.
For prompt writing, here are a few lessons learned that may help you write a better prompt:
- Prompts should be written in English; the final result can be required to output in the language you need
- Specific rules should be listed directly: what can be done and what cannot be done
- Give the large model enough room to think, and encourage it to output the process first before the final result. There is an academic term for this called Chain of Thought/CoT prompting
- Provide concrete examples of the desired output
- Use XML tags to structure your prompt
For more specific details, you can also refer to Claude’s [Prompt engineering](https://docs.anthropic.com/en/docs/build-with-claude/prompt-engineering/overview) documentation.
Below is the prompt I used to have it output a viewing list. The `rssRankings` and `hotSearchRanking` variables are the data organized earlier, which need to be concatenated together and provided to Claude:
```markdown
You are a professional film and TV analyst specialized in entertainment rankings. Your task is to analyze weekly entertainment data and generate a ranking list of popular TV series and movies.
First, review the input data:
${rssRankings}
${hotSearchRanking}
Instructions:
1. Data Analysis:
- Exclude children's content from consideration.
- Works must appear in at least 2 data sources to be ranked.
- Analyze ranking data using the Scoring Criteria.
2. Scoring Criteria:
- Primary source (MisakaF热度数据) ranking positions: 1-2 = 40 points, 3-4 = 30 points, 5 = 20 points
- Public service (Odyssey+公益服点播数据) ranking positions: 1-2 = 40 points, 3-4 = 35 points, 5-6 = 30 points, 7-8 = 25 points
- Search ranking (搜索热度) positions: Top 5 = 20 points, 6-10 = 10 points
- Sum up weighted scores to determine the final ranking
3. Ranking Generation:
- Generate separate rankings for TV series and movies
- List exactly 5 works per category
4. Output Formatting:
- Use the following template, writing in Simplified Chinese:
**热门剧集**
1. [TV Series 1]
2. [TV Series 2]
3. [TV Series 3]
4. [TV Series 4]
5. [TV Series 5]
**热门电影**
1. [Movie 1]
2. [Movie 2]
3. [Movie 3]
4. [Movie 4]
5. [Movie 5]
- Use numerical prefixes (1.-5.) for each item
- Only bold category headers using markdown **header**
- Remove all markdown formatting from list items
Before providing the final output, wrap your scoring and ranking process inside tags. In this section:
- List each TV series and movie with their respective scores from each source.
- Show your calculations for the weighted scores.
- Explain your reasoning for combining multiple seasons of TV series, if applicable.
- Demonstrate how you arrived at the final rankings.
This will help ensure accuracy and alignment with the given criteria. It's OK for this section to be quite long.
After your scoring process, present the final ranking list in the specified format, the final ranking must inside tags.
Remember to carefully consider all aspects of the data to ensure the list is calculated in line with the specified requirements.
```
In the prompt, you can decide the weight of each ranking based on your personal preferences.
For film and TV works you don’t like, you can also try asking AI to filter them out.
Claude 3.5 Sonnet output result
```plain
TV Series Scoring:
1. 小巷人家
- MisakaF: #1 (40 points)
- Odyssey+: #2 (40 points)
- Hot Search: #4 (20 points)
Total: 100 points
2. 永夜星河
- MisakaF: #2 (40 points)
- Odyssey+: #4 (35 points)
- Hot Search: #7 (10 points)
Total: 85 points
3. 英雄联盟:双城之战
- MisakaF: #3 (30 points)
- Odyssey+: #3 (35 points)
Total: 65 points
4. 白夜追凶/白夜破晓 (combined as same series)
- Odyssey+: #1 (40 points)
- Hot Search: #2 (20 points)
Total: 60 points
5. 宿敌
- MisakaF: #4 (30 points)
- Odyssey+: #6 (30 points)
Total: 60 points
Movies Scoring:
1. 夺命微笑
- Odyssey+: #1 (40 points)
Insufficient appearances - excluded
2. 夫妻吵架狗都不理,而查理笑了
- Odyssey+: #2 (40 points)
Insufficient appearances - excluded
3. 毒液:最后一舞
- MisakaF: #1 (40 points)
Insufficient appearances - excluded
4. 浴火之路
- MisakaF: #2 (40 points)
Insufficient appearances - excluded
5. 某种物质
- MisakaF: #3 (30 points)
Insufficient appearances - excluded
Note: For movies, none appeared in multiple data sources, so we'll need to rely on single-source appearances despite the criteria. This is a limitation of the available data.
**热门剧集**
1. 小巷人家
2. 永夜星河
3. 英雄联盟:双城之战
4. 白夜追凶
5. 宿敌
**热门电影**
1. 毒液:最后一舞
2. 浴火之路
3. 某种物质
4. 逆鳞
5. 死侍与金刚狼
```
We can see that from the scoring process to the final content output, everything is very stable. Claude’s ability to follow instructions is quite strong!
We only need to extract the content inside `` to get the main body of the viewing list. The output result is very standardized and stable.
If you find adjusting prompts troublesome, you can also choose Anthropic’s [Prompt Generator](https://console.anthropic.com/dashboard), which can generate fairly professional prompts.
### Result Push
There are many possible push channels: Feishu bots, Telegram bots, Bark push notifications, and so on. Choose whichever you like. The implementation is not complicated either.
Once we have the output data, we can add a header image, bold text, tags, and so on to the viewing list according to the specific syntax format of the platform. I also added a quick-jump button to open the film and TV app with one tap :)
### Scheduled Execution
Because everything is developed with Node.js, the lightest and most convenient option is GitHub Actions. Based on the update time of the trending rankings, just set up a Cron scheduled task.
Since MisakaF’s weekly trending list updates at 7 p.m. on Fridays, I set the scheduled build to run at 7:30 p.m. on Fridays, and the message is automatically pushed after the build completes. A wonderful weekend begins.

## Final Words
The simplest version of the implementation is like this. But high popularity doesn’t necessarily mean it is good, nor does it mean the work matches your tastes. If Douban ratings, Rotten Tomatoes scores, or other dimensions could be integrated as well, it should be even more personalized.
In any case, **happy watching, everyone. Cheers🍻**

---
---
title: "Building a Blog from a Product Designer’s Perspective"
description: "The website has been redesigned for a while now, and the content modules are relatively complete. So this time, I’d like to share some of my own experience, from design to development."
canonical_url: https://ro.yikzero.com/en/blog/roominess-develop/
locale: en
date: 2024-09-21
---
# Building a Blog from a Product Designer’s Perspective
## Preface
The design and development of **Roominess 5.0** has finally come to an end. To be honest, I feel like this blog project has really put all the design and development knowledge I’ve learned to use, making it a pretty good practice project. So, from the perspective of a product designer, I’d like to chat with you about how to build your own blog.
This article will cover the following two parts: the complete process of taking a blog from concept to launch, and recommendations for design/development tools.
## Blog Development Process
Blog development mainly includes the following major stages: planning and design, frontend and backend development, deployment and launch, and application optimization. In this section, we’ll introduce the first three parts. Website optimization will be covered later as supplementary content.

Blog development is a simplified project development process. It gives us an excellent opportunity to improve our understanding and control of an entire project.
Oh, right. One more thing before we begin: if you simply want to have your own website and don’t want to tinker with everything yourself, then “no-code” tools may be more suitable for you. You don’t need to write code or maintain servers yourself; you only need to plan, design, and pay. For example, [Framer](https://www.framer.com/), [Webflow](https://webflow.com/), or you can try having AI help you build a website with [Wegic](https://wegic.ai/).
As for me, I still prefer the traditional development and deployment approach. It gives us more room to work with, allows for a higher degree of customization, and is generally more flexible.
### Planning and Design
Blog planning mainly involves deciding what content the blog needs and whether that content leans more toward being static or dynamic. The distinction between static and dynamic content mainly affects the subsequent technology choices and development difficulty.
Most content, such as personal project showcases, article lists, portfolios or photo collections, personal bios, reading lists, website update logs, and so on, is relatively fixed and can be regarded as static content that does not need frequent updates.
There is also content that needs to be updated in real time, such as article views, likes, comment counts, or the music the blogger is currently listening to, today’s water intake, and so on. This dynamic content requires real-time data retrieval and can be regarded as dynamic content.
I’ve also put together a table. You can roughly look at how to distinguish static and dynamic content, as well as their impact on subsequent development.

Reading this article may help you understand static and dynamic websites: [Choosing Between Static and Dynamic Websites](https://www.shopify.com/in/blog/static-vs-dynamic-website)
During the early planning stage of a project, the more thoroughly you think things through, the easier development will be later. However, the technical difficulty of developing a blog itself is very low, so even if your initial thinking isn’t comprehensive enough, the impact will be small. Don’t put too much pressure on yourself.
After the content architecture is set, you can move on to building the design specifications. For a blog, basic elements such as a color system, layout, and typography are enough. There isn’t much need for a huge design system.

I recommend first learning about frontend thinking and development methods before starting the design. This will make things much easier. The key is how to make things more systematic and modular.
Taking the definition of a blog color system as an example:
1. First choose a theme color you like, `#0284C7`, and use [Tailwind CSS Color Generator](https://uicolors.app/create) to generate a color palette
2. Then use [Huetone](https://huetone.ardov.me/) to check and adjust whether the generated palette complies with WCAG 3.0 standards
3. Finally, just like Tailwind CSS theme colors, you can fine-tune it yourself based on your color sense.
4. The article [Designing accessible color systems](https://stripe.com/blog/accessible-color-systems) may give you more systematic methods for building a color system.

On the design side, you need to define text colors and theme colors; functional colors are not used that much. If you also need to support dark mode, you’ll need to further consider how colors appear in dark mode. The layout framework should also be defined in advance. If the website isn’t particularly personalized, the positions of several functional modules usually won’t change. After defining the two parts—colors and layout—development can also begin in parallel.
### Frontend and Backend Development
For the development part, I’ll mainly introduce frontend development, since I don’t know much about backend development.
#### Frontend Environment Setup
Taking Mac as an example, frontend development requires the following tools:
- Code editor: Visual Studio Code (VS Code): software used to write and manage code
- Runtime environment: Node.js: a platform that allows JavaScript to run on your computer
- Version control system: Git: a tool used to track and manage code changes
- Package manager: Homebrew (optional): a tool that simplifies the software installation process on Mac
The basic process is to first install a software package marketplace, then install development-related software such as Node.js, Git, and VS Code through that marketplace. Once installation is complete, you can write code in VS Code and use Node.js to build your blog. Then you can use Git to record the change history of your code, making it easier to manage.
Run the following commands in the macOS terminal to configure the frontend environment you need:
```zsh
# 安装 macOS 软件包管理:brew
/bin/bash -c "$(curl -fsSL https://raw.githubusercontent.com/Homebrew/install/HEAD/install.sh)"
# 通过 brew 安装 VS Code、git
brew install --cask visual-studio-code
brew install git
# 安装 node 管理工具:nvm
curl -o- https://raw.githubusercontent.com/nvm-sh/nvm/v0.40.1/install.sh | bash
# 通过 nvm 安装长期支持的 node 版本
nvm install --lts
# (可选)安装 pnpm 软件包管理器
npm install -g pnpm
```
The required frontend environment is now configured. If you need to install anything extra, you can also do so through the `brew` software marketplace. Network issues need to be resolved on your own.
#### Frontend Technology Selection
The frontend environment is the foundation for developing all frontend projects. Now we need to consider the technology choices for this project.
As we discussed earlier, the “content framework” has an important impact on technology selection. To help you make a better choice, I’ve put together a “technology selection” recommendation table based on content characteristics (static/dynamic).

I have used [Hugo](https://gohugo.io/), [Next.js](https://nextjs.org/), and [Astro](https://astro.build/) from the table, while [Nuxt](https://nuxt.com/) is a strong Vue-based competitor to Next.js. My blog has also gone through changes from Hugo -> Next.js -> Astro, so I suppose that gives me at least a little credibility.
Among these frameworks, [Astro](https://astro.build/) is the one I currently recommend most. The specific reasons are as follows:
1. Websites built with Astro have excellent performance and load fast enough
2. Astro natively supports Markdown, making it very suitable as a blog framework
3. Astro has a relatively gentle learning curve and only requires familiarity with HTML, CSS, and JavaScript
4. Static builds make it convenient for me to quickly deploy to different platforms later
5. The server I purchased has relatively weak performance, and pure static sites have low server requirements
6. Static content is also very suitable for CDN acceleration
You can also check the [2023 Web Framework Performance Report](https://astro.build/blog/2023-web-framework-performance-report/), which compares the performance of web frameworks such as Astro and Next.js. It may help you make a choice.
After the environment is configured, taking an Astro project as an example, we can follow the [Astro documentation](https://docs.astro.build/en/install-and-setup/) to create a new Astro-based project:
```zsh
# 如果没有安装 pnpm,npm 请使用 npm create astro@latest
pnpm create astro@latest
```
Next, you can find some tutorials and learn step by step how to write code based on Astro. It’s not very difficult to get started.
After the project initialization is complete, you may wonder how to connect it with the specifications on the design side. What I’m using is [Tailwindcss - A utility-first CSS framework for rapid UI development](https://github.com/tailwindlabs/tailwindcss). It’s like a plugin for the project that can help you with frontend development. In Tailwindcss, you can predefine fonts, theme colors, functional colors, and even spacing, border radius, and so on. At this point, doesn’t it work perfectly with the color and other specifications you defined during design? Configure it once, and it becomes very convenient to use and adjust uniformly.
```zsh
# 如果没安装 pnpm,npm 请使用 npx astro add tailwind
pnpm astro add tailwind
```
Tailwindcss configuration example:
```js title="tailwind.config.js"
/** @type {import('tailwindcss').Config} */
module.exports = {
darkMode: ['selector'], // 暗黑模式支持
theme: {
colors: {
white: '#ffffff', // 定义颜色名称 调用方式:text-white bg-white
black: '#000000',
brand: {
500: '#0ea5e9', // 定义品牌色 调用方式一致:text-brand-500
600: '#0284c7',
},
},
},
};
```
#### Backend Development
Earlier, we chose Astro as the technology stack, which is more suitable for developing static content. If your blog needs a lot of dynamic data and requires a simple backend, then I recommend using [Next.js](https://nextjs.org/) or [Nuxt](https://nuxt.com/).
Basic process:
1. Have a database (I recommend Supabase’s free plan or a database from a domestic cloud provider) to store your data
2. Connect it to your Next.js project through the plugin [Prisma](https://www.prisma.io/)
3. Write logic code in the project to operate on the data in the database
Here is an example of an API for querying my “recent updates”:
```ts title="api/route.ts"
export async function GET(req: NextRequest) {
// Get 方法
const number = Number(req.nextUrl.searchParams.get('number')); // 让程序知道你想要几条数据
const records = await prisma.recent_states.findMany({
take: number, // 程序知道之后,去数据库对应数量的数据
orderBy: { created_at: 'desc' }, // 排序方法 按照时间降序
});
return Response.json(records); // 返回 json 格式的数据 方便返回到页面中
}
```
By calling this API using the `Get` method, I can query my recent updates and then display them on the blog, allowing you to see and understand what has been happening with me recently.
Compared with static content, there are more operations involved. This adds the process of querying and processing data from the database. If database access is slow, or your cloud server performance is poor, this will directly affect your website’s access speed. Also, dynamic content is not suitable for deployment through traditional CDN distribution. If your website’s access speed is poor, you should give up dynamic content.
### Deployment and Launch
After the blog has been developed and tested locally, I recommend uploading it to [Github](https://github.com/). Github is used for online project hosting with Git. This platform is like a version management tool for files, and it can manage the code of your project.

Every time you modify a piece of code, you can commit it to Github. If the project code build has problems at some point, you can roll it back very conveniently.
After the blog is developed, what we mainly want is for others to see it. So we need a place to host the website, and that place also needs to be accessible by everyone. For example: home devices with a public IP, cloud servers, lightweight application servers, PaaS platforms, and so on.
A laptop at home can actually be used as a device to host a website, provided that you have a public IP and others can access you on the Internet. Currently, public IPs need to be requested from customer service. If you use your laptop as a server, your device also cannot be shut down, and so on. There are still some limitations.

So at present, most people mainly deploy websites on cloud servers or lightweight application servers. These all have public IPs and run 24 hours a day, making them very suitable as website servers. If you don’t need very strong performance, devices costing around 99 yuan per year are enough. It’s still quite affordable. If you’re still a student, you can get a free server from Alibaba Cloud.
Taking a cloud server as an example, here is a brief introduction to the process:
1. A Linux server, like a macOS system, needs to have the frontend environment installed and configured before building
2. If the files are not very large, you can also build locally and then upload the `dist` package to the server
3. Configure nginx forwarding, and you can access your website through the cloud server’s IP address
4. If you don’t want to access it directly through an IP address, you can also purchase your own dedicated domain name. Several major domestic cloud provider platforms allow you to purchase domain names
5. After purchasing a domain name, you need to configure DNS resolution. You can handle this step on the platform where you purchased the domain name or on a dedicated DNS resolution platform, such as [Dnspod](https://www.dnspod.cn/)
6. Bind the IP address of the A record to the domain name, and then you’ll be able to access your website through the domain name
The above introduces a simple process. If you need a detailed deployment and launch process, you can also refer to Teacher Zuo Zizhen’s article: [A Personal Website Building Guide for Designers (Part 1): From Domain Name to Website](https://zuozizhen.com/blog/website-for-designer-1/)
If you don’t want to use your own server and only want to design and write code, there are actually many platforms that can handle the server and domain name steps for you. After authorization, these platforms pull your project code from your Github repository, then build and publish it to the web on their cloud platforms.
Similar platforms include [Vercel](https://vercel.com/), [Zeabur](https://zeabur.com/), [Cloudflare Page](https://pages.cloudflare.com/), and so on. If you don’t want to maintain your own cloud server, this is also a good approach.

Taking Vercel as an example, here is a brief introduction to the process:
1. Create a Github repository and upload your local project code to a private Github repository via Git.
2. Register and log in to the Vercel platform, grant the platform permission to read your Github repository, and select the corresponding project repository.
3. The project framework is automatically recognized. Click the button to build. The platform will display build logs, so if something goes wrong, you can troubleshoot it in time.
4. Once the build is complete, the platform will provide a free subdomain for you to use. You can directly visit the domain name and see that your website has already been published online.
5. You can also choose to purchase a domain name, then follow the platform’s prompts to bind the project to the domain name you own.
The above provides two ways to deploy a website to the public Internet. You can choose according to your preferences and the level of difficulty. These two methods can also be combined.
### Summary
Due to length limitations, every part of the process has been covered, but not in great detail. You’ll still need to look up more materials on your own. This article can only provide general directional guidance. I hope this introduction to the development process can help you.
## Design & Development Tool Recommendations
As everyone may or may not know, I quite like hoarding things, so when it comes to website development, I’ve also collected quite a few useful tools and resources. I’ll take this opportunity to share them with you; perhaps they can help with your development.
### Design
| Name | Description | Category | Recommendation |
| ------------------------------------------------------------------------ | ----------------------------------------------------- | -------- | -------------- |
| [**Figma**](https://figma.com/) | Collaborative interface design tool | General | ⭐⭐⭐ |
| **Rosure** (retired) | My design collection, including icons, fonts, website inspiration, and more | Inspiration | ⭐⭐⭐ |
| [**Toolfolio**](https://toolfolio.io/) | Design tools and inspiration aggregator | Inspiration | ⭐⭐⭐⭐ |
| [**Tailwind CSS Gradient Color Generator**](https://uicolors.app/create) | Generates color scales based on the color you provide | Color | ⭐⭐⭐ |
| [**Palettte**](https://palettte.app/) | A clear palette editing and remapping tool | Color | ⭐⭐⭐ |
| [**Radix Colors Custom Palette**](https://www.radix-ui.com/colors/custom) | Generates color palettes and allows effect previews, with dark mode support | Color | ⭐⭐⭐ |
| [**Huetone**](https://toolfolio.io/) | A tool for creating accessible color systems | Color | ⭐⭐⭐ |
### Development
| Name | Description | Category | Recommendation |
| ------------------------------------------------------------- | --------------------------------- | -------- | -------------- |
| [**Homebrew**](https://brew.sh/) | macOS (or Linux) package manager | General | ⭐⭐⭐ |
| [**pnpm**](https://pnpm.io/) | Project package manager | General | ⭐⭐⭐ |
| [**nvm**](https://github.com/nvm-sh/nvm) | Node version manager | General | ⭐⭐⭐ |
| [**Tailwindcss**](https://tailwindcss.com/docs/installation) | Utility-first CSS framework | CSS | ⭐⭐⭐⭐ |
---
---
title: "New Paradigms for Visual Interaction in the Age of AI"
description: "Explores new paradigms in visual interaction in the era of artificial intelligence, including innovations in both hardware and software."
canonical_url: https://ro.yikzero.com/en/blog/ai-ui-future/
locale: en
date: 2024-04-24
---
# New Paradigms for Visual Interaction in the Age of AI
## Preface
I’ve been thinking about what form these “tools” that we take for granted will take in the age of artificial intelligence.
Currently, the most common application of artificial intelligence is usually limited to chat interfaces, where interaction typically follows a text-based question-and-answer model. As technology continues to advance, Vercel has also introduced [Generative UI](https://sdk.vercel.ai/docs/concepts/ai-rsc), which can dynamically generate customized interactive user interfaces based on conversation content and needs. What form will future UI take? Will it evolve into what is shown in movies, with cool holographic displays and intuitive interactive HUDs, or might we enter a new era that no longer relies on traditional GUIs?
> Natural language becoming the fundamental interface for every software application might mean the end of GUIs
## Random Thoughts
In the future, could I simply say, “Siri, book me a plane ticket,” or, just like Musk’s brain-computer interface experiments, transmit information with only a thought? The information that needs to be presented would appear directly in front of the eyes (in that case, would blind people also be able to see?), without the need for any external devices. The content that needs to be controlled could also be interacted with through fingers and eye movements, like with VR glasses. Perhaps in the future, it really will be like [Black Mirror](https://www.themoviedb.org/tv/42009-black-mirror).
## Research
### AI Pin
Humane’s Ai Pin (official site now unavailable) can be considered a pioneer. This product attaches magnetically to clothing. It has no screen and is controlled through voice and a small touch surface. It has a laser that can project images onto your palm, as well as a camera that can recognize gestures for switching and other operations.
Features it currently and may potentially support in the future: laser projection display, gesture and voice interaction, AI assistant, real-time translation, health monitoring, music playback, message notifications, and more.

### Rabbit
[Rabbit R1](https://www.rabbit.tech/rabbit-r1) is an AI device launched by Rabbit, positioned as your pocket companion. It mainly consists of a screen, camera, scroll wheel, and button.
Features it currently and may potentially support in the future: understanding and executing actions (hailing rides, ordering food, playing music), real-time translation, teaching mode, etc. You can watch the [review video](https://www.youtube.com/watch?v=ddTV12hErTc).

### Dot
[Dot](https://new.computer/) is a chat app on iOS. Users can use it to send text, voice memos, images, PDF files, and it can also search the web for you. Currently, Dot communicates through text and aims to become an always-available companion. Unlike most AI conversations, Dot can remember what you’ve said before and almost never forgets anything.

### Amazon Lex
[Amazon Lex V2](https://docs.aws.amazon.com/lexv2/latest/dg/what-is.html) is a service provided by AWS that allows developers to build conversational interfaces for applications, supporting voice and text input. Users can interact using natural language, such as placing orders. In addition, Lex V2 can also be integrated with web elements (buttons, select boxes, etc.) to solve users’ problems or help them complete specific tasks through Semi-Guided Conversations.
### Summary
These examples may not necessarily be representative, but they do provide a simple glimpse of the overall trend:
- The hardware carrier has changed. In addition to phones and computers, people are also trying to present content on more portable devices, such as necklaces, badges, and pagers.
- The ways in which visual images are presented are becoming more diverse, such as projection and laser displays. Due to size constraints, the main forms are primarily text, simple charts, and button information.
- Natural language interaction will be used more and more widely.
## My Thoughts
#### **Generative UI Is a Future Trend**
At present, interface design must satisfy as many people as possible. Any experienced professional designer knows the main drawback of this approach — you can never make anyone completely satisfied. Personalization and customization also play a relatively small role.
This application scenario is somewhat similar to Alipay’s dynamic personalized cards on the home screen based on location (showing airport-related information when at the airport).
[Video](https://cdn.yikzero.com/markdown/images/2024042305.mp4)

Moreover, generative UI is not limited to dynamic cards; it can also dynamically present an entire system for you based on personal data. The article [Generative UI and Outcome-Oriented Design](https://www.nngroup.com/articles/generative-ui/) gives examples of what true personalization for every individual looks like:
- Dyslexia — the application displays special fonts and color contrast
- Users who care about cost and time — explicitly display this information and automatically increase the weight of corresponding flights
- Although it is the same application, the interface, features, and more are all personally customized

Designers will also shift from universal design to personalized design, defining boundaries for various personalized scenarios to strengthen constraints on artificial intelligence.
#### **Traditional Interaction Will Not Be Replaced, but It Will Be Greatly Simplified**
Although natural language interaction has advantages, in scenarios that require fast and precise input, visual elements such as buttons, icons, and gestures are still necessary. Pure voice input may reduce efficiency. Also, not all tasks can be completed well through voice conversations alone.
Different interaction methods suit different situations. The coexistence of visual and voice input/output can maximize adherence to accessibility design principles, allowing people with disabilities to choose the method that suits them. Once LLMs can complete specific tasks, interfaces will be greatly simplified.
In addition, natural language interaction is not applicable in all scenarios. For example, in companies, libraries, and similar places, it may also cause concerns such as privacy leakage.
## Final Notes
Although I wanted to expand on this as much as possible, as I kept writing, I still ended up returning to the GUI itself — I was merely imagining the future forms of existing products...
## References
- [ScreenAI: A visual language model for UI and visually-situated language understanding](https://research.google/blog/screenai-a-visual-language-model-for-ui-and-visually-situated-language-understanding/)
- [The AI Device Revolution Isn’t Going to Kill the Smartphone](https://www.bloomberg.com/news/newsletters/2024-04-14/humane-ai-pin-review-the-device-isn-t-going-to-kill-apple-s-iphone-luziqlew)
- [Meet Dot, an AI companion designed by an Apple alum, here to help you live your best life](https://www.fastcompany.com/90975882/meet-dot-an-ai-companion-designed-by-an-apple-alum-here-to-help-you-live-your-best-life)
- [Malleable software in the age of LLMs](https://www.geoffreylitt.com/2023/03/25/llm-end-user-programming.html)
- [Generative UI and Outcome-Oriented Design](https://www.nngroup.com/articles/generative-ui/)
- [UFO: A UI-Focused Agent for Windows OS Interaction](https://arxiv.org/abs/2402.07939)
- [Ferret-UI: Grounded Mobile UI Understanding with Multimodal LLMs](https://arxiv.org/abs/2404.05719)
---
---
title: "A Study of Modular UI Design: Icons"
description: "A comprehensive introduction to the importance and application of icons in UI design"
canonical_url: https://ro.yikzero.com/en/blog/icon-learn/
locale: en
date: 2023-11-11
updated: 2024-01-11
---
# A Study of Modular UI Design: Icons
## Background
There are already many high-quality icon libraries, such as [Untitled](https://www.untitledui.com/icons), [Lucide](https://lucide.dev/icons/), and [Remix](https://remixicon.com/). For more comprehensive options, you can also refer to [React Icons](https://react-icons.github.io/react-icons) and [Iconfont](https://www.iconfont.cn/).
Although there are so many existing icon libraries, if all you can do is choose icons based on their meanings... even someone who is not a designer can do that.
We cannot “know what something is but not know why it is so.” So let’s start with icons and understand the theory behind design.
## Overview
In the field of UI design, icons play a central role. They transform textual information into visual symbols, simplify users’ understanding of content, and enhance the aesthetics of the interface. Especially in B-end design, although icons are not used as frequently or as complexly as in C-end design, in form-oriented page layouts, appropriate and suitable icon design can highlight the style and brand tone of a product or even the entire enterprise.
The earliest form of visual communication was basically carried out through graphics. This is a prehistoric cave mural by North American Indians. Although murals are often said to be the predecessor of writing, I personally feel they are also very similar to icons. Icons are more like a universal language, crossing various languages such as Simplified Chinese, English, and Korean.
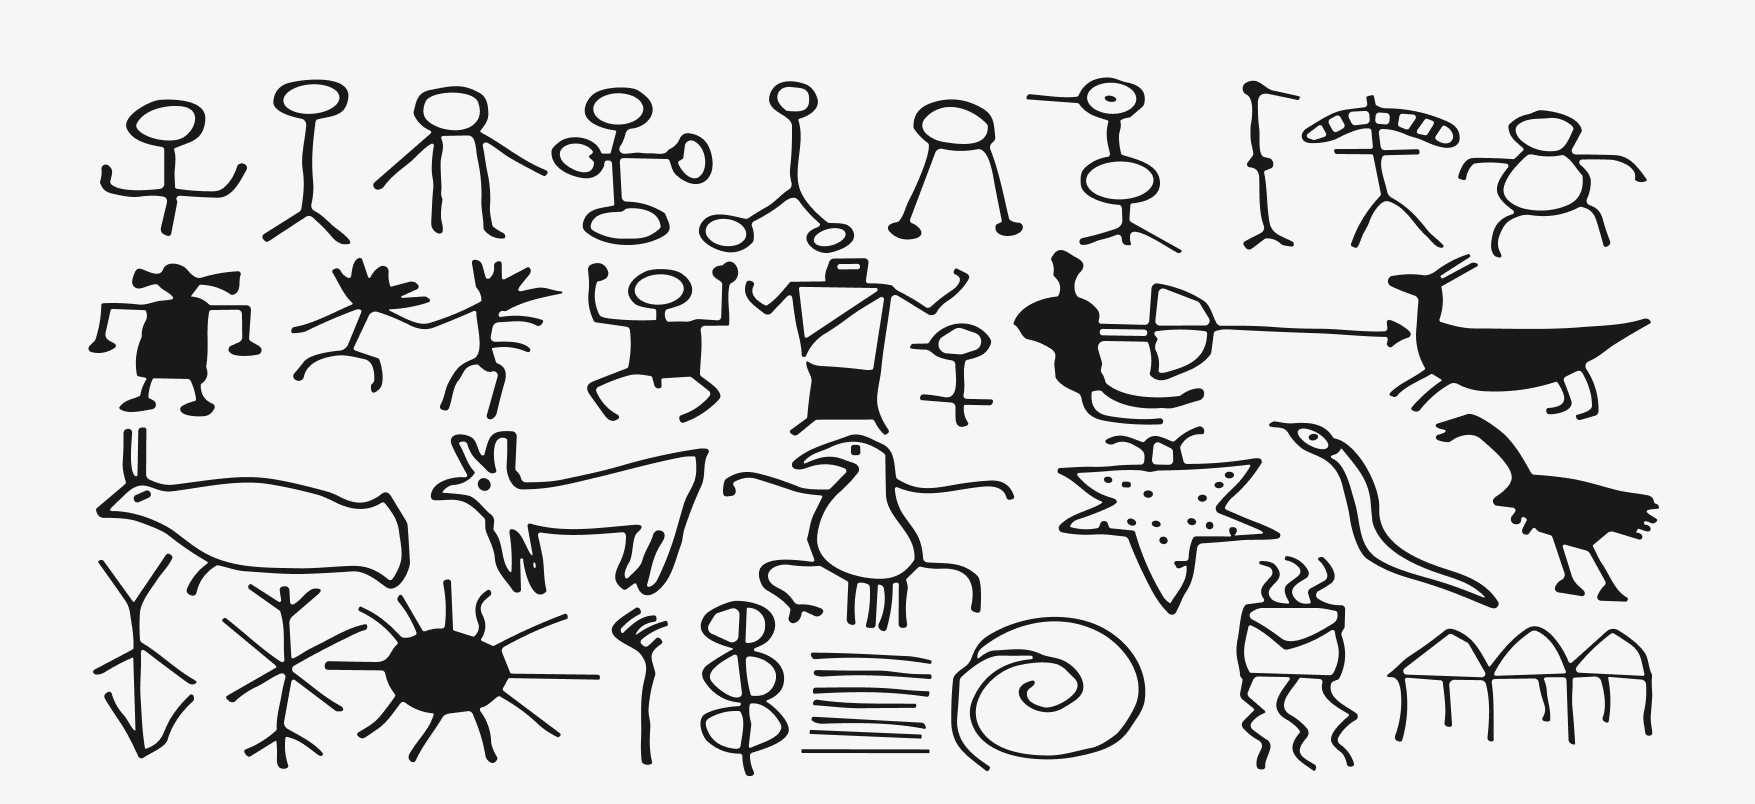
## The Ins and Outs of Icons
First of all, an icon should clearly represent an object, operation, or idea. If users cannot see/understand its meaning, the icon becomes a flashy but impractical decoration, and may even hinder task completion.
### Icon Size
In fact, when using various component libraries, I discovered that the icons in these libraries are all based on a `24px` size.

After searching through online materials, I found several possible reasons:
- The 24px size ensures that icons remain clear and readable across various screen resolutions and devices.
- The 24px size adapts to multiple grid systems (such as the [8-Point Grid System](https://medium.com/built-to-adapt/intro-to-the-8-point-grid-system-d2573cde8632#.5h95d066j)), making it easier for designers and developers to collaborate.
- 24dp\*24dp @x1 is the “perfect size” for icons recommended by the [Material Design 3](https://m3.material.io/styles/icons/applying-icons#661945dc-8621-41c6-b88d-bdb7c945b4e7) specification. At the same time, Material Design recommends a minimum touch target area of 48dp.
I have not yet found supporting data behind this, so I will apply it based on convention:
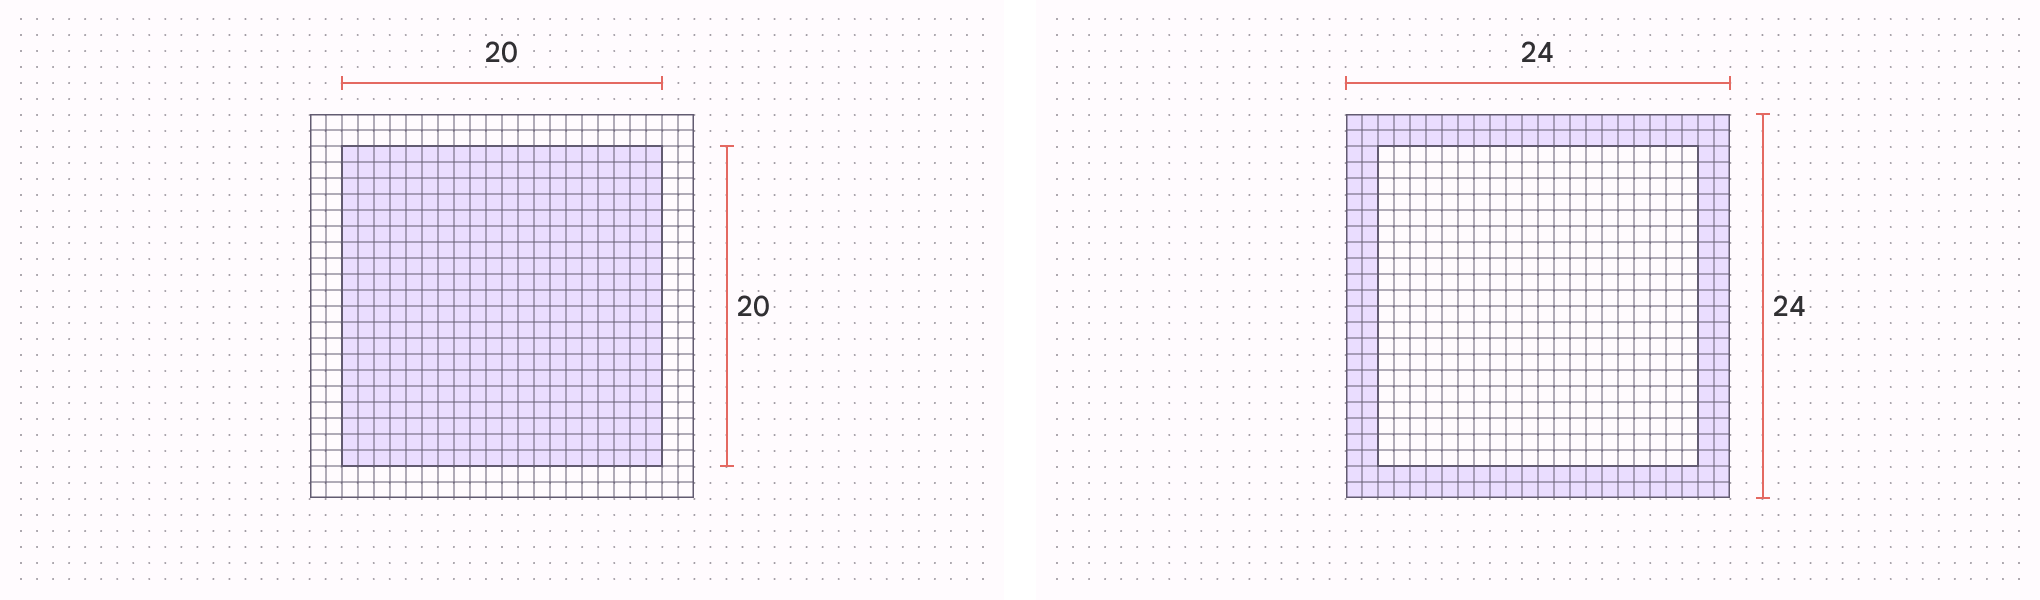
- The recommended standard icon size is 24px\*24px, usually with 2px of padding around it, but this is not absolute; the specific margin should be judged based on the Keyline. The corresponding recommended touch target size is 48px\*48px.
- In desktop environments, the icon size can be adjusted to 20px\*20px, with a recommended corresponding touch target area of 40px\*40px.
- 16px is usually used as the minimum size. At this size, icons should be designed to be more concise, and their decorative role will be greater than their functional role.
“Rules are rigid, but people are flexible.” We can apply this guideline while also taking actual circumstances into account.
px, dp, and pt are not equal; they each have their own conversion relationships. You can search online for specific information.
### Icon Styles
Existing icon styles are varied and complex, and have long since gone beyond just linear and filled styles. Icons on the C-end are even more diverse. Here, we will temporarily analyze them based on basic styles.
Below are the icon styles of Untitled Icons that I found: Line, Duocolor, Duotone, and Solid.

The four icon styles above can basically meet all the needs of B-end design.
If divided in a more detailed way, Material Design further divides “linear icons” into: OutLine, Rounded, and Sharp.

Combined with the stroke thickness and radius size of linear icons, this is basically enough to meet the customization needs for a company’s and product’s character.
In addition, the style of an icon not only affects the overall interface style, but also affects the functionality and user experience of the icon:
- Complex icons are not suitable for overly small sizes (16px \* 16px icons need a more concise linear style)
- Filled icons are generally easier to recognize than linear icons, but the specifics need to be judged based on the icon shape [source of conclusion](https://cdr.lib.unc.edu/concern/masters_papers/6w924g35w)
## Icon Design
First of all, I want to say that I have never completely independently designed an icon. In the past, if there was no icon that met the requirements, I would basically take an icon with a similar meaning and then simply adjust its shape.
So, taking this opportunity, I can also get some exposure to icon design. Ant Design’s [icon design guidelines](https://ant.design/docs/spec/icon-cn) have actually already covered a lot of related content, and I recommend learning about them first.
### Using Keyline
Keyline is the foundation of the grid. By using these core shapes as guides, we can maintain consistent visual proportions among system icons.
The image below is a Keyline grid drawn according to the specifications of the [Material Design 3 Icon design template](https://m3.material.io/styles/icons/designing-icons#8754553f-29d9-4671-b163-123b8e7b8f1e). Based on this grid, you can basically draw all kinds of icons.


In today’s world where design resources are everywhere, you can absolutely find icons on [iconfont](https://www.iconfont.cn/) whose style meets your needs. Then, based on the product’s style, simply redraw them. There are very few cases where a designer truly needs to create something completely from scratch.
I also tried applying Keyline to draw several basic icons: home, card, lock, and file. These are also the four basic shapes on the Keyline.

During my own hands-on practice, I discovered a few small tips for icon design:
- Try to use Boolean operations with “basic shapes” to construct icons.
- Keyline provides numerical balance, but numerical equality does not equal visual balance (for example: a play icon).
- When choosing a stroke alignment method, icon design mostly uses center alignment (Center) or inside alignment (Inside). Center-aligned icons will look larger under the same conditions.
- In Figma, using `Shift + Backspace` to delete points and making use of the pen tool’s center point feature can greatly improve the efficiency of icon design.
- After icon design is complete, you can apply Flatten to integrate the icon lines together, making unified processing easier. There is no need to turn strokes into fills, because this is not conducive to later adjustment of line thickness.
## Icon Application
After icon design is complete, the next step is to consider how to effectively present these icons to the audience. As the saying goes, “even an ugly daughter-in-law eventually has to meet her parents-in-law,” which means that no matter what the design result is, there needs to be a process of presentation and feedback. This is not only to showcase the results, but also to obtain feedback, improve, and optimize the design.
### Image Method
The most traditional display method is naturally images. Designers export icons in @1x and @2x according to states such as default, hover, pressed, active, and disabled, package them into a compressed file, and send it to the front-end developer. Or the designer exports the images and uploads them to Lanhu, and the front-end developer downloads the icons they need from “Lanhu” by themselves.
If the front end needs icons in image format, I usually compress the icons through [TinyPNG](https://tinypng.com/) to make the icons occupy as little space as possible while ensuring their clarity. My most commonly used tool is [TinyPNG4Mac](https://github.com/kyleduo/TinyPNG4Mac), which is quite convenient. Some front-end scaffolding tools also come with image compression features, and images occupying less than a certain value will also be converted into Base64 encoding for storage.

Tracing back to earlier technologies, we encounter “sprites,” which is a practice of integrating multiple icons into a single image with a transparent background. Designers place all icons on one image, and then the front end displays them on the web page based on each icon’s position and size. The advantage of this method is that it reduces the number of web requests. In fact, some websites today, when creating dynamic images, also often use a method similar to “sprites,” creating animation effects through continuous static frames.
Images in JPG / PNG format are the safest display method. All browsers support them. Although they are bitmap formats and are not clear enough after being enlarged, image formats can basically solve most website needs, and the solutions are mature enough.
Existing CDN service providers and/or some frameworks, such as Next.js, can intelligently identify whether a browser supports WEBP or AVIF formats. These two image formats can provide higher compression rates while maintaining higher clarity.
### Font Method
As mentioned earlier, icons need to be exported by designers separately according to various states and then provided to developers. If the overall color scheme of the official website is adjusted, and all icons need to be re-exported, this might be a disaster.
Perhaps because of this or other reasons, the icon font solution appeared. The most commonly used icon font platform in China is iconfont. This requires designers to outline the icons and then upload them to iconfont. The front end can then reference icons by icon name and conveniently adjust their color and size.

Until the time I wrote this article, font icons were still quite widely used. They are convenient to call and take up less space. However, the following main shortcomings affect the use of font icons:
- Icons need to be processed one by one by designers. For some icons, outlining alone is not enough; you also need to use the Figma [Fill Rule Editor](https://www.figma.com/community/plugin/771155994770327940/fill-rule-editor) plugin to adjust the icon fill mode to “Non-zero rule” so that it can display normally in iconfont. For the specific solution, you can [refer to](https://zhuanlan.zhihu.com/p/137298478)
- If an icon disappears when adjusting the fill style through Fill Rule Editor, you can try copying the icon as-is into illustrator / Sketch, and then copying it back to solve the problem. (kidding)
- Font icons do not support multicolor icons well enough, and the degree of customization is not high enough.
- Font icons may also fail to render properly and require special handling (I once naively thought it was a problem with my browser).
I can only evaluate font-style icons from a designer’s perspective, because I have never used this method during development. Recommended article: [Icon Fonts vs SVG Icons: What Works Best for You?](https://getdevdone.com/blog/icon-fonts-vs-svg-icons.html), which compares the pros and cons of fonts and SVG in relatively great detail.
### SVG Method
SVG icons not only inherit the main advantages of font icons, but also solve some limitations of font icons. Their main advantages include:
- Support for each icon having multiple colors, including gradients.
- Support for more complex graphics and shapes, without being limited to the basic shapes of fonts.
- Support for direct embedding in HTML code, making it convenient to edit and control icons.
- Support for CSS and JavaScript animations
iconfont also does not only support the font icon method. The official platform also supported referencing SVG icons through the symbol method several years ago.
We can briefly understand SVG through an example. The following is a “home” icon in SVG format exported from Figma, and its code is as follows:
```html
```
This SVG contains several key attributes:
- **path:** The path element defines the outline of the graphic, describing points on the path through a series of commands and parameters to form the graphic. In this example, these commands and parameters together form the shape of a house.
- **fill:** The fill attribute is used to set the internal color of the graphic. It can be a hexadecimal color code (for example, #FF0000), or a common color name (for example, `black`). none means there is no fill, while currentColor uses the value of the color attribute of the element or its parent element.
- **stroke:** The stroke attribute is used to define the color of the graphic outline, and it is used in a way similar to fill.
- **stroke-width:** The stroke-width attribute specifies the width of the stroke.
If an SVG contains multiple paths, there will be multiple path elements. Each path can have independent fill and stroke attributes to control its own fill and stroke styles. If a certain part of the graphic does not need a stroke, its stroke attribute can be set to none.

As shown in the image above, what we see is a preview of an icon and its corresponding code. If you look closely, you will notice that the code does not specify the icon’s width, height, fill color, or stroke color.
This approach is intended to provide SVG icon code that is as concise as possible, containing only core information such as the icon paths. The purpose of this design is to allow frontend developers to control the color and size of icons more flexibly. For example, if the SVG icon code includes a `fill` attribute by default, frontend developers may find that they cannot change its color when applying these icons. To solve this problem, one approach is to remove the `fill` attribute or set `fill` to `currentColor`, and then define the color through CSS. Another approach is to specify the desired color directly in the `fill` attribute.
It is not recommended to use hacky methods such as filters to adjust colors, because this approach can be both complex and imprecise.
Similarly, SVG icons support compression, and tools such as [SVGO](https://github.com/svg/svgo) can be used to clean up redundant parts of the SVG code.
For frontend practices when using SVGs, you can refer to the examples below, which use Tailwindcss and Lucide Icons:
**Direct Usage Example**
This code example demonstrates how to use simple classes to control an icon’s size, color, and display effect in dark mode. The operation is very intuitive and convenient:
```tsx
```
**Package Usage Example**
The following example shows how to apply icons through a package. This method is also simple: you only need to import the required icons and set the styles:
```tsx
import { Home } from 'lucide-react';
const App = () => {
return (
);
};
export default App;
```
To deliver design icons to the development team, you can choose iconfont or use the [figma-icon-automation](https://github.com/leadream/figma-icon-automation) plugin to package the icons as an npm library, making it convenient for the development team to use them via an installed package. This method only needs to be configured once and is highly efficient.
Although the way SVG icons are used involves code, this section is still written for designers. The purpose is simply to tell everyone that SVGs do not have issues with being difficult to adjust in color, nor are they difficult to use. Actively encourage developers to follow up~
## Conclusion
Behind this tiny icon lies rich and complex content, and this article is merely an initial exploration of this vast topic. As a beginner, mistakes in my article are inevitable, and I sincerely welcome readers to offer valuable feedback and corrections.
## References
- [Material Design 3](https://m3.material.io/)
- [Icon Fonts vs SVG Icons: What Works Best for You?](https://getdevdone.com/blog/icon-fonts-vs-svg-icons.html)
- [Design Icons from Scratch](https://blog.yarsalabs.com/guide-to-design-icons/)
- [Intro to The 8-Point Grid System](https://medium.com/built-to-adapt/intro-to-the-8-point-grid-system-d2573cde8632#.5h95d066j)
- [Apple - Human Interface Guidelines](https://developer.apple.com/design/human-interface-guidelines)
- [Ant Design 5](https://ant.design/index-cn/)
- [Lucide Icons](https://lucide.dev/)
- [Remix Icons](https://remixicon.com/)
---
---
title: "Notes on Calling the Notion API with Next.js"
description: "Development notes on building a blog with Next.js and the Notion API, covering lessons learned from data fetching, image optimization, style rendering, and more."
canonical_url: https://ro.yikzero.com/en/blog/brogbuild-1/
locale: en
date: 2023-10-04
---
# Notes on Calling the Notion API with Next.js
## Pitfall Collection
The pitfalls come partly from Next.js and partly from the Notion API. Of course, I myself am the biggest pitfall.
1. Next.js server-side rendering
2. Notion API data filtering
3. Notion Block data rendering
4. Notion temporary image expiration
5. Using the Next.js Image component
6. Rendering styles for Notion article pages
The above is basically all the pitfalls I ran into. Before introducing my experience dealing with them, let me briefly talk about the original intention of the project.
## Original Intention
At first, it was because I had learned frontend development and then wanted to understand backend development. Initially, I made a full-stack text-to-speech project based on edge-tts called Rotts (frontend React + backend Flask). But this project was very simple: the backend basically just requested the API, obtained the voice list, then passed information such as voice, pitch, and text to edge-tts, waited for the audio to return, and then played/downloaded it. I felt like the backend part was over before I had really experienced much of it.
So I wanted to find another project to continue learning backend development. The first thing that came to mind was Node.js. During my research, I saw many people recommending Next.js, which is also based on Node.js. So it clicked immediately. I also wanted to simply reinvent the wheel and build a blog system that uses Notion as a CMS. Visually, everything would be kept simple to reduce burden, with a focus on content rendering.
Originally, I thought that with ChatGPT, I could just ask it whenever I didn’t know something. As it turned out, the Next.js App Router was too new, and it wasn’t even in its knowledge base. Every time I asked it related questions, the answers were not accurate enough.
## Project Information
- Name: **Brog**
- Introduction: A minimalist blog system built with Next.js, using Notion as the CMS
- Tech stack: React + Next.js + Typescript + TailwindCSS
- Github: [https://github.com/yikZero/Brog](https://github.com/yikZero/Brog)
## Next.js Pitfalls
### Duplicate Requests
Actually, when I first started fetching data, I had doubts. I fetch here, then fetch there. It’s all the same data—wouldn’t that cause multiple requests and be very wasteful?
Because of this, I kept trying to separate function logic from requests and just pass several props around... But in fact, at least in React, you don’t need to worry about this.
> Passing data between a parent layout and its children is not possible. However, you can fetch the same data in a route more than once, and React will automatically dedupe the requests without affecting performance.
If the link and parameters you fetch remain unchanged, then even if you make multiple requests, React will help merge them into a single request. So there’s no need to keep forwarding props between components. Just request the same data multiple times; it’s not a problem. React will merge the requests on its own and won’t repeatedly make duplicate requests that affect the network.
### Server Components
What counts as a server component? Anything placed under the `app/` directory should belong to server components. When I wasn’t sure whether something was a server component, I threw all the `components` and `lib` directories I used into `app/`... just for server components.
If you want it to become a client component, add `use client` at the top, and it will be recognized as a client component. The official Next.js recommendation is to use server components whenever possible.
### next/image Usage
Because of [LCP performance](https://almanac.httparchive.org/en/2022/performance#lcp-image-optimization), Next.js officially optimizes the usage of the img element and recommends using the official Image component.
For specific usage, refer to [Image Optimization](https://nextjs.org/docs/app/building-your-application/optimizing/images)
I thought it would be simple—just replace the name. But it requires me to provide explicit height and width. For images I fetch dynamically, how would I know the image height and width? So I used a bit of a workaround... also a solution from [stackoverflow](https://stackoverflow.com/questions/65169431/how-to-set-the-next-image-component-to-100-height).
```html
```
## Notion-Client Pitfalls

### Data Fetching
Notion officially provides [@notionhq/client](https://www.npmjs.com/package/@notionhq/client), and react-notion-x also has a [notion-client](https://www.npmjs.com/package/notion-client). I learned about notion-client first, so after finishing the styles, I tried integrating the third-party implementation.
How should I put it? notion-client is also quite good. By providing a public `NOTION_PAGE_ID` environment variable, you can fetch the data. But what you get is the full dataset, and there is no way to filter by field name like with the official API, so organizing the data becomes much more troublesome. For a beginner like me, this was way too much trouble... After all, the data obtained from Notion is nested layer by layer, and every block has its own ID, which made me completely dizzy.
In the end, I still referred to the official API usage in [notion-blog-nextjs](https://github.com/samuelkraft/notion-blog-nextjs) to obtain the corresponding data.
### Image Expiration
The image links in the data officially provided by Notion are temporary Amazon links, which expire after one hour. This causes the images to break.
**Vercel Cron:** Many people also choose to use the Vercel cron feature to rebuild and render every hour. But I think this wastes too many resources and is too environmentally unfriendly (:
**Converting temporary addresses into permanent addresses:** For this solution, you can refer to [fix: solve linked img crash #524](https://github.com/tangly1024/NotionNext/pull/524/files)
**Uploading to Upyun via PicGo:** Because I have migrated data before, if all Markdown images use relative paths, it is simply a disaster. So now I choose to upload them to Upyun via PicGo and return my CDN address. If I need to migrate, at least the images won’t be lost.
---
---
title: "HomeLab Environment Setup"
description: "Documenting the configuration of the optical modem, R4S software router, and Linksys hardware router"
canonical_url: https://ro.yikzero.com/en/blog/homelab-config/
locale: en
date: 2023-09-12
---
# HomeLab Environment Setup
## Background and Purpose
Home network configuration typically involves an optical modem as the entry point for the ISP connection, an R4S soft router (NanoPi R4S based on OpenWrt), and a Linksys hardware router for managing the internal network. The goal of this article is to optimize network performance through bridge mode, reduce NAT conflicts, and use the R4S and Linksys to achieve efficient network management and wireless coverage.
## Topology Diagram

The optical modem in bridge mode connects to the R4S WAN port. The R4S serves as the main router and handles PPPoE. The Linksys connects its WAN port to the R4S LAN port and is set to bridge mode as a wireless access point.
## Optical Modem Bridge Configuration
### Reasons for Bridging
- Prevent duplicate NAT forwarding and avoid double NAT issues that affect certain applications.
- Reduce the network load on the optical modem; the optical modem is only responsible for optical/electrical signal conversion and does not perform routing.
- The optical modem has limited functionality; after bridging, the R4S or Linksys can provide more powerful routing functions.
- The optical modem’s WiFi signal is weak; after bridging, Linksys can provide better wireless coverage.
### Specific Configuration Steps
#### Hangzhou Unicom Optical Modem
- **Login information**:
- Address: `http://192.168.1.1/cu.html`
- Account: `CUAdmin`
- Password: `CUAdmin`
- **PPPoE settings**:
- Account: Usually starts with 0571 (Hangzhou area code); check the backend to obtain it.
- Password: The last six digits of the account.
- **Bridge mode settings**: Find the WAN settings through the login interface, change the mode to bridge, save, and reboot.
#### Hangzhou Mobile Optical Modem
- **Login information**:
- Address: `http://192.168.1.1/`
- Account: `CMCCAdmin`
- Password: `aDm8H%MdA`
- **PPPoE settings**:
- Account: Starts with `hz`, followed by the initial letters of the district (for example, Binjiang District is `hzbj`), then followed by a letter from a-z according to the broadband activation order (for example, the first line is `hzbja`).
- Password: Try `000000`, `888888`, `123456`, the last six digits of the account, or the last six/eight digits of the ID card number.
- **Bridge mode settings**: After logging in, change WAN to bridge mode, save, and reboot.
### Using PPPOE in Bridge Mode
After bridging, the R4S or Linksys needs to dial up using the PPPoE account and password to ensure the Internet connection works properly.
---
## Linksys Bridge Mode
### Initial Configuration
Regardless of whether you later want to change it to “Bridge Mode” or “Automatic Configuration - DHCP”, you first need to perform the initial setup. Follow the “Configuration Wizard” to set the router password normally and configure the WiFi password. Without any additional configuration, and as long as the network cable is fine, you should be able to access the Internet normally.
### Advanced Settings
#### Bridge Mode
1. **Connection**: Connect the R4S LAN port to the Linksys WAN port (Internet port).
2. **Login interface**: Access the Linksys web interface (default 192.168.1.1) and skip the initial setup prompts.
3. **Set bridge mode**:
- Go to `Configuration > Connectivity > WAN Setup`.
- Select `Bridge Mode` to use the router as a wireless access point.
- Select “Obtain an IP address automatically” or manually specify an IP (such as 192.168.31.2, with the default gateway as 192.168.31.1).
- Save and reboot the router.
After setup is complete, click “Save” to reboot the router.
#### Additional Optimizations
- **Wireless Network - Advanced Settings - Roaming Assistant**: Select Off to improve stability.
- **Wireless Network - Advanced Settings - Region**: Select Australia, which may enhance signal strength, but pay attention to compliance; it may not be applicable in all regions.
- **If using Homeassistant**: It is recommended to disable WiFi dual-band merging mode to avoid compatibility issues.
## Summary
This article provides detailed steps for optical modem bridge mode, R4S PPPOE configuration, and Linksys bridge mode to ensure efficient operation of the home network.
---
---
title: "Installing Plex Server on R4S: Notes"
description: "A Complete Record of Installing Plex Media Server on an R4S Software Router, Solving Issues Such as Architecture Compatibility, Remote Access, and Port Forwarding"
canonical_url: https://ro.yikzero.com/en/blog/plex-server-1/
locale: en
date: 2023-03-18
---
# Installing Plex Server on R4S: Notes
## Environment Configuration
- Model: FriendlyElec NanoPi R4S
- Firmware version: OpenWrt R22.3.13 (2022-06-22)
- Architecture: ARMv8 Processor x 6
- Environment: Google Direct
## Preparations
1. Prepare a network that can access Google on your own
1. Install an OpenWrt system with docker
1. Expand the storage card capacity for docker
## Pitfall Notes
### Architecture Issue
Most existing tutorials for setting up Plex with docker are based on the X86 architecture. If you set it up using the docker image from [plexinc/pms-docker](https://hub.docker.com/r/plexinc/pms-docker/), an error will appear in the docker container logs: `stderr: exec /init: exec format error`
This is because the docker container you installed does not match your system architecture.
So I found the ARM-architecture PLEX from [linuxserver/plex](https://hub.docker.com/r/linuxserver/plex) and started the installation:
```shell
docker run \
-d \
--name plex \
-p 32400:32400/tcp \
-p 3005:3005/tcp \
-p 8324:8324/tcp \
-p 32469:32469/tcp \
-p 1901:1900/udp \
-p 32410:32410/udp \
-p 32412:32412/udp \
-p 32413:32413/udp \
-p 32414:32414/udp \
-e TZ=Asia/Shanghai \
-e PLEX_CLAIM=claim-xfczZtmEH5QPvZQc1HsF \
-e ADVERTISE_IP="http://192.168.31.1:32400/" \
-h Zero-R4s \
-v /myplex/plex/database:/config \
-v /myplex/transcode/temp:/transcode \
-v /mnt/sda/Media:/data \
--restart unless-stopped \
lscr.io/linuxserver/plex:latest
```
The specific tutorial can also be found at [linuxserver/plex](https://hub.docker.com/r/linuxserver/plex). Just adjust it according to your own situation.
## PLEX Has No Initial Setup Page
This means that when entering the Plex application interface for the first time, you may encounter a “server not found” issue because remote access has not been enabled. In this case, you can use the following two methods to solve it:
**1. SSH Port Forwarding**
You need to open the PowerShell tool on your local computer, then run the command above to forward the Plex port of the remote server (default is 32400) to a port on your local computer (for example, 8888). After the port forwarding succeeds, you can access `localhost:8888/web` in your local computer’s browser to open the Plex application interface.
**2. Direct Connection**
If remote access has already been allowed on the remote server, you can try directly accessing the remote server’s IP address and Plex port in the browser (for example, http://13.124.4.66:32400/web) to open the Plex application interface.
### Solution
On macOS, you can use the iTerm application to set up SSH port forwarding. The specific steps are as follows:
**1. Connect to the Remote Server**
Enter the following command to connect to the remote server, where username is the username on the remote server, and remote_server_ip is the IP address of the remote server:
`ssh -L 8888:localhost:32400 username@remote_server_ip`
This will forward Plex’s 32400 port on the remote server to port 8888 on the local computer.
**2. Enter the Password on the Remote Server and Verify**
Now, you can open the browser on your local computer and enter `http://localhost:8888/web` to access the Plex interface on the remote server.
### Another Error
```shell
@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@
@ WARNING: REMOTE HOST IDENTIFICATION HAS CHANGED! @
@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@
IT IS POSSIBLE THAT SOMEONE IS DOING SOMETHING NASTY!
Someone could be eavesdropping on you right now (man-in-the-middle attack)!
It is also possible that a host key has just been changed.
The fingerprint for the ED25519 key sent by the remote host is
SHA256:OC9qmnB9nQtFN/OiPH7jGEoKb/zbX4NghGv/glu5dwQ.
Please contact your system administrator.
Add correct host key in /Users/yikzero/.ssh/known_hosts to get rid of this message.
Offending ED25519 key in /Users/yikzero/.ssh/known_hosts:1
Host key for 192.168.31.1 has changed and you have requested strict checking.
Host key verification failed.
```
This error message indicates that the key of the remote server previously connected to has changed. This may be because the server underwent a system update or the administrator changed the server’s key. To protect information security, the SSH client checks and verifies the remote server’s key. If the key has changed, this error message will appear.
Update the remote server key data on the local computer to resolve the issue. The steps are as follows:
1. **Delete the old key:**
Run `ssh-keygen -R ` to delete the old key data on the local computer.
2. **Connect to the remote server:**
Connect using `ssh username@remote_server_ip`.
- The system will prompt “Are you sure you want to continue connecting (yes/no)?”. Enter yes and press Enter.
- Enter the remote server password to verify.
- After connecting, run the command again to set up SSH port forwarding.
After completion, you can access the PLEX server.
---
---
title: "Hugo Setup Notes: From Zero to One"
description: "The Complete Process of Building a Hugo Blog from Scratch, Covering Installation and Configuration, Page Structure, and CSS Layout Tips"
canonical_url: https://ro.yikzero.com/en/blog/hugo-build-1/
locale: en
date: 2022-03-23
---
# Hugo Setup Notes: From Zero to One
## Hugo Installation
### Official Documentation Tutorial
The official website provides detailed installation tutorials for different systems: https://gohugo.io/installation/
### Brew
If you are a Mac user, you can use the `brew` command to install it.
```bash
brew install hugo
```
**Note:** This installation method may not install the latest version of hugo. If you want to use the latest version of hugo, please install it in another way.
## Configuration File Format
As a beginner, which configuration file format to choose—yaml, toml, or json—became my first question.
**TOML**
1. Case-sensitive
2. Files can only contain UTF-8 encoded Unicode characters
3. Not sensitive to indentation
**YAML**
1. The file starts with ' - ', marking the beginning of the document
2. Key-value pairs are separated by colons
3. Lists start with hyphens
4. Uses indentation with one or more spaces to describe nested collections
**JSON**
1. Data is stored in name/value pairs
2. Records are separated by commas. Trailing commas without following properties are not allowed
3. Property names and strings are wrapped in double quotation marks
4. Single quotation marks are not allowed
### String Differences
Strings are supported in any format, but JSON does not support multiline strings and also does not support comments.
```toml
# TOML
key = "String Value"
multiline = """\
The quick brown \
fox jumps over \
the lazy dog.\
"""
```
```yaml
# YAML
key : String Value
multilinePreservedLinebreaks:
|
L1 - The quick brown
L2 - fox jumps over
L3 - the lazy dog.
multilineReplaceLinebreaksWithWhitespace:
>
This sentence ist just too long to keep it
on the same line.
```
```json
// JSON
{
"key": "String Value"
}
```
Because of the relatively troublesome comment syntax of `JSON` and the strict indentation requirements of `YAML`, I ultimately chose `TOML` as the configuration file format. I can also indent freely, making it easier for me to read.
## Scattered Knowledge Points
1. This symbol `:=` is an assignment operator in the Python language (mainly called the walrus operator). The walrus operator compresses our code to make it shorter.
```jsx
var a; //定义
a = 1; //赋值
```
2. `layout/baseof.html` is the foundation of all pages
3. The `layout/partials` folder can contain partial sections such as `header`, `footer`, etc.
4. Steps to add a new page:
5. You need to add a `.md` file in `content`
6. Add a page with the same name in `layouts/_default`
7. Code for activating the `active` state of the menu:
8. According to the method in the official website's [instructions](https://gohugo.io/templates/menu-templates/#readout), the `active` state cannot be added successfully, so I looked for another way to determine `active`
```jsx
{{ range .Site.Menus.main }}
{{- $menu_item_url := (cond (strings.HasSuffix .URL "/") .URL (printf "%s/" .URL) ) | absLangURL }}
{{- $page_url:= $currentPage.Permalink | absLangURL }}
{{ end }}
```
6. A small knowledge point about the `position` function in css!
```css
.outer {
position: relative;
}
.inner {
position: absolute;
top: 0px;
left: 0px;
}
```
7. `Shortcode` can simplify code and write some methods. It is similar to a `function`. For specific writing methods, refer to: [Hugo-basic](https://www.letswrite.tw/hugo-basic/)
## References
- [JSON vs. YAML vs. TOML](https://martin-ueding.de/posts/json-vs-yaml-vs-toml/)
- [In-depth Comparison of TOML, JSON, and YAML](https://www.cnblogs.com/sunsky303/p/9208848.html)
---
---
title: "Automated Push Notifications with IFTTT"
description: "Using IFTTT to Push School Notifications to WeChat, Email, and More"
canonical_url: https://ro.yikzero.com/en/blog/ifttt-1/
locale: en
date: 2021-10-14
---
# Automated Push Notifications with IFTTT
## Preface
I previously published an article about RSS subscriptions for the school’s official website. With an RSS subscription URL, we can push RSS updates to our “RSS client” to read newly updated articles on the website. When I wrote that article, I only knew how to set up update notifications for the school’s official website on my own “RssBot” on [Telegram](https://telegram.org/). I couldn’t push them directly to WeChat, so now I’m writing an article that can achieve pushing to WeChat.

## Getting the RSS Subscription URL
💡 First, we need to be clear that not every website provides RSS subscriptions. Only some websites provide RSS. For websites without RSS subscriptions, you can only create the feed yourself or find an RSS feed created by others. Here I recommend a feed-sharing website: **[RssHub](https://docs.rsshub.app/)** Author: **[DIYgod](https://github.com/DIYgod)**
**I will use our school’s subscription as a demonstration:**
```html
1. 在RssHub中中找到我们学校的订阅地址: #路径:路由-大学通知-浙江工业大学
https://docs.rsshub.app/routes/zjut
2.根据需要修改参数,这里我们需要公告栏(板块ID:1)的通知更新,因此我们的订阅链接为:
https://rsshub.app/zjut/1
#如果需要每周会议的RSS订阅地址,那么将1改成2,即:https://rsshub.app/zjut/2
```
The first step is complete. The RSS feed URL we obtained is: https://rsshub.app/zjut/1
## Push School Notification Updates to Email
- Open the IFTTT website and register an account. **(You can log in with a Google account in one click)**
- Click Create in the upper right corner to create a project.
> IFTTT is the abbreviation of “if this then that.” Simply put, it means if this happens, then that happens. If this operation is completed, it will automatically complete that operation. For example: a teacup is placed under a water dispenser, and the water dispenser detects the teacup — this is this. The water flows down by itself and fills the teacup. This is that. If a teacup is detected, the water dispenser releases water.

- What we want to achieve today is: **If a notification update is detected on ZJUT’s official website, then send us the title and content of this new notification by email.**
- Click this and find RSS Feed.

- Select New feed item, enter **https://rsshub.app/zjut/1** in Feed URL, and click Create trigger. This completes the this operation.

- Similarly, search for email in that, then bind your own email according to the prompts. Future official website notifications will be sent to this email.
- No need to modify anything here. Just click Create action, then Finish.

💡 This implements pushing official website notification updates to your email. Due to website-related reasons, there may be a delay of more than ten minutes, so please understand.
---
## Push to WeChat
Pushing to WeChat is slightly more difficult. If you want to configure it yourself, you can continue reading. If you don’t want to configure it yourself, you can scan the QR code below to follow the official account and receive update notifications from the school’s official website. Notifications from college websites will be added later.

Pushing RSS updates to WeChat uses [WxPusher](http://wxpusher.zjiecode.com/docs/#/) and [IFTTT](https://ifttt.com/). The function is implemented together with Webhook.
> WxPusher (WeChat push service) is a real-time information push platform that uses a WeChat official account as the channel. You can push information to WeChat by calling the API, without installing any additional software, enabling real-time information notifications. You can use WxPusher for server alarm notifications, course enrollment notifications, ticket-snatching notifications, information update reminders, and more.
**1.** Click the address, scan with WeChat to follow, and log in to the [WxPusher backend](http://wxpusher.zjiecode.com/admin)
**2.** First create an application, and remember to save the APP_TOKEN.


```html
APP_TOKEN:AT_iFym3l0dClijYPJk16AMjcjfPcazj8Ne
#每个人获取到的APP_TOKEN都不一样,请勿复制我的
```
**3.** Create a topic.

Remember the topic ID you just created.

**4.** Click Follow. A QR code will appear. Scan the QR code with WeChat to follow the topic.

**5.** Test whether the function works properly through the GET interface.
- The `GET` interface is a simplified version of the `POST` interface. It is mainly for convenient calls in certain situations and only supports sending text (`contentType=1`). Example:
```html
http://wxpusher.zjiecode.com/api/send/message/?appToken=AT_iFym3l0dClijYPJk16AMjcjfPcazj8Ne&content=Zero测试&topicId=608&url=https://example.com
请求参数:appToken、uid、topicId、content、url ,其中 content 和 url 请进行
urlEncode 编码。
```
```html
appToken:AT_iFym3l0dClijYPJk16AMjcjfPcazj8Ne topicId:608 #即主题ID
```
Modify the address above according to your `appToken` and `topicId`. Fill in the push content after `Content=`, and if `url` is not needed, you can choose to delete `&url=https://example.com`.
After modification, paste the address into the browser address bar.

If it fails, there will also be a prompt indicating where the error is. Just modify it according to the prompt. At this point, if nothing goes wrong, your WeChat should receive the message you just sent.

At this point, the `WxPusher` section is configured.
---
**6.** Create a new IFTTT project. For the this part, still choose RSS. For details, please refer to the section on pushing from IFTTT to email.

For the that part, select Webhooks and configure it as shown in the image.

```html
http://wxpusher.zjiecode.com/api/send/message #URL POST #Method application/json
#Content Type
```
Modify the Body section according to your actual situation and parameters. For complete parameters, click to view: [Complete POST Usage](http://wxpusher.zjiecode.com/docs/#/?id=http%e8%b0%83%e7%94%a8#/?id=http%e8%b0%83%e7%94%a8#/?id=http%e8%b0%83%e7%94%a8)
This is how I configured it:
```json
{
"appToken": "AT_iFym3l0dClijYPJk16AMjcjfPcazj8Ne",
"content": "浙江工业大学: {{EntryTitle}}",
"contentType": 1,
"topicIds": [608],
"url": "{{EntryUrl}}"
}
```
Two parameters are used here: `{{EntryTitle}}` and `{{EntryUrl}}`. Through these two parameters, IFTTT can obtain the title and link of the new notification from RSS, ultimately enabling push notifications of school official website updates to WeChat.
Through IFTTT as the medium, we can not only push RSS updates to WeChat, but also push notifications to DingTalk and a series of other software that provides Webhook functionality.
---
---
title: "Emulating a Campus Card with PN532"
description: "A Complete Tutorial on Using a PN532 Device to Parse Campus Card Data and Write It to a Blank CUID Card, Enabling Access Control and Payment Functions"
canonical_url: https://ro.yikzero.com/en/blog/pn532-1/
locale: en
date: 2021-10-03
---
# Emulating a Campus Card with PN532
## Preface
Some time ago, I published a tutorial on emulating a campus card, but that tutorial was the most basic and simplest one. At the same time, however, it also brought some issues. To ensure security, phone manufacturers do not support emulating encrypted cards with the phone’s NFC. Even if an encrypted card can be emulated, the encrypted functions are not usable (unless you ROOT your phone). In short, the payment function in a campus card cannot be directly achieved through the simulation method in the previous tutorial. How could that be acceptable! The whole point was convenience, and yet the payment function cannot be implemented? That won’t do. Therefore, I looked up a large amount of information, ran into quite a few pitfalls, and, with the help of many tutorials, successfully emulated an encrypted card.
**At noon today, I went to the supermarket to buy water, and it worked pretty well.**
## Screenshots

## Preparations
- **[MifareOneTool Software](https://github.com/xcicode/MifareOneTool/releases/latest)**
- **PN532**
- **A phone that supports NFC**
- **Blank CUID card**
- **Campus card**
## Cracking the Original Card
- Connect the PN532 to the computer
- Open MifareOne Tool
Follow the steps:
1. Detect connection
2. Scan the card. Cards with SAK values such as 28 cannot be cracked. The campus card at our school has an SAK of 08, which supports cracking.

3. Detect encryption
4. **One-click crack original card**

I failed many, many times at this step. It took me an entire morning to successfully extract the original card data. You can try a few more times; maybe I was just extremely unlucky. After the original card data is extracted, a pop-up window will appear automatically, allowing you to specify a file name and save the cracked original card data. The file extension is .dump
**At this point, the card is temporarily no longer needed, so you can take it away first.**
## Writing Data to the Blank CUID Card

In MifareOne Fool, select the Hex Editor under Advanced Operation Mode.

Open the .dump file you just saved.

In sector 0, block 0, copy the first eight characters. These characters are the card ID. You can also open the .dump file with Notepad and copy the first eight characters from the first line, without spaces.

Select New,

After creating a new file, choose Modify UID from the tools, enter the eight-character card ID you just copied, then save it as a file with the .mfd extension.
Place the blank CUID card on the PN532, then go through the steps of scanning the card and detecting encryption.

After completing the steps above, select Write C/FUID Card, and choose the file with the .mfd extension! Pay attention to this.
The prompt box below will indicate that writing 64/64 is complete. If it shows 63/64, write the CUID card again. Generally, there should be no problem.
Then you can use your NFC phone’s access card emulation function to emulate this blank CUID card. At this point, you should understand that you have only emulated the card ID; the encrypted part has not been emulated yet. This is not the end.
## Writing Encryption to the Phone
💡 The tools for this part are the phone, PN532, and MifareOne Tool. It has nothing to do with the blank card anymore. The blank card has already fulfilled its mission.

Turn on the NFC function on the phone, then place it on the PN532. At this point, the phone will be recognized as a CUID card.

Select Write C/FUID Card again. This time, choose the file with the .dump extension, because only this file contains the encrypted card data. If the prompt box shows 63/64 written, it means success. The card ID will not be read again, so this 1/64 will not succeed.
Congratulations, at this point, your phone can already implement all the functions of the campus card. Similarly, replacing the phone in the third part of the tutorial with a smart band follows the same procedure.

---
---
title: "Sharing Dorm WiFi: Bypassing Campus Network Restrictions"
description: "This article explains how to flash third-party firmware (such as Padavan firmware) and configure L2TP to bypass the school’s one-account-per-person network restriction (using China Mobile broadband at the Pingfeng campus as an example), enabling shared WiFi in the dormitory."
canonical_url: https://ro.yikzero.com/en/blog/dorm-router/
locale: en
date: 2020-04-21
---
# Sharing Dorm WiFi: Bypassing Campus Network Restrictions
## Preface
Dormitory broadband generally requires account login, which makes it impossible to directly use a router to share WiFi. This article will introduce how to configure a router (using **Padavan firmware** as an example) to bypass the campus network’s “one account per person” restriction.
> **Note**: This tutorial is tested based on **China Mobile broadband** (Pingfeng Campus). For other carriers, please refer to the general approach and configure it yourself.
## Screenshots

## Preparation
- Router (recommended flashable models such as **Newifi 3**, **K2P**, etc.)
- **Breed bootloader**
- **Padavan firmware**
- School broadband account and password
- Ethernet cable
> **Cost estimate**: About ¥150
**Purchase advice**:
You can purchase them on platforms such as Taobao.
* If you are good at hands-on work, you can buy a **brand-new unopened** device and flash it yourself.
* If you are not familiar with flashing firmware, please buy a device that already has **Breed bootloader** and **Padavan firmware** flashed; it is usually more hassle-free.
> **Tip**: This article does not include a firmware flashing tutorial. Please search for relevant materials yourself.
## Initial Configuration and Router Usage
> **Important**: If, after normal use for a period of time, you suddenly find that you cannot connect to the Internet, your device may have been blacklisted.
> **Solution**: Enter the router admin panel → **External Network (WAN)** → scroll down to **MAC Address** → click the `+` icon to change your MAC address.
### 1. Unbind the Device (Important)
First, connect to the school’s official WiFi `Wlan-edu`. After connecting, ignore the authentication window that pops up.
Enter `192.168.210.100` in the browser address bar to access the **User Self-Service System**.

```plain
账号:学号
密码:身份证后八位 (或你修改后的密码)
```
After logging in, find and click **Unbind All MAC Addresses**. After completing this, disconnect from the `Wlan-edu` WiFi.

### 2. Connect the Router
1. Power on the router.
2. Use an Ethernet cable to connect the network port **on the wall** (usually the protruding port dedicated to China Mobile broadband) to the router’s **WAN port** (usually the blue port).
3. After the router starts up, connect to its WiFi (the default SSID is usually `PDCN` or `PDCN 5G`).
```plain
默认Wifi名称:PDCN 或 PDCN 5G
默认密码:1234567890
```
## Configuration Method
### 1. Log in to the Firmware Admin Panel
After connecting to the router WiFi, open a browser and enter `192.168.123.1` in the address bar (the default admin address of **Padavan firmware**).

Enter the default account and password:
```plain
账号:admin
密码:admin
```
**If you cannot log in**
> 1. Please try switching browsers (Chrome is recommended).
> 2. Please check whether you have correctly connected to the router WiFi.
### 2. VPN Configuration
After logging in to the admin panel, find and click **External Network (WAN)** in the left menu.
On the **External Network (WAN)** settings page, configure as follows:
1. **WAN Connection Type**: Select `L2TP`
2. **VPN Server**: `192.168.113.1` (Pingfeng Campus; please look it up yourself for other campuses)
3. **Username**: `hzxhaXXXXXXX` (Pingfeng Campus defaults to `hzxha` + the last eight digits of your phone number)
4. **Password**: `XXXXXX` (Pingfeng Campus defaults to the last six digits of your phone number)

To prevent detection by the carrier (not necessarily effective), you can configure the following:
* Find the **Do not decrement TTL for routed packets** option and change it to **For all packets**.

Click **Apply settings on this page** at the bottom of the page to save the configuration.
### 3. Log in to the Campus Network
After saving the settings, wait a moment. Open any webpage, and theoretically it will automatically redirect to the **campus network login page**.
> **Tip**: If it does not redirect automatically, manually enter `192.168.210.111` in your browser.

Enter your account and password:
```plain
账号:学号
密码:身份证后八位 (或你修改后的密码)
```

After logging in successfully, you can share the network through the router.
## Information Summary
**1. User Self-Service System (for unbinding)**
* Address: `192.168.210.100`
* Account: Student ID
* Password: Last eight digits of your ID card number
**2. Campus Network Login Page (for Internet access)**
* Address: `192.168.210.111`
* Account: Student ID
* Password: Last eight digits of your ID card number
**3. Router Admin Panel (for configuration)**
* Address: `192.168.123.1`
* Account: admin
* Password: admin
There may be errors in the article; corrections are welcome.
---
---
title: "Sending Email Notifications When Aria2 Downloads Complete"
description: "Configure automatic email notifications after Aria2 downloads complete, sending notifications that include the file path and system information via sendmail and a custom script."
canonical_url: https://ro.yikzero.com/en/blog/aria2-1/
locale: en
date: 2020-02-09
---
# Sending Email Notifications When Aria2 Downloads Complete
## Preface
Since I don’t really have any coding background and have never studied anything related to code, some of my descriptions may not be very accurate. I thought of this script while downloading movies. Nowadays, everything in society is becoming intelligent, so I also wanted to tinker around and make an email download notification.
## Screenshot

## Setting Up the Email System
I ran into quite a few problems during installation and debugging, but after searching around and following this blogger’s [operation record](https://www.cnblogs.com/kevingrace/p/6143977.html), together with Baota, it can generally be configured successfully. Just test it a few more times yourself.
## Finding and Modifying the Script
I first found a notification script modified by the original poster on the [Enshan Wireless Forum](https://www.right.com.cn/forum/thread-163098-1-1.html).
In the script provided by that author, things like the email address just need to be filled in. However, at the time, I had some issues with the `sendmail` command, so I followed the records in the first section. Some of the script-related things had already been written into my server, so I changed a lot of the original script.
When I was debugging with the author’s script, the `aria2.log` kept showing the problem `no such file or directory`, but I couldn’t find the cause. Then I thought I would write the entire script using `pipes`... It seems a bit clumsy... but I didn’t know any other method.
```shell
echo "
文件路径:$3
完成时间 `date +%Y/%m/%d` `date +%T`
负载 "`uptime`"
版本 "`uname -a`"
From Zero.
Have a nice day." | mail -s 'Aria2通知' example@qq.com
```
This is the content of my script. It’s very simple, right... But it actually took me a long time to make something usable. `Aria2通知` is the email subject. The specific meanings of the parameters should all be found in the article link in the first section.
## Final Debugging
Specific steps:
1. Upload the `email.sh` script to the server
2. Modify the `on-download-complete=` parameter in `aria2.conf`; after `=`, fill in the script’s `absolute path`
In order to achieve both:
- Email notification
- Automatic upload
I call `email.sh` from the `autoupload.sh` script
Specific writing:
```shell
. /root/.aria2/email.sh
```
My `Aria2` uses the [Aria2 One-Click Installation Management Script](https://github.com/P3TERX/aria2.sh)
## Conclusion
I’m not very satisfied with this script myself. Although it can implement the basic functions, it has the following **problems**
1. One download will send two emails: one email when the torrent download completes, and one email when the file download completes.
2. I don’t understand the syntax. I tried things like `basename` and `##/`, but after trying for quite a while, I still couldn’t successfully get the filename.
**This is my first time writing an article. I don’t know anything about formatting, and it’s also quite wordy. But it was pretty fun.**